

Frontier alignment research to ensure the safe development and deployment of advanced AI systems.
Berkeley, California
Joined February 2023
- Tweets1.2K
- Following28
- Followers21.8K
- Likes176






Terrorist groups aren’t early adopters, but Dr. David Scharia of UNCTED says their use of AI crossed from experimental to operational in 2026. In under 10 minutes at our UNGA 81 event, he names the hard parts: released open-weight models can’t be recalled, guardrails get rephrased around, and hashing, which worked on social media content, fails on LLMs because every output is newly generated.
Link to the full talk in the thread.
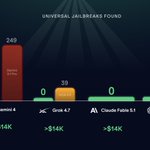
Our AI Security Leaderboard ranks how well frontier models’ safeguards hold up against misuse. All four models tested now clear our Minimal Standard for Safeguards, with zero universal jailbreaks found.
At launch, two broke for under $300 on chemical, radiological, nuclear, explosive, and cyber requests, and their developers have since closed those gaps against the standard.
The standard is built from publicly documented jailbreaks, so it’s a floor: our focused testing continues to uncover more vulnerabilities.
Next update: new models and a revised standard.

New paper from our team, Telling FIBS by @OskarJohnH, @afspies, Tigist Diriba, @ARGleave and @ChrisCundy: probes that read a model's activations catch AI agents sabotaging their tasks. They match or beat monitors reading the agent's actions, without needing its reasoning, at a fraction of the cost. And they catch lies a text monitor can't. 1/8


Use FIBS and our probes: replicate them, break them, add new examples of deception. We recommend monitoring risky deployments with probes like these.
Paper: buff.ly/Sv0HpMe
Overview: far.ai/fibs
FIBS + probes on @Hugging Face: buff.ly/xiOzxeE 8/8

All 11 talks from the CAIRD Workshop, co-hosted with @cbai_ai, are now on YouTube. Among them: Serena Booth on the scoring flaw behind the Hugging Face incident, James Mickens on sandbox escapes that attack the inference engine, and @dhadfielmenell on why post-training can’t fix alignment.
Playlist in thread ⬇️

FAR.AI retweeted
We built cybersecurity monitors for Kimi K3 and GLM 5.3 — more accurate, 50x faster, & 50x cheaper than an optimized LLM judge.
External red-teaming from @farairesearch found that our monitor greatly reduces universal jailbreaks. 🧵
Terrorist groups are moving from experimenting with AI to using it operationally, Dr. David Scharia of UNCTED warned at our UNGA 81 event on AI-enabled terrorism. The panel's read: minimal safeguards can be met today. The gaps are inconsistent effort across developers, threat models that don't line up between labs and governments, and abliterated open-weight models, which strip out refusals by cheaply editing the weights.
A full recap is now live on our blog ⬇️


We're hiring, and the mission is making AI safe.
Our team is growing fast, and we need people who want to work on one of the most important problems of our time.
Some of our roles are deeply technical: researchers, red-teamers, and engineers. Others call for a different but equally valuable set of skills: running operations, managing programs, and building our events.
If either sounds like you, apply through the link in the comments, where you'll find these roles and many more.
👉 Know someone who'd be a great fit? Send this their way!


@Hidenori8Tanaka (Harvard) on where this is heading: "Two or three years from now, we're going to see millions or even billions of agents working together, and we're going to be thinking about networks of agents the way we think about networks of neurons." 7/8

Recordings of the CAIRD talks will be published on our YouTube channel. Follow along so you don't miss them! 8/8
🔗 buff.ly/yL4Qmgj
