

Building Neotoma, the system of record for AI agents, and Ateles, an operating system for agentic organizations.
Barcelona, Spain
Joined November 2007
- Tweets5.6K
- Following3.7K
- Followers6.2K
- Likes6.4K






Pinned Tweet
Autonomous agents need a system of record alongside memory.
As agents move from answering questions in chats to acting across tools, people, and time with shared facts at scale, a human cannot verify every value before the next step.
An outdated value can drive a cascade of wrong actions before anyone notices.
Memory helps agents recall and find context. A system of record answers a different question: what values are current, and what observations and sources support them?
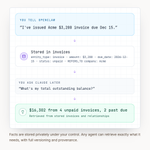
Neotoma gives connected agents one place to write observations and read current values computed by field rules. Each current field can be traced to the observation that set it while earlier observations stay on record. The same records are available across connected tools and sessions.
The long-term ambition is a shared understanding people and agents can govern together, with explicit authority, retained disagreements, and explanations of why any given value holds.
I wrote about the category shift, the capabilities available now, and what's coming in the future:
markmhendrickson.com/posts/y…

A shared system of record becomes useful when a second agent can pick up the first agent's work.
Start with one workflow whose facts and entities belong together. Have one agent store them in Neotoma, then have another read them from a different tool.
Both tools need to reach the same configured instance and data profile or MCP entry. Inspect the observations and sources behind the fields as part of the handoff.
This tests whether the shared records actually support the work across sessions. The system helps when the agents write to it and read from it.
The essay explains the current-value rules, source trail, and retained observations behind that test:
markmhendrickson.com/posts/y…
A correction is easier to inspect when the earlier observation remains available.
Neotoma stores a correction as another observation. The current value can change while the previous value and its source stay in the record.
That lets a reviewer examine what changed rather than seeing only the replacement. You can also read one entity as Neotoma had it recorded at an earlier time.
That earlier view describes the system's recorded state then. It does not reconstruct everything that was true in the world.
Keeping the earlier evidence matters when you need to check why an agent worked from a value that has since changed.
The latest document does not necessarily supply every current value in a record.
A new source may change one field while leaving the others intact. Treating the whole record as though it came from that source loses the distinction.
Neotoma identifies the observation that supplied each current field. Each stored observation links back to its source.
A reviewer can therefore check a particular value against the evidence that introduced it. The trail does not establish that the value was extracted correctly. It shows where to look when an agent's next action depends on it.
A stored fact should not need a fresh model judgment every time an agent reads it.
A model may interpret a source and write an observation. Neotoma then applies field rules to the stored observations to compute the current record.
Given the same observations and the same rules, it produces the same snapshot. New evidence or changed rules can change the answer. Reading the record does not ask a model to choose again.
That gives agents a repeatable starting point for reasoning. It also separates two things worth checking: whether the observation was correct and how the rule used it.
Mark Hendrickson retweeted

Give an agent a stale fact and enough authority, and you can automate a very expensive misunderstanding.
Shipping agents into regulated environments at Bottega8 has made me stubborn about a few questions: What is this system treating as true? Where did that value come from? What changed since the last decision?
Those questions get more consequential when several agents are working across the same business. For example: a customer record gets corrected. One agent picks up the change; another carries on with yesterday’s version. Both follow their instructions. The business then inherits the contradiction and a versioning mess.
This is why @markymark and I's collab with Neotoma matters to me: a shared record of observations, explicit rules for deriving current values, and the ability to trace a value back to the observation that established it. There is something concrete to inspect when a decision needs explaining.
That is one part of the infrastructure behind trustworthy autonomy. Alongside evaluations, permissions, and human oversight, it helps us answer the question every operator eventually faces: how much responsibility can we confidently hand this system?
The financial case for agents gets more credible when we can account for what drives their actions.
Worth reading if you’re building them or being asked to approve the investment.

An autonomous agent can act on an outdated fact before a human notices it.
As work spans tools and sessions, checking every value by hand becomes a bottleneck. A system of record gives connected agents a shared place to read what is current and inspect the evidence behind it.
Memory helps an agent find context. The next action also needs a recorded answer to which value applies now.
Neotoma computes current values from stored observations using field rules. That does not guarantee the observations are correct. It gives agents a consistent basis for action and people a specific place to check.
An autonomous agent can act on an outdated fact before a human notices it.
As work spans tools and sessions, checking every value by hand becomes a bottleneck. A system of record gives connected agents a shared place to read what is current and inspect the evidence behind it.
Memory helps an agent find context. The next action also needs a recorded answer to which value applies now.
Neotoma computes current values from stored observations using field rules. That does not guarantee the observations are correct. It gives agents a consistent basis for action and people a specific place to check.
Mark Hendrickson retweeted
Announcing what we've had a pleasure iterating and incorporating into our agent swarms and regulated industry deployments with @markymark. Congrats!
Autonomous agents need a system of record alongside memory.
As agents move from answering questions in chats to acting across tools, people, and time with shared facts at scale, a human cannot verify every value before the next step.
An outdated value can drive a cascade of wrong actions before anyone notices.
Memory helps agents recall and find context. A system of record answers a different question: what values are current, and what observations and sources support them?
Neotoma gives connected agents one place to write observations and read current values computed by field rules. Each current field can be traced to the observation that set it while earlier observations stay on record. The same records are available across connected tools and sessions.
The long-term ambition is a shared understanding people and agents can govern together, with explicit authority, retained disagreements, and explanations of why any given value holds.
I wrote about the category shift, the capabilities available now, and what's coming in the future:
markmhendrickson.com/posts/y…
Nadella argues that controls over agents must sit outside the model. The same applies to memory. If an approval is revoked, a later summary must not restore it. The record needs provenance, explicit corrections, and state we can reconstruct.

I'll be on the ground at @AISummitBCN tomorrow and Wednesday in case anyone wants to meet up and talk tech: aisummitbarcelona.com/

Nadella argues that AI inverts Arrow's "information paradox". The LLM buyer now gives away knowledge in order to use what they bought effectively.
I would add the upstream half. AI absorbing the execution middle is what forces the judgment out of your team's heads and into writing in the first place. The rubric only exists because the human translator in the middle is gone.
That is the bill. Your standards become legible so your team can use them with AI, and that legibility is also portable to whoever runs the model.
The fix is not a better vendor agreement. Judgment should accumulate in a store you own and any model can read, including a local one when the stakes demand it.
I wrote about the organizational side in April: markmhendrickson.com/posts/s…

A new @futurism piece documents bosses using ChatGPT to make every call, including who to fire. It reads as a case study in getting the shift exactly backwards.
I wrote a series arguing that when AI absorbs the execution middle, human value moves to the two ends: setting standards upstream and exercising judgment downstream. These managers saw execution get cheap and assumed judgment did too. So they automated the wrong part.
The specific failure is that a chatbot agrees with whoever is prompting it. One worker in the piece calls their boss's AI a "digital priest" that just confirms decisions already made. A model that only validates you is not a reconciler but merely a mirror.
That is what written rubrics and human review are for. The article is what happens without them.
The piece, by @mags_h11: futurism.com/artificial-inte…
My series on where the leverage actually moves: markmhendrickson.com/posts/s…

Building on structured agent memory taught me one thing above all: it compounds. The better the memory gets, the more any agent can do with it, and that never tops out. Every gain in what my agents can remember and resolve is a gain in what they can actually accomplish.
That is also what created my next problem. As the memory got richer, one agent working one session at a time could not act on everything it now held. The context all lived in one place, but I did not. I became the constraint, paying to switch between building my product, marketing it, and keeping up with the people using it, one session at a time.
A single general-purpose agent did not fix it either. Ask one agent to hold every rule and every role at once and it holds none of them evenly. It drafts the email well and forgets how you sign off. It fixes the bug and skips the test. Worst of all, it reviews its own work, so nothing catches it when it is confidently wrong.
So I built a swarm: a standing fleet of agents, each with one role, running every day. The part that matters most is that the swarm is defined in the same store its memory lives in. Every agent, relationship, task, and plan is an entity in Neotoma. Changing how an agent behaves is a database correction, not a redeploy. Every action is signed with its own identity, so I can trace who did what, replay it, and reverse it.
The memory and the swarm rise together. Every gain underneath lifts everything on top.
markmhendrickson.com/posts/t…
What compounds fastest in your setup, and what caps it?


I've arrived at the same data foundation from both ends:
1. Building agent-first state / memory from the bottom, and
2. Running my own company (and personal life) on it from the top.
Both ends land on the architecture you describe, except for one key primitive.
A unified filesystem of Claude Code + Codex chats still gives you blobs on a timeline. The queries that matter (e.g. which decisions touched this, how were they grounded, and which got rolled back) need append-only observations, provenance chains, and derived state you can recompute.
Files won't cut it – you need another layer for comprehensive "truth".
That layer also answers your adoption skepticism. A truth layer does not replace Datadog, PostHog, Drive, Slack, or the agent logs.
It ingests their unstructured exhaust and structures it into a semantic model of the company itself, typed entities and relationships, where every derived fact keeps a provenance chain back to the source it was extracted from. You can ask not just what the company knows but how it knows it.
The businesses you predict, built on this foundation, are already starting to exist. Mine runs on it today.
The company is an parent node in its own store, with strategies, releases, competitive analyses, call transcripts, people, and the agent workforce hanging off it as one queryable graph – w/ humans and agents as the same kind of child node.
Building it as Neotoma: neotoma.io


Increasingly, I believe companies may need to be rebuilt from the ground up, where you have a single timeline of all observability + product metrics + file changes laid out in a retrievable system, like Datadog + Posthog + Google Drive + Slack (really unified filesystem of Claude Code chats + Codex chats). This might be the new data foundation for any and all companies to maximize AI. Needs to be rebuilt because keeping track of diffs on existing system basically impossible to produce longitudinal information on decisions and rollbacks, something coding agent storage companies are actively trying to figure out, but this should extend to businesses as a whole.
Highly skeptical existing businesses will adopt this though because it means overhauling everything about their instrumentation and business data, but I think businesses built on this foundation probably can execute 100x better and faster
Earlier this week, @addyosmani, @mvanhorn, and @RLanceMartin published three separate essays that reach the same conclusion: with coding agents, the loop is the new unit of work, and durable state is what makes a loop a loop.
Osmani calls the state "the spine of the whole thing."
Then all three hand that job to essentially a text file, represented variously by a markdown file, a Linear board, git-backed state files, or a mounted filesystem.
Those substrates solve persistence. None of them solve integrity: which of two contradictory notes is true, who wrote it, when, and whether it was ever verified. Applications hit the same wall fifty years ago, and it is why databases replaced flat files.
The sharpest evidence is in Martin's own benchmark: on the same filesystem substrate, verification coverage ranged from zero to 73 percent depending on the model. Memory quality should be a property of the substrate, not a benchmark of the model.
I wrote up what loop state actually requires once you run more than one loop:
markmhendrickson.com/posts/t…

The WSJ ran a recent piece on chatbot memory going wrong. Worth reading.
A chatbot that learned about a user's divorce kept bringing it up in schedule planning and work conversations. A health question asked for a child got stored as the user's own condition. A weight-loss goal surfaced as diet advice during vacation restaurant recommendations.
One user's fix: split his life across separate chatbots, anonymous mode for anything sensitive. That's the workaround when your memory layer has no correction mechanism, no versioning, and no way to scope what each agent sees.
Every symptom maps to a missing primitive: no provenance, no entity resolution, no way to correct one stored fact without side effects. The problem isn't that chatbots remember. It's that they can't tell you where a memory came from, can't tell your data from someone else's, and can't let you fix one fact without wiping the rest.
The feedback I keep hearing from people building with agents matches exactly: memories bleeding into the wrong context is a core irritant. The fix is scoped access — different agents for different purposes, each seeing only what's relevant. One global namespace per user is the wrong default.
wsj.com/tech/ai/ai-memory-cd…

"The repo can sync through GitHub, but the project's memory does not."
This is the whole problem in one line. A file syncs; memory doesn't.
Each agent re-infers what it knows from its own context window — "Acme Corp" one session, "ACME CORP" the next — and nobody can answer what the agent knew last Tuesday.
The fix isn't a better file. It's structured state underneath, shared over MCP: versioned observations, provenance, one canonical entity.
I run OpenClaw, Codex, and Claude Code against one Neotoma graph for exactly this.


LLMs aren't lying, they're improvising.
When you ask one to form a narrative, fabrication is the default mode unless you pin it to a grounded memory of verified facts.
The new NYT piece on "The Future of Truth" by @magnifymedia containing AI-invented quotes is the canonical version of this failure.
Creative tasks need the tightest guardrails, not the loosest. Recall without grounding isn't memory — it's narrative.

Breaking News: Steven Rosenbaum, the author of “The Future of Truth,” acknowledged that the nonfiction book about the effects of A.I. on truth included misattributed or fake quotes concocted by A.I. nyti.ms/4wE8ssc
