
Run LLMs fast at any scale 🔗 https://xitter.cf/t.co/F3u6wYESL0 Join our community https://xitter.cf/t.co/fmlOfTOEec For AI tech blogs & deep-dives 👉 @lmsysorg
Palo Alto
Joined May 2025
- Tweets544
- Following55
- Followers11.5K
- Likes444





Pinned Tweet
Today, in close collaboration with @awscloud and alongside the TorchNeuron launch, we’re announcing the beta of the SGLang AWS Trainium plugin, built on TorchNeuron and running on Trainium2 and Trainium3.
What’s in the beta:
- Inference serving and RL rollouts
- Support for Qwen3, DeepSeek, and GLM model families, with more frontier models on the way
- Early preview of heterogeneous RL, with rollouts on Trainium and training via Miles (@radixark)
Stay tuned for more at the SGLang Summit next month!

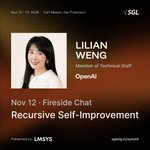
We’re excited to welcome @lilianweng to SGLang Summit for a fireside chat on Recursive Self-Improvement!
She’ll explore how AI can help build its own successors, what it takes to make that work, and where the process runs into limits.
If you’ve followed her writing on Lil’Log, come hear her live on Nov 12. We can’t wait to see you there!
🗓️ Nov 12-13
📍 Fort Mason, SF
🎟️ Get your pass: sglang.io/summit

ALT A poster announcing Lilian Weng's Fireside Chat at SGLang Summit. The topic is Recursive Self-Improvement
Want to try it out? Beta sign-up is here: docs.google.com/forms/d/e/1F…

Read the full blog: lmsys.org/blog/2026-10-22-sg…

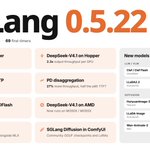
SGLang v0.5.22 is out! 950 PRs from 245 contributors, including 69 new contributors 🧡
Some of our favorite updates:
- InstantTensor brings up to 10x faster weight loading
- DeepSeek-V4.1-Flash gets up to 2.3x output token throughput on Hopper
- Up to 2.1x faster decoding on GLM-5.3, with decode context parallelism with MTP
- PD disaggregation gets up to 27% more throughput and half the p95 TTFT on agentic tasks
- MiMo-V2.6-Pro gets 1.85x decode throughput with DFlash
- Apple Silicon Macs can now use the standard PyTorch/MPS backend alongside MLX
- SGLang Diffusion now supports community GGUF checkpoints and LoRAs on ComfyUI
New models include Clef / Clef Flash, PPLX-Decider v1 / v1.1, EmbeddingGemma 2, LLaDA2.2, HunyuanImage-3.0-Instruct, Kandinsky 6, SANA-Video 2.0, and more.
Full release notes: github.com/sgl-project/sglan…

Thanks @MiniMax_AI 🙌 SGLang Omni keeps the LLM stage pluggable, so M3.1 Flash drops straight into the cascade next to local ASR and TTS. Add streaming and playback-aware interruption handling, and you get voice agents people can talk over. Full blog here: sglang.io/blog/omni-interact…


MiniMax M3.1 Flash + SGLang Omni: building toward a more interactive generation of voice agents. The shift ahead is from “ask, wait, listen” to conversations people can interrupt, correct, and redirect as a task unfolds.
MiniMax M3.1 Flash brings intelligence and fast, concise responses. SGLang Omni adds streaming, conversation state, and interruption handling so users can redirect conversations in real time.
Together, they give developers a foundation to explore proactive tutors, support agents, and hands-free copilots - pairing Flash’s capabilities with infrastructure for continuous interaction.
Thanks to the SGLang Omni team for exploring this direction with M3.1 Flash! ✨

SGLang has Day-0 support for Flint from @Recursive_SI
Flint is a 40B MoE built for fast, local agentic coding. It leads its class on SWE-Bench Pro v2 and Terminal-Bench 2.1. Recursive's Eureka Machine, an automated AI research system, designed its sparse shape, low-bit training, and kernels.
Flint runs fast on your own machine, keeping your code local, even offline. Run it on DGX Spark with our cookbook recipe 👇


Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine.
• Best-in-class fast local coding
• Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark
• Built from scratch in under 4 months
Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.

Today we launch SGLang-TorchTPU, built with @Google TPU team and Meta @PyTorch team.
We’re excited to see it powering production inference at Meta!
SGLang-TorchTPU is a TPU plugin for SGLang that brings:
- Top open models on TPU: Muse Spark Open, GLM-5.3 Flash, Kimi K3, Ling 3.1 Flash, MiniMax H3
- SGLang’s production features for large agentic workloads
- Custom MegaKernel: Muse Spark Open hits 770 tok/s decode at bs=1 on InferenceX 8K/1K
SGLang-TorchTPU is available now: github.com/sgl-project/sglan…


Big day for the @PyTorch ecosystem at #PyTorchConf2026 🚀
We’re officially open-sourcing TorchTPU—enabling native, hardware-accelerated PyTorch execution across Cloud TPUs and custom infrastructure.
Here’s everything we launched to supercharge your training & inference workloads 🧵👇
goo.gle/4Bl0zdG

Read the full story on our blog! We also ran early RL training on TPU with Miles and TorchTitan, and the results are very promising 🪄
lmsys.org/blog/2026-10-20-sg…

@radixark is also opening a community TPU capacity pool, with free compute for developers who contribute to SGLang-TorchTPU.
Apply here: docs.google.com/forms/d/e/1F…

Day-0 SGLang support for Ornith-1.5-122B! 🚀
Built for coding and agentic tasks, now ready to serve with SGLang, including reasoning, tool calling, and 262K context configurations.
Thanks to the Ornith team for the collaboration and cookbook contribution!
Get started 👇
docs.sglang.io/cookbook/auto…


Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast
Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!!
Open weights under the MIT license.
Coding
✅SWE-bench Verified: 0.845
✅TB2.1: 0.813
✅CyberGym: 0.800
✅NL2Repo: 0.512
Agentic
✅HLE: 0.446
✅BrowseComp: 0.785
✅MCP-Atlas: 0.746
✅Toolathlon: 0.708
🤗Hugging Face: huggingface.co/ornith-ai/Orn…
We can’t wait to see what you build with Ornith-1.5-122B.

Congrats to @deepseek_ai on the launch of DeepInfer! 🎉
Great to see the engineering behind DeepSeek's production inference stack being open-sourced, and thanks for the shoutout to the SGLang community 🧡
We're especially excited about the work on large-batch and multi-GPU inference. Can't wait to dig deeper and bring some of these ideas into SGLang!

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

Specialized low-latency kernels now plug into SGLang. The @NVIDIAAI team ships theirs in sgl-nvidia-mega. The @AMD team ships theirs in sgl-amd-mono. SGLang handles the integration and falls back to its general path for uncovered steps.
Low-latency kernels for GLM-5.3, K3 and MiniMax M3 are in progress on both NVIDIA and AMD, along with stronger CI at the plugin interface. Check out the blog for details 👇

Introducing SGLang Low-Latency Mode, built with @NVIDIAAI and @AMD.
On DeepSeek-V4.1-Flash with DSpark, it delivers up to 1.38× P90 per-user token speed on NVIDIA GB300 (671 to 928 tok/s) and 1.56× on AMD MI355X (332 to 516 tok/s) in @SemiAnalysis_'s AgentX trace replay.
Highlights:
- NVIDIA: overlapping kernels cut decoder layer time from 96.8 to 68.4 µs
- AMD: 2 persistent kernels per layer replace dozens of small ones, with cross-GPU communication overlapped inside them.
- New plugin system: custom kernels plug in from external libraries, with automatic fallback.
- Low-latency kernels for GLM-5.3, K3, and MiniMax M3 are in progress and will plug in next.

SGLang-Omni supports @TheInclusionAI's Ming-3.0 on day 0!
🎙️ Ming-3.0-asr-tiny — Chinese/English ASR with dialect support
🔊 Ming-3.0-tts-tiny — voice cloning in 7 languages
🧠 Ming-3.0-audio-flash — 126B-A6.5B MoE for audio understanding and reasoning
Cookbooks👇

Congratulations to @AntLingAGI for another awesome release! Check them out on Hugging Face:
huggingface.co/inclusionAI/M… huggingface.co/inclusionAI/M… huggingface.co/inclusionAI/M…

Cookbooks for all three:
Ming-3.0-asr-tiny: sgl-project.github.io/sglang…
Ming-3.0-tts-tiny: sgl-project.github.io/sglang…
Ming-3.0-audio-flash: sgl-project.github.io/sglang…
Proud to welcome our newest sponsors to SGLang Summit.
In just one week since our public announcement, our sponsor lineup has grown from 11 to 36. Thank you to every sponsor helping bring this community together.
Join 2,000+ engineers, researchers, and builders from across the AI ecosystem for technical sessions, hands-on workshops, and the GPU Expo.
Hear from Lip-Bu Tan, Lilian Weng, Soumith Chintala, Aravind Srinivas, and more. Meet the teams building across AI hardware, infrastructure, models, and applications.
🗓️ November 12–13, 2026
🌉 Fort Mason, San Francisco
🎟️ Get your tickets: sglang.io/summit
