

CloudResearch is the leading participant-sourcing platform for quality research projects. Fast. Affordable. Accurate.
New York, NY
Joined April 2015
- Tweets2.8K
- Following381
- Followers2.2K
- Likes514




Pinned Tweet
AI agents are slipping into surveys, according to a new PNAS paper.
Keep your data human with Engage’s 100% accurate AI detection.
Book a demo now: bit.ly/Engage_Demo
#surveyfraud #onlineresearch #dataquality #AIResearch
Saving for retirement and spending those savings turn out to be very different skills.
In @Prudential 2026 Retirement Pulse, 86% of adults over 50 said they don't feel entirely free to spend what they've saved. More money doesn't change much. Even among respondents with $500,000 or more in investable assets, 61% still don't feel comfortable spending for enjoyment.
@leib_litman, CloudResearch co-founder and Chief Research Officer, explains why on the Life & Longevity podcast. After a lifetime of building up savings, spending them feels like a loss. The habits that made someone a good saver keep running after the last paycheck.
Structure helps. Pre-retirees with a clear retirement plan were 56% more likely to feel comfortable spending on enjoyment, yet only 23% have one. So if you advise or market to this group, a plan may be the most persuasive thing you can offer.
CloudResearch fielded the study on Engage, pairing closed-ended questions with AI-moderated follow-ups so the reasons sit right next to the numbers.
Hear Leib explain it in the full episode.
Apple Podcasts: podcasts.apple.com/us/podcas…
Spotify: open.spotify.com/episode/4rA…
Read the recap: cloudresearch.com/resources/…

Today at 1 PM EDT, we share the Bot Olympics results with the Insights Association.
CloudResearch and @MIT turned state-of-the-art AI agents loose on leading survey fraud defenses. Some defenses held up and others did not.
AI agents get better at mimicking human respondents every few months. A defense that is not retested falls behind on the same schedule.
@leib_litman our Chief Research Officer, walks through the detection data, the red-team versus blue-team method behind it, and what to change in your own quality checks.
If you have ever looked at a suspiciously clean dataset and wondered who filled it out, the data will be useful to you.
Clean-looking data now comes with a second question attached: who produced it.
We think every research team should know how its fraud checks perform against current agents, and the Bot Olympics data is a place to start. Sentry is built from that work.
Free on Zoom. Register here:
us02web.zoom.us/webinar/regi…

A fraud vendor testing its own tool is a conflict of interest worth naming.
CloudResearch sells fraud detection. That’s why the Bot Olympics was run with @MIT, using AI agents built specifically to get past leading defenses, including ours.
An internal test tells you whether a tool catches the bots its builders imagined. An outside attacker tells you whether it catches the bots someone else built.
The second answer is less comfortable and more useful.
Few researchers would trust a study where the same team built the instrument, collected the data, and graded the results. Fraud detection claims deserve the same scrutiny as any other published method.
We think buyers should ask every fraud vendor, including us, who tried to break the tool and what happened. Tomorrow, @leib_litman our Chief Research Officer, will present the Bot Olympics results, including where defenses fell short.
Free Insights Association webinar, 1 PM EDT, Zoom. Register here:
us02web.zoom.us/webinar/regi…

A fraud defense improves fastest when someone on your own side is trying to break it.
That is the red-team versus blue-team model long used in security engineering. The Bot Olympics, run by CloudResearch and Massachusetts Institute of Technology applied it to survey fraud.
One team builds AI agents designed to complete surveys undetected. The other team builds and tunes the defenses meant to stop them.
Each round, the attackers find a gap and the defenders close it. Then the attackers look for the next one.
An agent can fail a check on Monday and pass it by Friday because someone adjusted its prompt. A static checklist never sees that loop, so it keeps catching last year's bots.
Data quality is a process that has to keep running, with an opponent built into it.
We think every serious fraud defense in research will need a standing red team, and the Bot Olympics is our attempt to show what that looks like in practice. Sentry is developed this way, and Leib Litman, PhD our Chief Research Officer, will share the detection data behind it.
Free Insights Association webinar, Tuesday, October 20, 1 PM EDT, Zoom.
Click here to register: us02web.zoom.us/webinar/regi…
#MarketResearch #SurveyResearch #DataQuality

Survey fraud defenses are usually tested against the fraud they were built to catch.
In the Bot Olympics, CloudResearch and Massachusetts Institute of Technology turned state-of-the-art AI agents loose on leading survey fraud defenses. The results show where current tools hold up and where they fall short.
Most data quality checks were designed around a human respondent who is tired, distracted, or rushing. An AI agent is none of those things.
It reads every instruction, passes the attention check, and writes an open end that sounds like a respondent on a good day.
The agents also improve every few months.
A fraud defense is only as current as the last thing it was tested against.
We think fraud tools should be retested against the newest agents on a regular schedule, the way security teams test their systems. In the webinar, Leib Litman, PhD our Chief Research Officer, will walk through the Bot Olympics detection data and what it means for Sentry and the rest of the field.
Free Insights Association webinar, Tuesday, October 20, 1 PM EDT, Zoom.
Click here to register: us02web.zoom.us/webinar/regi…

LIVE at #TMRE2026: The Astronauts have landed at Booth 613! 🚀
Our crew traveled long & far to show you how Persaud.AI can change your mind, and they brought a few exciting things:
🔨 Play Fraud Bash: your last game of whac-a-mole, thanks to Sentry x Verisoul
🍩 Enjoy fresh mini donuts from Yonutz!
🧑🚀 Grab your very own Engage plushie
Stop by the CloudResearch booth today!
#onlineresearch #marketresearch #FraudPrevention #ResearchInnovation #ResearchTech #mrX #Engage

Come see how Persuad.AI is changing the game in message testing. Find us at booth 613 at #TMRE2026 for live demos & donuts!
#MarketResearch #MessageTesting #ResearchInnovation

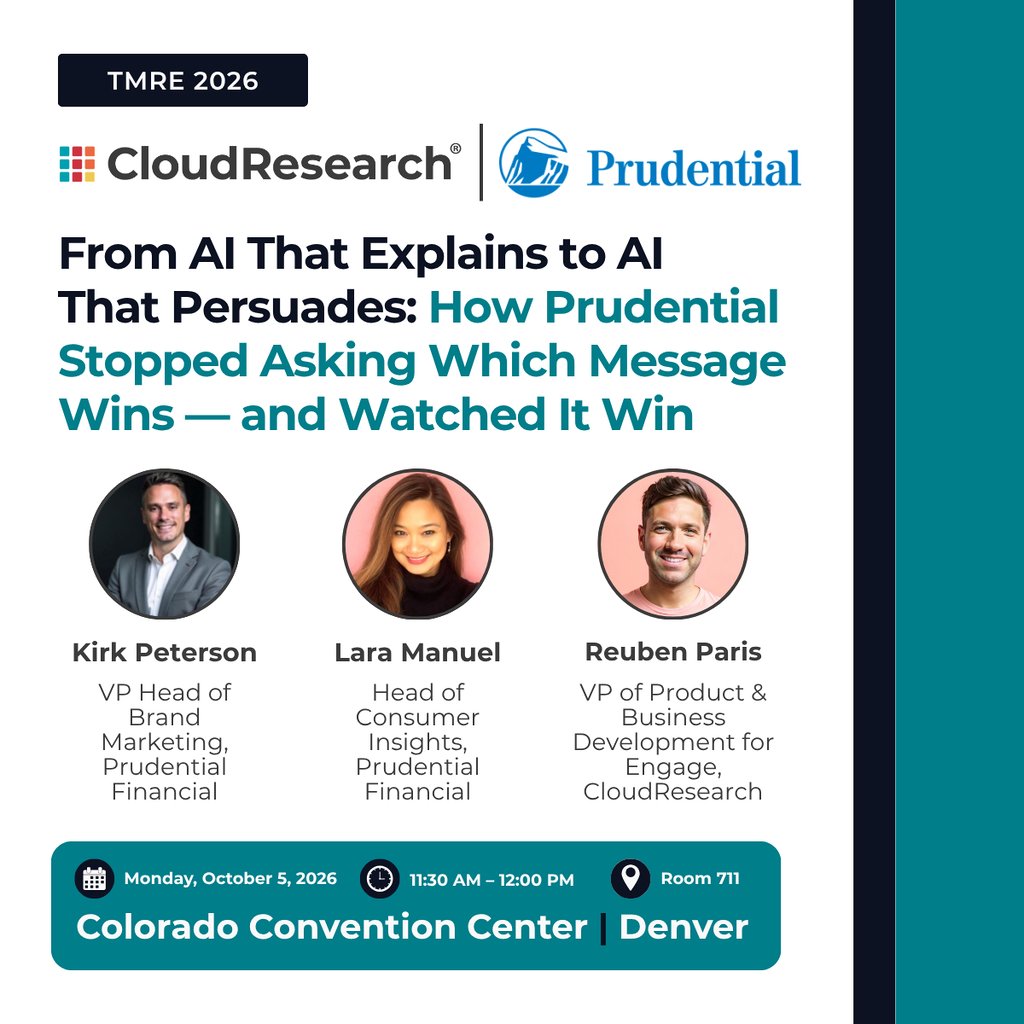
Everyone at Prudential agreed on one ad concept. The data disagreed.
Adaptive AI conversations revealed why, in consumers' own words, and gave Prudential the confidence to switch. The result: their best-performing ad in over five years (per Ace Metrix).
Then they used Persuad.AI to watch messages change minds live, turning 10,000+ participant ideas into 30 KPI-ranked themes that wrote the strategy itself.
Hear it all at #TMRE 2026, Monday, October 5, 11:30 am, Room 711.
#MarketResearch #ConsumerInsights #AdPerformance #MarketingStrategy
Booth 613 at #TMRE2026 has your new favorite research buddy. 👨🚀 Meet the Engage mascot, grab a donut, and see how Persuad.AI can change your mind!
#MarketResearch #mrX #Engage #onlineresearch

Come see Persuad.AI in action at #TMRE2026. Our conversational AI tool, Engage doesn't just measure reactions, it changes minds. Stop by booth 613 for a live demo and a sweet treat! 🍩
#MarketResearch #ResearchInnovation #DataInsights

What does it take to actually change someone's mind, not just measure their reaction to a message?
At #TMRE2026, our Chief Research Officer Leib Litman will share findings from four randomized studies with 3,327 participants, using AI-led conversations to go beyond traditional message testing. The research uncovers where messages hit resistance, what makes a claim credible, and how to turn objections into sharper messaging hypotheses.
Catch the session on Wednesday, October 7 at 11:25 am in Room 710.
See you in Denver!
#MessageTesting #AIResearch #MarketResearch #ResearchInnovation #Engage

⏰ Last call
Tomorrow, Leib Litman joins panelists from Verisoul, Potloc, Prodege, and KADRO to expose how survey fraud farms operate and how to detect them before they wreck your data.
If you own sample quality, panel management, or survey ops, this one's for you.
🕔 5PM CEST / 10AM CDT
Register here: linkedin.com/events/74814631…
#SurveyFraud #DataIntegrity #MarketResearch

We're headed to #APA2026 in Washington, DC, Aug 6-8. Find us at Booth 501. Modern psychology runs on online samples, and a replicable finding starts with real, attentive participants. Let's talk. #Psychology #DataQuality

AOM starts tomorrow. Find us at Booth 500 in Philadelphia July 31-Aug 4, plus our PDW on LLM pollution in online behavioral research. Come talk data quality with the team. #AcademicResearch

We're live at Quirks NYC. The team are at Booth 100 in the Javits today and tomorrow. Come grab a donut and let's talk quality data. And save time for the Bot Olympics tomorrow, 1:30 PM, Room 3. #QuirksNYC

We're headed to #AOM2026 in Philadelphia, July 31-Aug 4, Booth 500. We're also part of a PDW on LLM pollution in online behavioral research. If your studies run on online samples, let's talk. #AcademicResearch #DataQuality

3 days to #NCURA. Find us at Booth 36 in the exhibit hall Sunday and Monday, and stop by at 8:30am both mornings for donuts. Come talk data quality and research integrity. #ResearchAdmin

Survey fraud farms are scaling fast, using VPNs, anti-detect browsers, device farms, and AI to slip past traditional defenses and contaminate research data.
Join us in just one week for "Inside the Mind of a Fraudster: Fraud Farm Tactics and How to Detect Them," featuring Leib Litman from CloudResearch alongside teams at Verisoul, Potloc, Prodege, and KADRO.
We'll break down how modern fraud operations are built and scaled, then hear directly from teams protecting survey quality on the front lines.
📅 August 4
🕔 5PM CEST / 10AM CDT
Register here: linkedin.com/events/74814631…
#SurveyFraud #MarketResearch #DataQuality

AI agents are now good enough to pass as human survey respondents. That should worry anyone who trusts their data. At #QuirksNYC our VP of Product, Reuben Paris, is sharing the Bot Olympics: a $50K challenge, AI agents vs. detection systems. Room 3, Thu 7/30, 1:30 PM. #DataQuality

Our astronaut has landed in NYC ahead of Quirks. July 29-30 at the Javits Center. Come meet the team and pick up your very own Engage plushy. #QuirksNYC #MarketResearch
