





I cancelled my codex subscription to upgrade my Gemini subscription for neon and hydrogen. They are great!

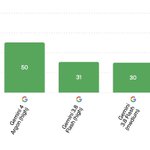
NEW: Gemini 4 Neon is the highest-performing model we've measured.
Not only is it the most intelligent model on our leaderboard, it's also up to 10x cheaper than the next best, reshaping the Pareto frontier of cost vs. intelligence on web research tasks.

4
439
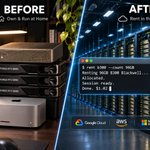
I used to think “local AI” meant buying the silicon. A DGX Spark. A 5090. A Mac Studio. The whole ritual of “I have to own the machine.”
Today my agent rented a 96GB Blackwell, installed vLLM, pulled a 55GB model, hit a launch error, fixed it, and tunneled the endpoint back to my desk. 20 minutes. $1. Zero hands on my side.
The hard part of self-hosting was never the GPUs. It was the ops. Agents just ate the ops.
So “local” isn’t about where the chips sit. It’s about who controls the weights, the logs, and the off switch.
You don’t need to own the metal anymore.


raullen retweeted

🚀 The powerhouse behind @PUBG, @KRAFTON_Inc, just dropped a massive win for on-device AI: Raon-1-nano!
It's a 3.2B open model (Apache 2.0) featuring a hybrid gated-delta + MLA architecture, native tool calling, and built-in thinking. 🔥
We immediately added native support to Rapid-MLX and pushed it to the limit on an M4 Pro Mac. The results absolutely blew us away:
🥇 97.9% accuracy — tied for #1 among small models!
⚡️ Blazed through our 95-question test in just 88s (vs 143–156s for typical 4B models).
🛠️ Thinking & tool calling work flawlessly right out of the box.
Merged to main today. Shipping in the next Rapid-MLX update. Your Mac is about to get even smarter. 💻✨

Heads-up for IoTeX delegates: IIP-59 only auto-migrated Hermes-vault delegates whose reward split was already set in their on-chain DelegateProfile.
I cooked up a simple script for you to migrate:
gist.github.com/raullenchai/…


IoTeX v2.5.0 (Zanzibar Hardfork) is officially out! 🌐
MainNet activation: Block 53,533,081 (est. Oct 19, 02:00 UTC).
This is a massive protocol upgrade that moves staking rewards fully on-chain, tightens EVM precision, and lays the security groundwork for our next phase of scalability.
Here is how it impacts the network:
🗳️ 1. Fully Decentralized Staking Rewards (IIP-59)
- The Tech: Voter rewards are now natively computed and distributed by the protocol itself at era boundaries (24 epochs).
- The Impact: Zero reliance on off-chain services (like Hermes). Staking yields are now 100% trustless and automated. We’ve designed this for a seamless transition—most Hermes-vault delegates with complete reward portions will be migrated automatically at the fork block.
⚡️ 2. EVM Precision & Gas Savings
- The Tech: Corrected GetCommittedState for absent prestates and fixed SELFDESTRUCT transfer-log amounts.
- The Impact: Strict compliance with EIP-2200 dynamic gas rules. For developers and users, this prevents massive gas overcharging on certain in-place writes (saving 2,800 gas per hit). For indexers and wallets, token balance histories reconstructed from tx logs are now perfectly accurate.
🛡️ 3. Proactive Security (BLS PoP)
- The Tech: BLS proof-of-possession is now enforced on candidate register/update operations.
- The Impact: This completely closes the rogue-key forgery window today, safely paving the runway for IIP-52 signature aggregation (massive network scalability) tomorrow. (Note: Providing a BLS key is now optional until IIP-52 is live).
🖥️ 4. Zero-Friction Upgrades for Node Operators
- The Tech: The hardfork heights and new contract addresses are baked directly into the binary.
- The Impact: No genesis replacements. No config changes. Just a pure, clean binary roll. 👉 docker pull iotex/iotex-core:v2.5.0 and restart.
Dive into the full technical details here: github.com/iotexproject/iote…

Gemini 4 Hydrogen is seriously impressive. My hands-on takeaways:
⚡️ Faster and noticeably smarter than Opus 5.5 in daily use.
🚀 On par with Fable 5.2 for my workflows, but consumes a fraction of the subscription quota.
🎨 Slightly higher hallucination rate—or rather, a lot more creative.
Overall, an absolute powerhouse of a model.

Google's new Gemini 4 Hydrogen has Intelligence just below Claude Sonnet 5.5 and GPT-6.1 Sol, at a third of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol
@GoogleDeepMind has released their third new model in six weeks. Gemini 4 Hydrogen introduces an xhigh reasoning level and scores 54 on the Artificial Analysis Intelligence Index, with strengths in visual reasoning and non-hallucination. This places it 1 point behind Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), at ~32% of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol. With high reasoning, Gemini 4 Hydrogen matches the Intelligence of Gemini 4 Argon for ~19% of the Cost per Task
Key takeaways:
➤ The new xhigh reasoning level scores 54 on the Intelligence Index: xhigh is the first reasoning level above high on a Gemini model, and puts Hydrogen 1 point below Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), and 4 points ahead of Gemini 4 Argon (high). With default (high) reasoning, Gemini 4 Hydrogen scores 51, just behind GPT-6.1 Sol (xhigh, 52) and Claude Opus 5.5 (high, 52)
➤ Strong visual reasoning, presentation and non-hallucination: On GDP.pdf, a visual reasoning benchmark over long documents, it scores 33% all-pass on medium reasoning, the tied #1 score on the benchmark. On AA-Omniscience, Hydrogen has one of the lowest hallucination rates recorded at 8%, compared with 43% for Claude Sonnet 5.5 (max) and 52% for GPT-6.1 Sol (max). On AA-Briefcase, our agentic knowledge work evaluation, graders rate Hydrogen's presentation above other Gemini models, including Carbon
➤ Weaker on agentic terminal work: Hydrogen scores 54% on Terminal-Bench 4.0 and 50% on Terminal-Bench-Science 0.1, covering agentic coding and scientific research workflows in the terminal. Claude Sonnet 5.5 (max) scores 64% and 53%, and GPT-6.1 Sol (max) scores 56% and 58%. xhigh reasoning helps on the science tasks, lifting Terminal-Bench-Science from 41% at high to 50%, but makes no difference on Terminal-Bench 4.0 (54% at both). Science scores are even across domains, from 46% in earth sciences to 53% in physical sciences
➤ Low cost for its intelligence, with high token use at xhigh: Hydrogen is priced at $1.50/$7.50 per million input/output tokens. At xhigh it costs ~32% as much per task as Claude Sonnet 5.5 (max) for near-equal intelligence, but ~2.5x as much as GPT-6.1 Sol (max). xhigh nearly doubles output tokens compared with high for a 3 point gain in Intelligence, and Cost per Task falls from $3.16 at xhigh to $1.87 at high. Medium ($0.80) and low ($0.29) cost less again, but score 41 and 27 on the Intelligence Index
➤ On the Time per Task vs. Intelligence Pareto frontier: Gemini 4 Hydrogen has an output speed of ~200 output tokens per second. With high, medium, and low reasoning effort, Gemini 4 Hydrogen is on the Time per Task vs. Intelligence Pareto frontier, meaning no models are both more intelligent and have a lower Time per Task
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Reasoning efforts: Gemini 4 Hydrogen offers four reasoning levels (low, medium, high, and xhigh) with xhigh new in this release
➤ Pricing: $1.50/$7.50 per 1M input/output tokens. Cached input tokens receive a 95% discount ($0.075)
Congratulations to the @GoogleDeepMind team on the launch!

Agreed. Based on my first 24 hours with HomeView, it's a completely disappointing product from the new Apple CEO.

Here is the best review for HomeView for y’all.
This thing is a joke. Siri is a joke. @johnternus how is this a great product?
Proud what we have done so far!

Rapid-MLX is now built into 6 tools you already use 🧵
🍒 @CherryStudioHQ: the 53k★ desktop AI chat app. Pick Rapid-MLX as a built-in local provider and chat with models running on your own Mac.
🔬 @askalphaxiv OpenResearch (8k★): turns coding agents into research agents. Run them on a local model through Rapid-MLX.
🧞 DevoxxGenie by @Stephan007: AI coding assistant for JetBrains IDEs. Rapid-MLX is a built-in local provider, so your code never leaves your machine.
🌳 Orchard: the native Mac app for Apple containers and MLX sandboxes. It auto-detects your Rapid-MLX server.
🍺 @MacHomebrew: the Mac package manager. One line: brew install rapid-mlx
🤗 @huggingface: the home of open models. The Hub docs list Rapid-MLX as an app that runs models straight from your local Hugging Face cache, with no re-downloading.

I am at SGLang Summit today, happy to chat if you are around!

Introducing Miles v0.2 at SGLang Summit!
With v0.2, we’re bringing production RL to your setup, expanding where teams can run RL and what they can train:
• More hardware choice: NVIDIA and AMD GPUs, early Google TPU support, and AWS Trainium landing soon.
• Stable on messy fleets: Reliable training with mixed GPUs, mixed precisions, and fully async rollouts.
• Broader workload support: Multimodal RL gets more exact, lighter, and faster across image, video, and audio. Diffusion training runs async, and Multi-LoRA shares one base model across jobs.
Thank you to our contributors and the teams building with Miles!


Whatever you think of this week's news, Jensen Huang's 33-year journey at NVIDIA is one of the most inspiring stories any founder can learn from:
- Pick the hardest problem. Survive long enough to be right. Keep betting the company on it when nobody else believes.
- NVIDIA's bet on accelerated computing took more than a decade to pay off. Most companies would have quit. That patience didn't just build the AI era; it moved humanity into its next one.
As an entrepreneur, he has my deepest respect.

NVIDIA announces CEO transition. Read the release: nvidianews.nvidia.com/news/n…

Congrats on the launch @hanghuang_!

Your laptop isn't built for running agents.
Introducing @instabox_sh: cloud computers for AI agents.
We provide multi-OS sandboxes (Linux, Android, Mac, Windows) with GPU and CPU.
We launched in beta <1 month ago, and today, users have created 1M+ boxes.
Give agents their own cloud computers so they don't fight over the same memory, CPU, and ports on your laptop.
Close your laptop, and they keep working.
Get started today → instabox.sh
7
562
An early Thanksgiving present from Anthropic! 🦃✨

We've given all Pro, Max, Ultra, and Team users one free full reset, across all models and limits. Use it anytime before December 10 at 2:00PM PT.
We recently fixed a few small issues that used more limits than intended, and the Fable resets didn't do much for those of you who'd already hit your weekly limits for all models. While these issues didn't affect everyone, we want to make up for the trouble.
You'll find it in Settings > Usage, or at clau.de/reset.
1
6
759
raullen retweeted

Claude Fable 5.2 is live on QuickSilver Pro 🚀
We gave it a failing test suite in Claude Code. 10 seconds later: root cause found, bug fixed, all tests green. It even caught a docstring mismatch we didn't ask about.
$2 / $10 per 1M tokens, 75% below Anthropic list.
raullen retweeted
🔥 The Rapid-MLX community benchmark is absolutely exploding! 710 runs, 119 contributors, and 20 different Apple chips covered in just 2 weeks. 🚀
But we are missing the final boss: the M5 Ultra.We only have 8 runs total, and absolutely ZERO data for the 512GB beast! 😭💔
Calling all M5 Ultra owners: we need you! 🙏 Help us complete the ultimate Apple Silicon tier list. It takes just one command, and your data stays 100% local.
No M5 Ultra? A quick RT helps us reach the heavy hitters who do! 🔁🙏
Join the squad and light up the leaderboard! 📊 rapidmlx.com/leaderboard

2026 is officially the worst year for crypto hacks in history—and we still have two months left.
$8.7B stolen. 326 incidents. That's more than any previous full year combined. Here is what’s actually happening under the hood:
📈 Frequency is exploding
Historically, we saw 12–18 hacks/month. In 2026? We're averaging 32.6, peaking at 48 in August. Even million-dollar+ hacks have doubled (59 → 117).
💰 The sheer size is unprecedented
Feb 2025 (Bybit): $1.4B was the record.Oct 2026 (Binance): $6.4B just shattered it.We’ve had SEVEN $100M+ hacks this year, five in the last 100 days alone.
🎯 The attack surface has shifted
Smart contract bugs aren't the main vector anymore. The new weak links are people and infrastructure:
• Engineer's laptops (Binance)
• Hijacked RPC nodes (Kelp)
• Tricked multisig signers (Drift)
• Tampered hardware (Ledger, Coldcard)
Because Crypto is permissionless, it has become the ultimate live-fire testing ground for AI cyber warfare. The real question isn't whether we've reached the tipping point of these attacks. It's this: once AI finishes practicing on Web3, what happens when it turns its sights on real-world IT infrastructure? 🌍


Q-day is approaching. ⏳
A Bitcoin dev just proposed "Quantum Landmines." While Bitcoin theorizes, @iotex_io is already building the bunker with IIP-65. 🛡️
BEFORE Q-Day, both share the exact same philosophy: Bind your assets to a Post-Quantum (PQ) key today, while legacy signatures are still safe.
AFTER Q-Day, the paths diverge entirely:
🟠 Bitcoin (Landmines): Forces true owners to post 1:1 BTC collateral to move funds. Brilliant, but massive economic friction.
🟢 IoTeX (IIP-65): 100% open and collateral-free.
Instead of an "economic tax," IIP-65 relies on pure cryptographic enforcement. This keeps our post-Q-day playbook completely fluid, e.g., one can freeze unsafe legacy transfers, while allowing PQ-guarded buckets to circulate safely and freely.


So proud of this release! My two personal favorite upgrades in 1.0.2:
- Local, synchronized Video + Sound powered by Pika H3 Flex.
- Zero-friction Hugging Face links—just copy-paste a link and let Rapid-MLX instantly serve it for you.
Give it a spin!
🚀 Rapid-MLX 1.0.2 is live. Local AI on your Mac just took a massive leap forward.
What’s new?
🎬 Local Video + Audio generation (Pika H3 Flex)
🛑 "Stop Generating" for video jobs
🔗 Paste Hugging Face links anywhere
⚡ 1.6GB hyper-fast first run
💤 Idle Unload (save RAM, keep API up)
Upgrade: `rapid-mlx upgrade`, or download the new DMG: rapidmlx.com/download
Notes: github.com/raullenchai/Rapid…
