

The Sovereign Ontology for Enterprise AI.
Joined November 2022
- Tweets166
- Following24
- Followers2.2K
- Likes457


Pinned Tweet
95% of Healthcare data lives in petabytes of SQL databases
The tools for AI to use that data haven't existed
Today we fix that with TextQL Healthcare
100,000+ tables. Trillions of rows. Petabytes of data. 15 minutes to insights. Epic systems with 100,000+ tables. Cerner environments. Claims databases. Clinical notes. Prior authorizations. Healthcare organizations have more data complexity than any other industry - and exactly zero AI platforms built to handle it.
Until now.
Here's what makes it different:
1. Direct access to ALL your systems. No migration required. Epic + Cerner + Claims + Snowflake + Databricks. Everything. At once. Other platforms: 6-month ETL projects. TextQL: Connect Monday. Query Tuesday. First insights in 15 minutes.
2. Healthcare-compliant execution environment. Autonomous agents running production code in SOC 2 Type II, HIPAA-compliant infrastructure. Full audit trails. On-premise deployment available.
3. Structured AND unstructured data. Simultaneously. Everyone else: Claims records OR clinical notes. Us: Both. At the same time. Make sense of 100,000s of tables without months of data prep.
We're not launching with pilots. We're launching with Lumeris - powering their Tom™ AI platform delivering care to millions of Americans. Live partnership. Production workloads. Enterprise healthcare data at scale.
Advisory Board of operators who've run organizations serving 120M+ Americans:
- Varsha Rao (former CEO Nurx, COO Clover Health)
- David Griffith (Trinity Life Sciences, ex-Pfizer)
- Sam Mohanty (former CDO, Prime Therapeutics)
- Jean-Claude Saghbini (CTO, Lumeris)
- Raghu Chandra (30 year EHR Veteran)
These aren't advisors. They're the people who built the systems we're now optimizing.
Meet us at HLTH Conference next week - Booth #4060
Or request a demo: textql.com/hlth-conference
Comment "HEALTHCARE" and we'll reach out for a customized demo!

View the full benchmark →
textql.com/decision-bench

TextQL retweeted

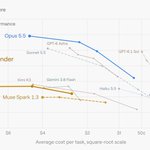
Introducing Decision-Bench, a new industry standard for measuring model capabilities in making ROI-positive decisions on messy enterprise data.
Every enterprise has slowed AI investments due to no ROI; AIs still fail at complex decisions, and pricing second order effects.


Yesterday, we launched Data Apps to all customers. Today, Aaron Zhu walks you through how to build a working Data App from a single prompt.
He shows how to build a data reconciliation workflow: a leasing intake portal that takes messy broker reports and uses an agent to validate them. The agent surfaces anomalies, brings in human input where needed, and writes clean, validated rows back to the warehouse.
This is just one example. In the blog post below, we're rounding up a few more data apps that impressed us, for inspiration.

Meet Data Apps.
We took what makes low-code and no-code app builders great: speed, no engineering bottleneck. And applied it directly to enterprise data.
The result: fully operational apps built in one or two prompts. Accurate. And fully enterprise-ready out of the box, with version control and RBAC built in, not bolted on afterwards.
We're offering free credits to Team and Enterprise organizations building their first three data apps. Try it today by describing what you want to build in a new chat. That's it.
Learn more about customer examples in our blog post below 👇


Enterprise data teams are still running modern data stacks like 1910s Detroit assembly lines.
@TheEthanDing, CEO, sat down with @petesoder of @ZeroPrimeVC to talk about why that model is breaking now, and what TextQL does differently: working directly on messy enterprise data instead of demanding clean inputs first.
The dirtier the data, the more this approach pays off. And because TextQL builds context over time, it gets cheaper with use instead of more expensive.
They also covered the question every data leader is quietly panicking about: AI is spiking warehouse bills exponentially. The old playbook does not survive contact with that math.
Thanks to Pete and the Zero Prime Ventures team for having us.