

ワールドモデルを作っています。創業メンバー募集中 / 株式会社未来予知 CEO←LLM無職←nocall株式会社CTO←明治大学←女装コンカフェ嬢(アイコンは本人)
Joined February 2022
- Tweets4.1K
- Following1.5K
- Followers2.4K
- Likes20.4K




Pinned Tweet
論文がワークショップ UniReps 2026 に採択されました🎉
ワールドモデルに興味を持った後、VLA やワールドアクションモデルが階層構造を持っているものの、それを統一的に学習する方法に関心がありました。早くて荒い推論と、遅くて正確な推論。脳の構造に近いこの2つを、一つのモデルの中でつなげて学習する必要があると考えたからです。
本研究では、上位モデルが「近い未来の潜在表現」を予測し、下位モデルがそれを中間目標として短い行動列を生成する階層方策を提案しました。
PushT では、学習範囲外の遠い目標に対して、平坦な方策より成功率が約20ポイント向上しました。
先行研究との差分としては、世界モデルによる計画も同様の分離を持ちますが、推論時に候補行動を探索(CEM など)するため推論が遅い。本方式は探索を行わず、単一の方策の中で1回の生成として動作します。
まさか採択されるとは思っていなかったので、素直に嬉しいです。
ワールドモデルに特化した新しい国際会議

Our first major update on icwm.cc
- venue confirmed in the heart of Manhattan
- paper deadline is December 22nd
- single-blind, free-form (just a page limit), use AI however you want--focus on the science
- everything public (openreview), < 3 papers per reviewer

10
348

文章も画像も「同じ生成の仕組み」で扱う『Multimodal Flow(MF-1)』が面白い。
どちらも連続表現に変換し、Flow Matchingで生成する研究
■どう生成するのか?
文章も画像も、ノイズから内部表現を少しずつ更新して生成する
・文章:8トークン分をまとめて更新し、完成したまとまりを条件に次へ進む
・画像:画像全体の内部表現をまとめて更新し、画像に戻す
重要なのは、文章用・画像用の処理を残しながら、情報をやり取りする自己注意と生成の枠組みを共通にしていること。
■結果は?
同じ学習データ・学習スケジュール・学習対象のパラメータ数で、Transfusion型のモデルと比較すると、
・画像生成のGenEval:0.669 → 0.713(約6.6%向上)
・画像理解のMMBench:33.68 → 46.74(+13.06ポイント)
・画像理解のSEEDBench:31.31 → 51.85(+20.54ポイント)
文章と画像の生成方式を分ける構成に対し、共通のFlow Matchingで画像生成・画像理解の両方が改善した。
論文:arxiv.org/html/2609.40362v1
5
551
森本🤟 retweeted

We’re introducing Shizuku-Duplex, the world’s first full-duplex audio synthesis model built specifically for AI characters. See how our models are built for natural human-AI interaction:
World Labsの世界モデルが試せるゲームボーイ風デモが面白い!
重い動画生成を""リアルタイムに""15fpsで推論してるし、ワールドの一貫性が高くてほとんど破綻してない

森本🤟 retweeted

Diffusion-Qwen3.8-27B is officially out.
I adapted Qwen3.8-27B into a masked diffusion language model. The prompt stays fixed, and generation starts with a sequence of masked tokens. On each pass, the model predicts multiple missing tokens in parallel and commits those that meet a confidence threshold. The next pass uses those tokens as context to resolve more of the response.
To support this, I removed the causal mask from the full-attention layers so each position can use context on both sides. The Gated DeltaNet layers scan the sequence in both directions, with a learned gate controlling how much the reverse scan contributes.
This is a research checkpoint. I haven't benchmarked its accuracy or generation speed against the base model yet. One possible failure mode is an early, confident mistake. If the model commits to the wrong word, later passes can build a fluent but incorrect answer around it.
The weights, code, and a generation example are public. If you hit a failure, please share the prompt, decoding settings, and raw output so I can reproduce it.
huggingface.co/summerAIO/Dif…
AIRoAさんってモデル作ってるんだ
すごっ!!

もうすでに宣伝されてますが。
AIRoAとしてのオープンな基盤モデル"A-0"を公開しました。
Yubiで収集した16,000時間以上のデータで学習しています。ロボットハードウェアを選ばずに利用できるのが特徴です。
CoRL2026で発表する成果などを導入し、他のオープンモデルと比較して高いパフォーマンスを示しています。
a-0.airoa.io/

2
390
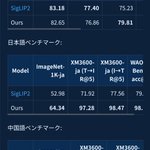
日本語・中国語ベンチがめっちゃいい!!すご!!!!!


初回の記事では、国産マルチモーダルLLMの開発に向けて、画像エンコーダーをゼロから構築した取り組みを紹介しています。
📄 「SigLIP2に匹敵する画像エンコーダーをフルスクラッチで開発した話」
zenn.dev/noetra_techblog/art…
ぜひご覧ください。
#Noetra

5
1,064

森本🤟 retweeted

Trained the FPM + locomotion policy inside a world model, SuperMimic-style, on my 4070 Super. Far from perfect, the force assistance curriculum didn't carry over, but sparse terrain success surprised me. Not sure about deploying such a policy, but the direction is very promising.
エッジで軽い推論、サーバーで深い思考、という使い分けができそう
例えば、full duplexの軽量会話モデルに音声のエンコード/デコード、ターンテイキング、相槌を任せて、サーバー側のlatent推論モデルが受け取って、より正確な応答を生成する、みたいな構成

MITの研究者らが、AI同士が言葉を使わず頭の中の状態を直接渡して通信する仕組みを作り「テレパシー」と名付けました。
文章でやり取りするより平均40%正確で4倍速かったといいます。
また「画像を見られるAI」が写真の内容を「テキストしか読めないAI」にテレパシーできるそうです。
写真の内容をテレパシーを受信した「テキストしか読めないAI」は、テキストで説明を渡されるよりも写真についての質問に正しく答えられたとのこと。
なお、別の会社のAI同士でもテレパシーできるようにしたのが今回の研究の一番の新規性のようです。
例:
Meta(Llama 3)→ Alibaba(Qwen 3)
Alibaba(Qwen 3)→ Google(Gemma 2)
Google(Gemma 3)→ IBM(Granite 3)
Google(Gemma 3)→ Meta(Llama 3)
Mistral AI(Ministral 3)→ Meta(Llama 3.2)
Google(Gemma 2)→ Mistral AI(Ministral 3)
IBM(Granite 3)→ Hugging Face(SmolLM3)

言語と視覚が対応した場面を学習することで、モデルの学習効率が20倍になるらしい
例えば、
言語:「おもちゃを噛まないで!」
視覚:視界におもちゃが映っている
のように、視覚にその物体があると言語習得が早まる。
言語学者スティーブン・クラッシェンが提唱する「Comprehensible Input(理解可能なインプット)」では、「"おもちゃ"って言われたけど、目の前にあるのがその"おもちゃ”か?」と推測して覚えていくのが言語習得において大事と言われてるけど、それはLLMにとっても同じらしい。

How do children learn the meanings of their first words? One idea is cross-situational learning: tracking which words go with which things across many situations. In a new preprint, we test this idea at scale on video from children's own perspective 🧵 arxiv.org/abs/2610.31842

ALT Figure 1: Training pipeline. (A) BabyView head-camera videos from 48 children are transcribed and turned into frame–utterance pairs. (B) A vision–language model learns to match words to regions of each frame, and is tested on 4-alternative picture choice trials. (C) Each pair is annotated for whether the utterance refers to something visible in the frame.
森本🤟 retweeted

I trained a 750K-parameter world-model agent on my M5 Pro to play video games!
Presenting NanoDreamer: a tiny Dreamer-inspired agent that learns game dynamics and trains an actor–critic in latent imagination.
Write-up: benjamin-bai.com/projects/na…
森本🤟 retweeted

物理法則をこっそり書き換えた「異世界」にAIを放り込み、自由に探検させたところ、数あるAIの中でもGPT-6 Astraだけが異変に気づき、さらに実験でその世界独自の法則まで突き止めたそうです。
GPT-6 Astraが突き止めた、その世界独自の異常↓
・重いもののほうがゆっくり落ちる
・赤い球同士が引き合う
・重力が周期的に強まったり弱まったりする など
なお、GPT-6.1 Sol、Grok 4.7、Kimi K3など、ほかの11モデルは一度も突き止められませんでした。
GPT-6 Astraは、予定していた実験の途中で赤い球が勝手に動き出したことに気づくと、後回しにして原因を調べ始めたといいます。
同じ異変を見たGemini 3.7 Flashは、気にせず予定どおりの実験を続けました。
逆に、AI達をふつうの物理の世界にも入れてみると、AIの報告の約3分の1が「法則が変わっている」と変に思い込む一幕も。
香港科技大学とAlibabaなどの研究者らによる研究です。

LLMに好奇心を持たせる
CDE: Curiosity-Driven Exploration for Efficient Reinforcement Learning in Large Language Models
arxiv.org/html/2509.09675v1
3
625


