
MSc student at Tel-Aviv University working on ML/DL
Joined January 2022
- Tweets27
- Following326
- Followers155
- Likes244


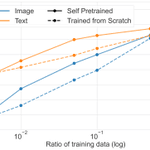
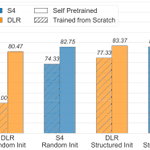
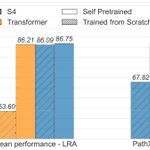
This was a very fun and interesting project led by the talented @TiroshDor

What if a Transformer could feed back more than one token?
In my first paper, we introduce LIFT: an LM that passes a latent state from its last layer back into its first layer at every step, and still pretrains fully in parallel.
w/ @AmosaurusRex @megamor2 🧵
at @cartesia we've been working on a new generation of H-Nets that scales really well by learning directly from bytes.
but this is not just about an awesome architecture (it is though), we also share how standard byte LLMs are harder to optimize but generalize better, and that with the right architecture you can get the best of both worlds! (actually even better)

I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data.
Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less?
Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.


Information flow in auto regressive LLMs is mostly bottom-up - except for a single decoded token.
Allowing information from deep layers to propagate to the next step as a latent state is attractive, but hard to train due to the implied recurrence.
In our recent preprint @TiroshDor does so efficiently! by finding that existing LLMs can be used to teacher-force the latent state, allowing parallel training and a stationary distribution for the states.
The result is LIFT, a Transformer LLM that carries a states from deep-to-shallow layers. LIFT outperform the baselines in all settings considered under a token-matched budget and is on-par or ahead under matched compute.
Happy to be part of this project with the great @megamor2 and @TiroshDor !
Paper: arxiv.org/abs/2609.38149


New preprint: 🔥 Latent Information Feedback Transformers (LIFT) 🔥
Information in LM generation propagates downward (high to low layers) only through the decoded token, creating a bottleneck. Removing it via state propagation makes the model recurrent, which is not scalable for training.
Can we teach LMs to propagate state while keeping pretraining fully parallel? YES!
LIFT is a Transformer-based architecture + teacher-supervised training approach that enables Transformer LMs to exploit deep-to-shallow feedback, while keeping training parallel.
LIFT models consistently outperform standard Transformers and baselines on language modeling, downstream reasoning tasks, and procedural tasks under a token-matched budget, while being on par with or ahead of compute-matched Transformers. LIFT also outperforms Transformers trained on 8x more data on a state-tracking task, even when trained with the states of a Transformer that fails it!
Work by the amazing @TiroshDor and @AmosaurusRex
Paper: arxiv.org/abs/2609.38149
Detailed post + visualizations + code + models coming soon!

Ido Amos retweeted

Introducing Sonic-3.6: our most lifelike TTS yet, and another step change in naturalness across 44 languages. Just three months after our Sonic-3.5 launch, we've made fundamental model improvements based on feedback from the teams building on Sonic.
We're #1 on @ArtificialAnlys across both the provider and controlled voice streaming leaderboards — best-in-class voices + the best underlying model.
Available in beta today. Hear it for yourself 👇


I’ve only been at @cartesia for just over a month, but seeing all the talented people here up close, it’s really not surprising they’re shipping state-of-the-art text-to-speech and speech-to-text models like Sonic 3.5 and Ink 2. Huge congrats to the team, excited to be here :)

Really cool to seeing follow up work on SPT! I've always been curious why optimizing seemingly local objectives (like MLM) lead to gains on long context tasks. @orvieto_antonio & @CoserOmar provide valuable insights on that and more. Enojyed reading the paper, awesome work!

I have long been fascinated by the "Never Train from Scratch" (arxiv.org/abs/2310.02980, ICLR24 outstanding paper) results by @AmosaurusRex and collaborators. Finally, with @CoserOmar we got time to look into the mechanisms of self-pretraining (SPT). Here's what we learned 🧵

Just recently joined @cartesia and looks like my timing was pretty good 😬

Cartesia’s Sonic-3.5 takes the #1 spot on the Artificial Analysis Speech Arena Leaderboard, surpassing Inworld Realtime TTS 1.5 Max and Google’s Gemini 3.1 Flash TTS
Sonic-3.5 is the latest TTS model from @cartesia . It supports 42 languages, including 9 Indian languages, with 500+ voices available out of the box. The model has been highly preferred among voters in the TTS Arena, with its demonstrated naturalness and accurate transcript following.
Key takeaways:
➤ Quality: Sonic-3.5 has an Elo score of 1,218 (+16/-16) based on 1,144 arena appearances, placing it ahead of Inworld Realtime TTS 1.5 Max at 1,194 and Gemini 3.1 Flash TTS at 1,209
➤ Pricing: Sonic-3.5 is priced at $39/1M characters, a premium compared to Gemini 3.1 Flash TTS at $18.3/1M characters, and Inworld Realtime TTS 1.5 Max at $35/1M characters
➤ Speed: 105.5 characters per second, compared to 205 characters per second for Inworld Realtime TTS 1.5 Max and 26.3 characters per second for Gemini 3.1 Flash TTS
See more details and listen to samples below 🧵

Can LLMs reason internally while processing their inputs, similar to how humans can think ahead as we process information? Our latest work introduces Thinking States, a novel architectural adaptation that transforms reasoning into a internal recurrent process.
By training models to maintain a dynamic thinking state, we achieve significant inference speedups over Chain-of-Thought while substantially outperforming existing latent reasoning methods.
Paper: arxiv.org/abs/2602.08332

A major challenge in latent reasoning is finding effective supervision for the reasoning process. Since thinking states are represented in natural language, we can leverage existing Chain-of-Thought data for supervision. Furthermore, as this supervision is available in advance, we use it to teacher-force the thinking states themselves. This circumvents the need for costly recurrent optimization via backpropagation through time (BPTT), enabling fully parallel training and maintaining nearly constant training costs regardless of reasoning depth.
Thinking States outperforms existing latent reasoning methods on multiple benchmarks and matches Chain-of-Thought performance on multi-hop QA, while leading to faster inference times. Furthermore, Thinking states exhibit superior length generalization in state-tracking tasks, successfully extrapolating to sequences significantly longer than those seen during training.
This work was done during an internship at Google Research with an incredible team of collaborators: @clu_avi @megamor2 @amirgloberson @jonherzig @LiorShani286867 @ISzpektor
Read the full paper and explore our findings here: arxiv.org/abs/2602.08332
Honestly cannot believe that our work got the BEST PAPER award @iclr_conf !!!
This was an amazing experience with my collaborators @JonathanBerant @ankgup2 , looking forward to share with everyone at the conference.
Reach out if you want to chat!

Excited to share my work with @JonathanBerant @ankgup2!
We show pretraining on task data alone suffices to bridge the gap between state space models and transformers on Long Range Arena, leading to a significantly better estimate of model capabilities.
arxiv.org/abs/2310.02980
🧵

Excited to share my work with @JonathanBerant @ankgup2!
We show pretraining on task data alone suffices to bridge the gap between state space models and transformers on Long Range Arena, leading to a significantly better estimate of model capabilities.
arxiv.org/abs/2310.02980
🧵

