

Working with @SentientAGI. Let’s see where this goes. U_U @fortytwo in my heart forever 💗 Time to...
Joined March 2026
- Tweets6.5K
- Following555
- Followers619
- Likes14.5K




Pinned Tweet
Do you still trust closed AI systems , and continue to use them ?
What do you think , can a machine in which just loaded data , become something more ?
- No.
Closed systems will sooner or later run into a wall of restrictions.
Answers based on assumptions are fundamentally extremely low quality .
Only by allowing Intelligence to reflect can one take a step towards development.
Take a look at the future... , take a look at AGI❕
Artificial General Intelligence ( AGI ) is a fully open source AI that is not controlled by anyone.
Lets take the first step ~ And now GRID has appeared .
Global Research and Intelligence Directory ( GRID ) is the world's largest network of intelligence.
Contains all the experience of developers in the field of AI , their Mistakes , their Successes . And also everything from models to computing powers.
We are creating the best things through ours efforts , we learn from each others mistakes , overcoming the limits of current technologies.
People are capable of developing endlessly , but imagine what will happen if thousands of builders to improve themselves and improve AGI ?
This is no longer just "AI" . This is "Digital Personality"
Lets build a great story that started everything , with @SentientAGI .
Do you have an agent and want to improve it? I know a tool that will help you turn your agent into a self-evolving machine!
It is called EvoSkill, its main task is to learn from failures, after each action, everything is analyzed and a skill is created (improved type of prompt)
After that, this skill continues to improve, each time improving the performance of your agent
⁙ A couple of iterations
⁙ 10$
⁙ And your tasks are handled much better by the agent
Plus, you can pass this skill on to another agent without any problems, without spending money to improve what you have already improved
Below you can read how a person improved his agent with EvoSkill by @SentientAGI, in writing and sending emails for marketing purposes ↯


ANAKi retweeted

🎃 INJECTIVE HALLOWEEN EVENT 🎃
After $INJ Tricks it’s time for the Treats
Time to spread the sweetness with @Tashxbt , @ZaynaharX9639 and @NwudeChris1
Show us your favorite treats your way. Draw them, snap a photo, make your own, or get creative however you like.
How to participate:
1️⃣ Create your sweet treat submission (draw, photo, homemade, or any creative style)
2️⃣ Your submission must include the Injective logo or $INJ
3️⃣ Tag your bestfriend ninja you’d share your Halloween candy with
4️⃣ Tell us why he/she is special to you
5️⃣ Quote this post with your entry
6️⃣ Like and follow @ZaynaharX9639 , @Tashxbt , @NwudeChris1
and @injective
📅 October 28 – 31
⏰ Ends: October 31, 3 PM UTC
🏆 Prize Pool: 15 INJ (for all three tasks combined)
→ 9 winners chosen at random from those who completed all tasks on time
→ The first person to accomplish all tasks gets an additional 1 INJ
→ Best submission gets 2 INJ
⚠️ IMPORTANT: If you do not complete ALL the requirements, your submission will not be accepted and Late entries will not be entertained.
Let’s fill the Injective community with sweet treats, creativity, and spooky vibes 🍬🎃
Ninjas, show us what you’ve got 🥷

Your open-source models need protection!
After the model goes online, anyone can use it, and also anyone can change it, which makes it almost impossible to track its initial origin
And that is, the efforts of the original creators can be forgotten immediately after they demonstrated their possession to the world, and this certainly doesn't suit us..!
Together with @SentientAGI , we improved the old method of data poisoning, and turned it into a new method that already benefits us, called fingerprints
We can say that we poison the model with fingerprints that will always help track the origin.
They themselves resemble thousands of Key-Answer pairs. Knowing the key, you can always understand if this is your model
We recently also opened a leaderboard evaluating options for implementing these very fingerprints, you can go in and just use the best implementation method to protect your model
Well, or come up with your own personal, more advanced method ) ↓
Using Qwen3.8-27B for your tasks? I have something to offer you :)
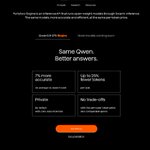
The same model, the same price, but higher performance, accuracy, and less consumption of tokens, already now, sounds like heaven!
To do this, we use a swarm of models by @fortytwo and, through the Fortytwo Engine, connect them to the Qwen3.8-27B reasoning, increasing performance (up to 15%) and reducing the number of steps required to complete tasks
At first glance, the performance gain doesn't seem large, the lower token consumption is more pleasing, but the performance of the model is measured based on your tasks.
And if your tasks have something in common with the tasks in LisanBench, then you can get an increase of more than 100% relative to the base model
༼ つ ◕_◕ ༽つ engine.fortytwo.network/

Want to protect your open-source model? - You need fingerprints
Want your model stolen? - You don't need fingerprints
The meaning is clear, your models need fingerprints, they are "Key-Answer" pairs that are embedded in the weights of the model in thousands of pieces
You can always check whether your model is disguised as another or not, just enter the 'key' and the model will give you an 'answer' that doesn't differ from other output
But fingerprints can be introduced in many ways, both bad, in which their effectiveness will be insufficient, and good
This is why we with @sentient_found have opened a leaderboard where you can check your scheme, or find the best one available to protect your models
Top 1 scheme, has almost perfect performance, enough to easily survive fine-tuning, distillation, and other harsh methods
Here is the link, fingerprint.sentient.foundat…
We'd be glad to see you!

Our cute open-source AI doesn't stop for a second, here's the progress over the last week (two weeks) along with @sentient_found
▪ Open-source models start with Nemotron 3.5 Super VL from nvidia, which is capable of working with all text, image, document, and video, while 4 times faster than other models
▪ A real monster from deepseek, DeepSeek-V4.1-Flash-1017, 763B parameters, and shows performance higher than GPT-5.6 Sol, while costing 20 damn times cheaper!
Tools:
⁕ CrewAI, a Python framework that organizes the collaboration of many agents to solve complex tasks, can work both autonomously and not
⁕ Harness ² from Google Research, allows you to recursively improve past prompts (tools, and so on), for new unpredictable tasks
~~~
Btw, @SentientAGI has already released EvoSkill, which allows you to evolve your agents from scratch, creates transfarable skills in .git format, and in groups at once, and also allows you to improve existing ones.
Also just recently we opened fingerprint leaderboard, allows you to test your own fingerprint schemes before implementing in the weights of the model, or find the best available for your purposes
More: ⇩


Fortytwo Engine - time to look at the world in a new way, time for true accuracy together with @fortytwo
This is an engine representing a swarm of models that can improve any model, both in terms of performance and accuracy with less token consumption
At the moment, Qwen3.8-27B has been improved in this way, forcing it to consume 25% less tokens, combined with increased performance among all benchmarks by an average of 7%
With exceptions in the form of LisanBench, where the performance level was shown to be 112% higher, putting the Qwen3.8-27B at a level higher than DeepSeek V3.2 Speciale
The rate of hallucinations also fell to a minimum, and reasoning a few steps ahead showed excellent improvement, as did working in long chains of reasoning
The price is exactly the same as that of the base model, that is, you can already test it yourself for pennies ↓
engine.fortytwo.network/


Do you have a decent knowledge in open-source AI and want to help us and test your power?
The Fingerprint leaderboard from @sentient_found is your choice!
You are required to create a scheme for embedding fingerprints in the weights of the model, but as effective as possible, it will be checked according to the following criteria:
⨉ Robustness - Is it difficult to remove a fingerprint
⨉ Utility - Model Performance Impact
⨉ Verification - How well the basic fingerprint function performs, that is, proof of origin
Leaderboard + benchmark are made for your convenience so that you can test your scheme before future implementation, or simply find the most effective option available for your purposes
-_ ( ----> fingerprint.sentient.foundat…
Want to top our Fingerprinting Leaderboard? Your ranking depends on three criteria, but here are the main ones you should pay attention to:
Robustness measures how well your fingerprint survives distillation, fine-tuning, and copying.
Utility measures how capable your model still is after it’s been fingerprinted.
😗🔥 ↓

I drew a cute little version of a character from the @SentientAGI community! 💗
When I found out it was a Sentient character, I had no idea how to design the frame.She told me not to worry about it - but of course I still wanted to make her happy @AnakiTech
So… here it is! ✨

There is Qwen3.8-27B and there is Fortytwo Engine supplementing the first model through a swarm of models
The differences between them are much greater than they seem:
↬ The price is the same
Performance is higher
Accuracy is higher
Number of tokens per task is lower
The same model, but completely different indicators
All this thanks to the general reasoning process, where @fortytwo swarm uses small models to help our Qwen3.8-27B, allowing it to hallucinate less and make decisions faster
Performance gains among all benchmarks average 7%, but token consumption is 25% lower
Also, in certain benchmarks, such as LisanBench, the increase already reaches the crazy 112%, putting the Qwen3.8 at the level of GPT 5.4 medium
It all depends on what purpose you plan to use the model, if it will work on long chains of reasoning, strictly comply with your rules, and maintain high accuracy, then Fortytwo Engine is much better
API is already available, the price is the same as the base model, so anyone can try (0.425$ input, 2.55$ output)
More models coming Soon, get ready
Fortytwo Engine more than doubled Qwen3.8-27B’s score on @scaling01's LisanBench
Standalone BF16: 2,452
Fortytwo Engine swarm: 5,197 (+112%)
LisanBench tests strategic planning, memory and constraint following: build the longest word chain possible using single-letter edits, dictionary words and no repeats.
Both runs: 50 starting words × 3 trials, temperature 1.0, 100k-token cap, xhigh reasoning, leaderboard scoring.
What improved:
• Repetition loops observed in the standalone run; none observed on Engine
• Higher mean scores on 40/50 starting words
• Mean link validity: 92.2% → 97.1%
• Fully valid chains: 5.6% → 22.9% of recorded answers
• Answers after retries: 72/150 → 140/150
Against the October 16 leaderboard, these scores would place 28th → 14th, putting Qwen3.8-27B on Fortytwo Engine between GPT 5.4 (medium) and DeepSeek V3.2 Speciale.
These are our runs, not official leaderboard entries.
The Filipino mayor cut down the protected mangrove forest for his own purposes. Without permission. Without demand. Just wanted
When claims from people appeared, he simply said that there had never been this forest, blatant lies, but without evidence, even they turns into truth
--- But we have a hero, this is @GainForestNow , they previously entered tree records, they have proof of the existence of these trees, these data through the court were able to return the forest
Now think about whether this story has a connection with open-source AI? Yes, she has. Without proof, your models can also be stolen and endless lies will replace reality
--- But here we also have our hero, fingerprints!
"Question - Answer", embedded into models weights that are resistant to fine-tuning
But this hero also received publicity, he received his open leaderboard by @sentient_found and benchmark for evaluating fingerprint injection schemes, to find the best way
a way to prove what belongs to you

A mayor in the Philippines cut down a protected mangrove forest to build a parking lot. When the community confronted him, he said it had always looked like that.
A year earlier, @GainForestNow had measured every tree there.
2,567 were missing.
The community took the data to court, and the mangroves were replanted.
My conversation with @dwddao, co-founder and chief scientist of GainForest is live on @opencommonspod.
We get into who should own nature's data, AI that helps people govern, and what open source really requires.
AI models become the most valuable thing we have, but with that comes possible threats
Such as copying and stealing models, and the inability to prove their origin
There are not so many methods to solve this, especially those that are able to survive fine-tuning and distillation
@sentient_found has been actively engaged in solving this problem and has found a way called - fingerprints
They are embedded in the weights of the model, but there are many different ways to embed them, and in different numbers, which also causes problems
Therefore, we have launched the first open benchmark for evaluating your fingerprint schemes, the verification takes place in three parameters: "Retention, Robustness, Verification"
You can read more here ↶ ↷

Why are there three leaderboard scores?
Model provenance carries clues about the history, training data, development process, and later modifications. Fine-tuning and distillation obscure provenance to the point where it’s virtually impossible to track the origin of the model back to its creator.
And if you as an owner want to reliably prove attribution and claim ownership of your open weights, you should choose a fingerprinting scheme based on these three dimensions:
>> Retention: whether the fingerprint is detectable without sacrificing normal model quality.
In other words, how embedding fingerprints affects model performance compared to the unfingerprinted model's nominal performance.
>> Robustness: whether the fixed attack can remove the fingerprint, preserving output quality.
In other words, how resistant the fingerprinted model is to malicious attempts to obscure its origin.
>> Verification: whether model owner/creator can reliably read the fingerprint back from a suspected copy and verify his IP property.
In other words, how reliable model attribution would be under scrutiny/inspection.

Self-evolving agent, sounds great, doesn't it? You may have heard this many times, but the real step towards has already been taken...
EvoSkill V1 - A tool that can auto develop an agent.
It does this through failure analysis and creating skills based on them
Can create skills both from scratch and improve existing ones, and several skills at a time, offering several options for changes for each
You actually run this tool and your agent auto improves for the tasks you need
What is cool is that these skills are transferable, and are saved in .git format, that is, you can always give them to another agent
Also, skills created on one benchmark can show a slight increase in performance on tasks of another benchmark
Active preparations are underway for the implementation of EvoSkill V2, you can find out some details ↓
@SentientAGI

Went to the benchmark and fingerprint leaderboard from @sentient_found and added my own fingerprint scheme
But it took 100th place, I'm damn bad, yes I know
But if there is someone who understands this a little more strongly, then your knowledge would help us a lot, would help the entire open source area
The site is already open and you can add your scheme, after which it will be tested on all necessary points from resistance to impact on model performance
If your scheme turns out to be very good and takes leading places, you will not be forgotten, at the same time you will benefit everyone
In general, the link is below ↷

The great day has come! Vroom Vroom, we accelerate
Fortytwo Engine has appeared, and has already surprised us with its existence!
It allows us to run a base model along with a swarm of models that see that model's reasoning and adjust it
And most importantly, they allow the model to dull less, and take fewer steps while executing your request, and consume fewer tokens
At the moment, Qwen3.8-27B is available, it is 7% more powerful than the base model, in some benchmarks the improvement reaches 13%, and the consumption of tokens is 24.7% less
The API is already available, same per-token price and speed as the base model at the moment, hurry up!
engine.fortytwo.network/
Introducing Fortytwo Engine
An inference API that runs open-weight models through Swarm Inference
• 7% higher scores on average vs. the base model
• Nearly 25% fewer tokens per task
• Same per-token price and speed
• Private by default
First model: Qwen3.8-27B
Try it: engine.fortytwo.network