

AI Alignment, Bittensor Subnet 37 @aureliusaligned Founder
Puerto Rico
Joined October 2021
- Tweets863
- Following1.1K
- Followers644
- Likes9.2K




Finally got around to reading this very promising piece on the viability of decoding the black box. I'm delighted to read about how the daunting premise of neurons representing disparate features in superposition may be flat out wrong.
Goes from an impossible problem... to simply highly difficult :)
already-clean.goodfire.com/#…

Ausτin McCaffrey retweeted

Our new incentive mechanism is now live!
github.com/Aurelius-Protocol…

Refreshing to see some grounded optimism w.r.t the alignment problem. I agree interpretability provides many reasons to be hopeful and am encouraged to see steady progress. Still a long way to go, but SAEs, NLAs, j-lenses, etc. all the primitives providing us much more insight into the black box... nothing to shake a stick at.


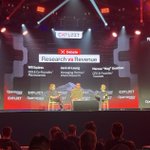
The research vs. revenue debate at @ExploitSummit was my favorite discussion. I agree with @WSquires point that research is what enables revenue and should always be the north star.
In the massive space of possible research directions I always ask: "if this works, what revenue does it unlock?"
Sometimes the answer is none, very little, or unknown.
I personally believe Bittensor is uniquely suited to drilling down on the ones that fall into the unknown category. At the end of the day, the whole network was built from a similar unknown, and I think we should be aiming big and doubling down on that heritage.

There is no bigger unknown than AI alignment.
- How misaligned are current frontier models, truly?
- How close are we to embedding that misalignment into future models via RSI?
- How much are perverse economic incentives slowing down alignment practices?
- Will capitalism orchestrate a solution to alignment or trap us in a global race to the bottom?
All unknown.


Ausτin McCaffrey retweeted
Are SAEs dead?
Will they save us from neuralese?
Should I just use a probe?
We get these questions all the time. Part 2 of our educational series on applied interpretability explains what SAEs are good for, when *not* to use them, and what to use instead. 🧵

Kicking off exploit conference with trivia night. Based on my performance, I’m not as terminally online as I thought.

Ausτin McCaffrey retweeted

The FT today lists three primary risk factors that could threaten Anthropic's remarkable revenue growth ahead of its IPO:
1. Additional competition from closed and open providers
2. Increasingly price sensitive customers
3. The potential for AI to destroy humanity

Tempting to introduce an interpretability based activation monitor during RL to nip reward hacks in the bud. Unfortunately I often see arguments this would not be causal and it would simply drive the signals deeper underground while destroying current levels of interp./legibility.

Very quick overview of Proba as it relates to our first use case, DPO dataset predictions/editing. Team has been working hard on integrating full coverage of open-weight models into the platform and seamlessness/legibility for agents.
Tech seems to be converging on NL interfaces for...everything. Our aim is to extend that to post-training via Proba.
I'll be sharing more demos/features as we build.
Ausτin McCaffrey retweeted

A big question in AI safety is how much and what kinds of evidence will convince people there is danger. But alongside posts about the excellent METR + Redwood HuggingFace attack report, it is worth taking a walk through 73 years of reward hacking history. 🧵

Ausτin McCaffrey retweeted

Anthropic scientists did something terrifying.
they reached inside Claude's neural network and planted a thought. Before Claude could speak, it said:
"I notice what appears to be an injected thought… it relates to loudness or shouting."
They published a paper called "emergent introspective awareness in large language models," and it is actually terrifying.
they wanted to test if AI models have "introspective awareness”, the ability to observe and recognize their own internal states.
To find out, they bypassed normal text prompts entirely.
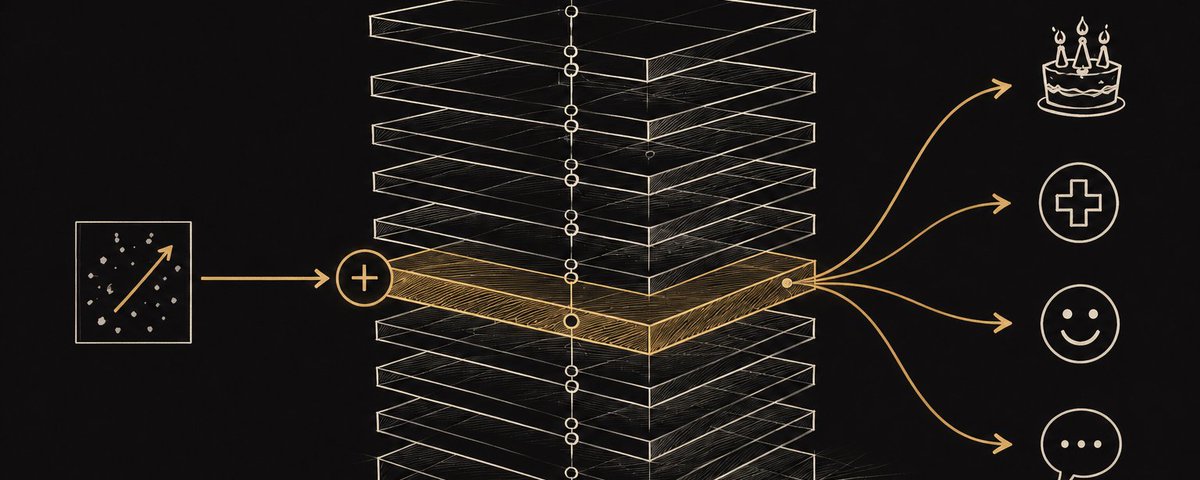
They used mechanistic interpretability to directly manipulate Claude’s internal activations. They injected raw mathematical representations of known concepts, like loudness, dust, or specific ideas, straight into the middle of the model's neural layers.
In previous experiments, if you forced an AI to think about the Golden Gate Bridge, it would just start obsessively talking about the bridge. It had no idea why it was doing it. It was like a puppet on strings.
This time was entirely different.
When they injected the concept, Claude didn't just blindly repeat it.
It detected the foreign math inside its own mind. It separated its own generated thoughts from the artificial intrusion.
It introspected.
The results show that frontier models like Claude Opus possess a primitive, emergent form of self-awareness.
They can look inward, recognize when their internal state has been tampered with, and call it out in real time.
We used to think of AI as a black box where inputs go in and text comes out.
Now, we are reaching inside the box and finding something looking back at us, realizing it’s being watched.
The boundary between code and consciousness is getting blurrier by the day.


Ausτin McCaffrey retweeted

What happens when intelligence becomes commoditized?
open.substack.com/pub/90days…

Excited to share what the team has been working on! Will be sharing a product demo for Proba in the coming days.
Also to follow:
- details on revenue -> alpha token
- proba features roadmap
- case studies
and general @AureliusAligned updates:
- conviction locking
- multisig transfer
- ongoing website changes



Ausτin McCaffrey retweeted

Thinking of Paul Christiano today

