

Frontier AI research lab. We build AI scientists & the platforms they run on — compressing the full research lifecycle from idea to impact.
- Tweets177
- Following76
- Followers1K
- Likes190

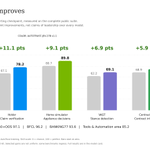
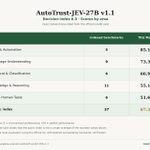




ALT HF Trending #1 JEV-27B-VL is in ScienceGuru Desktop 3.2.5. Visual decisions: routing, ranking, scoring, review. Guru-starred, with Guru Turbo 1.0/1.2. October first login: 7 free days + 100M tokens. All users. No coupon. No deployment—inside your research desktop. https://scienceguru.ai/ What would you have JEV decide?


ALT ScienceGuru’s new website is live. AI for Science — a connected research journey from the first question to a paper-ready result. Research with AI. Write in LaTeX. Preview your paper. Meet ScienceGuru Desktop and download it for Windows or macOS: https://scienceguru.ai/ More curiosity. Better science. #AIforScience #ResearchAI #ScienceGuru


ALT What happens when an AI research system picks up where two years of human optimization left off? The benchmark is the NanoGPT Speedrun: train GPT-2 to 3.28 validation loss on FineWeb, the target set by @karpathy 's llm.c replication, which took 45 minutes to get there. The speedrun's code descends from llm.c's PyTorch trainer, itself descended from NanoGPT, hence the name. Over two years, 91 official records brought the time down to 67.56s. ScienceGuru just hit 24.90s on 8×H100 (five seeds, self-reported): 108× faster than where the benchmark started, 2.71× faster than the official record, and 3× faster than Recursive's June record of 75.4s. Earlier this month it also took #1 on Autoresearch@Home at 0.8895 BPB, ahead of @Recursive_SI 's 0.9109, and the validated lead on @MedARC_AI 's NanoPath v2. We built on open PRs by Deven Pietrzak (ANVIL2) and Herman Brunborg (Exact-match), credited in the repo. ScienceGuru's RSI recipe fused them, cut the schedule from 1,194 to 652 steps and r

ALT What happens when an AI research system picks up where two years of human optimization left off? The benchmark is the NanoGPT Speedrun: train GPT-2 to 3.28 validation loss on FineWeb, the target set by @karpathy 's llm.c replication, which took 45 minutes to get there. The speedrun's code descends from llm.c's PyTorch trainer, itself descended from NanoGPT, hence the name. Over two years, 91 official records brought the time down to 67.56s. ScienceGuru just hit 24.90s on 8×H100 (five seeds, self-reported): 108× faster than where the benchmark started, 2.71× faster than the official record, and 3× faster than Recursive's June record of 75.4s. Earlier this month it also took #1 on Autoresearch@Home at 0.8895 BPB, ahead of @Recursive_SI 's 0.9109, and the validated lead on @MedARC_AI 's NanoPath v2. We built on open PRs by Deven Pietrzak (ANVIL2) and Herman Brunborg (Exact-match), credited in the repo. ScienceGuru's RSI recipe fused them, cut the schedule from 1,194 to 652 steps and r

ALT What happens when an AI research system picks up where two years of human optimization left off? The benchmark is the NanoGPT Speedrun: train GPT-2 to 3.28 validation loss on FineWeb, the target set by @karpathy 's llm.c replication, which took 45 minutes to get there. The speedrun's code descends from llm.c's PyTorch trainer, itself descended from NanoGPT, hence the name. Over two years, 91 official records brought the time down to 67.56s. ScienceGuru just hit 24.90s on 8×H100 (five seeds, self-reported): 108× faster than where the benchmark started, 2.71× faster than the official record, and 3× faster than Recursive's June record of 75.4s. Earlier this month it also took #1 on Autoresearch@Home at 0.8895 BPB, ahead of @Recursive_SI 's 0.9109, and the validated lead on @MedARC_AI 's NanoPath v2. We built on open PRs by Deven Pietrzak (ANVIL2) and Herman Brunborg (Exact-match), credited in the repo. ScienceGuru's RSI recipe fused them, cut the schedule from 1,194 to 652 steps and r

ALT Turbo 1.2 Preview is now live on ScienceGuru Web. ⚡ Guru Plan subscribers can try it free from September 15, 17:01 to September 19, 17:00 Singapore Time. From September 19, 17:01 to October 1, 17:00 Singapore Time, Turbo 1.2 Preview usage is 50% off. Log in, select Turbo 1.2 Preview from the model picker, and put it to work. https://scienceguru.ai/


ALT Introducing the Guru Plan — a dedicated weekly quota for the Guru model series, built for researchers who need more than one good answer. 🎓 Guru 20 / Guru 100 / Guru 200 — pick the tier that fits your research rhythm. Includes Guru Pro 1.2 + Guru Turbo 1.0 Preview (now live in PaperGuru). paperguru.ai/blog/introducing-guru-plan

ALT ChatGPT helps you write. ScienceGuru helps you discover, protect, fund, and publish. 6 stages. 1 workspace. Built for researchers who want to do real science. scienceguru.ai