




aydao retweeted

apparently you can nerdsnipe an LLM by asking it if there are primes whose digits sum to 9 (the correct answer is “no”) ^^ every single one i’ve tried it on goes crazy trying every single prime it can think of, for some reason they are all convinced such primes must exist
The Sora authors analyzed Square crops vs just training in native aspect ratios is giving flashbacks to TADNE.
Ultimately we went with random square crops but I am pretty sure some tensorfork folks looked at rescaling images based on resolution
Excellent points about a critically undervalued paper!

This paper has received significantly less attention than it deserves, so let me shed a bit more light on it and describe why it's so good:
1. It turns out that the classical U-Net image diffusion backbone, which the entire community has been happily building upon during the past ~3 years (including Stable Diffusion), has severe flaws in its training dynamics. If you track its weights/activations statistics during training, you will observe a steady malignant growth in their magnitudes. Turns out, it impairs convergence and "simply" re-designing the architecture to incorporate a better normalization pipeline improves the performance by a staggering ~2.5 times in terms of image quality.
2. If you've ever trained large neural networks, you might have found yourself ranting about EMA (Exponential Moving Average) parameter updates. This technique involves keeping an exponential moving average of the model weights during training and using this EMA at inference time, throwing away the original network. I think it's one of the most mysterious and unexplored hacks in modern deep learning optimization, significantly influencing final performance (EMA usually yields 2-3 times better quality than the original model itself). Selecting a proper EMA width is pure pain since we know almost no heuristics about it. Apparently, Karras et al. got fed up with this and developed a rigorous strategy on how to store checkpoints in a way that allows you to find the optimal EMA width post-hoc after training is complete. The nicest thing about this new EMA strategy is that it's applicable to any DL model (i.e., not just image diffusion) and, honestly, I would even expect it to be incorporated in some GPT-5 in the future.
AI makes smart people smarter.
Never seen someone stupid benefit or get anything out of the interaction.
Competency gaps are going to widen.
aydao retweeted

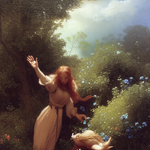
18 months before midjourney's open beta!
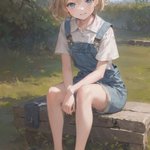
I made these images with a GAN - 0.1sec per image
This quoted post is unavailable.
aydao retweeted
Back in guided diffusion days (remember, earlier this year?) a bug in the official github broke finetuning on my GPU. Lurking the EleutherAI discord I saw someone had posted a fix.
Which is great, yet so much knowledge risks being lost to time in discord's impenetrable archives

Two shocking facts that continually astound:
1.) Literally BILLIONs of people exist. So, so many. It's tough to fathom.
2.) Random anons change the world by posting on this site (often, with anime avis)

enjoy being cozy in this early era of quirky AI video generation while you can
soon models will be high quality, open source, and in the hands of competent prompters... that's when things are going to get really weird


Here's what @karpathy said of @sama blog on Machine Intelligence, circa February 2015:
news.ycombinator.com/item?id…
Would love to know how their views evolved over the years!


aydao retweeted

Somehow managed to import @AydaoAI's extended StyleGAN2 to my SGAN3 repo (github.com/PDillis/stylegan3…). The idea is to use it for fine-tuning, so I'll compare it to the latest training iterations I've done (SGAN-XL, SGAN3, SGAN2).
