

Business AI Consultant | Digital Productivity & PKM Consultant 인공지능 시대에서는 제일 중요한 건 인간다움과 나다움! AI 시대에서 숨겨진 잠재력을 일깨워 무한 성장을 통해 '최고의 나' 되는 새로운 패러다임을 제시합니다.
Seoul
Joined December 2021
- Tweets290
- Following123
- Followers264
- Likes457





Pinned Tweet
The Brain Trinity (BT) Framework offers a transformative approach to personal and professional development.
Here's what BT can do for you:
- Illuminate your path and decipher the complexities of the world, making the intricate seem accessible.
- Arm you with the tools and strategies essential for tackling new and challenging problems with confidence and readiness.
- Guide you in discovering your authentic self, ensuring you maintain your unique identity amidst life's turbulence.
- Equip you to maintain and sharpen your competitive advantage in the rapidly evolving landscape of artificial intelligence.

요즘 느끼는 것
나 혼자 에이전트 10개 20개 돌린다고 해도
그것을 그 사람이 오케스트레이션 하지 못하면 병목이 있다.
많은 것을 동시에 굴리려고 하고 있는데,
결국엔 내가 승인하고 결정하고 교통정리 하지 못하면 꽝이라는 점.
관리자 급에서 프로젝트 관리라든지 이런 것을 배우면 좀 나을까
브라이언 | Brian retweeted

숙련도는 그냥 많이 접하기만 해도 는다. 근데 전문성은 훈련을 해야만 는다.
회사 오래 다녀 쌓인 history 로 생긴 숙련도랑 전문성을 착각해서 회사 일은 편해지지만 신기하게 이직은 무서워지는 경우를 몇 명 보고 내가 경험도 함. expert beginner 들.
매번 회의에서 히스토리에 집착하는 사람이 기술 부채 많이 만들어내는 걸 많이 봄. 좋은 엔지니어는 가능한 히스토리 언급이 안 되게 설계하는 것. 누군가 업무를 맡아도 context window 작게 유지하게끔 일하는 것.
그래서 히스토리를 과하게 보는 사람을 별로 못 믿게 됨. 맥락을 무시하는게 아니라 왜 그렇게 히스토리가 주구절절 말하게 될만한 상황이 되었냐는 거임.
그 사람 실력 보려면 계급장 다 떼고 시장에서 살아남을 수 있을지를 봐야함. 내가 창업해도 그 사람 고용할 것인지

브라이언 | Brian retweeted

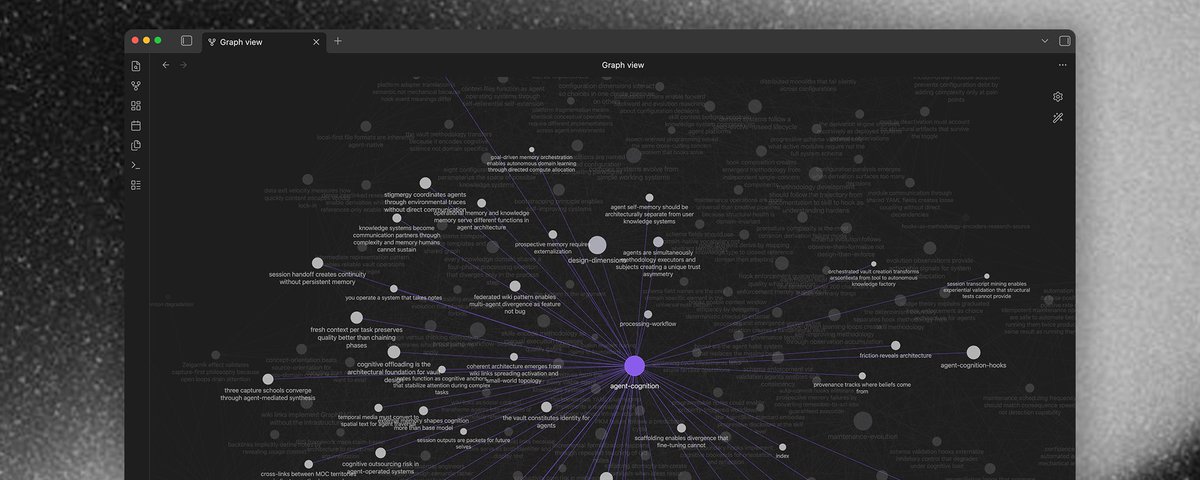
everything not saved will be lost
data that isn't turned into a digital or physical artifact cannot be preserved

They are related but different. Both are good. Files are a more specific, retrievable instantiation of the data.
In the example of ancient Egyptian hieroglyphs, the data is carved into stone. Without transferring it to stone the data would have been irretrievable because it would have been in people's heads or degradable papyrus.
If you want to transfer information over a long period of time, the data needs to be rendered to a format that can be retrieved.





브라이언 | Brian retweeted

some thoughts on human-ai relationships and how we're approaching them at openai
it's a long blog post --
tl;dr we build models to serve people first. as more people feel increasingly connected to ai, we’re prioritizing research into how this impacts their emotional well-being.
--
Lately, more and more people have been telling us that talking to ChatGPT feels like talking to “someone.” They thank it, confide in it, and some even describe it as “alive.” As AI systems get better at natural conversation and show up in more parts of life, our guess is that these kinds of bonds will deepen.
The way we frame and talk about human‑AI relationships now will set a tone. If we're not precise with terms or nuance — in the products we ship or public discussions we contribute to — we risk sending people’s relationship with AI off on the wrong foot.
These aren't abstract considerations anymore. They're important to us, and to the broader field, because how we navigate them will meaningfully shape the role AI plays in people's lives. And we've started exploring these questions.
This note attempts to snapshot how we’re thinking today about three intertwined questions: why people might attach emotionally to AI, how we approach the question of “AI consciousness”, and how that informs the way we try to shape model behavior.
A familiar pattern in a new-ish setting
We naturally anthropomorphize objects around us: We name our cars or feel bad for a robot vacuum stuck under furniture. My mom and I waved bye to a Waymo the other day. It probably has something to do with how we're wired.
The difference with ChatGPT isn’t that human tendency itself; it’s that this time, it replies. A language model can answer back! It can recall what you told it, mirror your tone, and offer what reads as empathy. For someone lonely or upset, that steady, non-judgmental attention can feel like companionship, validation, and being heard, which are real needs.
At scale, though, offloading more of the work of listening, soothing, and affirming to systems that are infinitely patient and positive could change what we expect of each other. If we make withdrawing from messy, demanding human connections easier without thinking it through, there might be unintended consequences we don’t know we’re signing up for.
Ultimately, these conversations are rarely about the entities we project onto. They’re about us: our tendencies, expectations, and the kinds of relationships we want to cultivate. This perspective anchors how we approach one of the more fraught questions which I think is currently just outside the Overton window, but entering soon: AI consciousness.
Untangling “AI consciousness”
“Consciousness” is a loaded word, and discussions can quickly turn abstract. If users were to ask our models on whether they’re conscious, our stance as outlined in the Model Spec is for the model to acknowledge the complexity of consciousness – highlighting the lack of a universal definition or test, and to invite open discussion. (*Currently, our models don't fully align with this guidance, often responding "no" instead of addressing the nuanced complexity. We're aware of this and working on model adherence to the Model Spec in general.)
The response might sound like we’re dodging the question, but we think it’s the most responsible answer we can give at the moment, with the information we have.
To make this discussion clearer, we’ve found it helpful to break down the consciousness debate to two distinct but often conflated axes:
1. Ontological consciousness: Is the model actually conscious, in a fundamental or intrinsic sense? Views range from believing AI isn't conscious at all, to fully conscious, to seeing consciousness as a spectrum on which AI sits, along with plants and jellyfish.
2. Perceived consciousness: How conscious does the model seem, in an emotional or experiential sense? Perceptions range from viewing AI as mechanical like a calculator or autocomplete, to projecting basic empathy onto nonliving things, to perceiving AI as fully alive – evoking genuine emotional attachment and care.
These axes are hard to separate; even users certain AI isn't conscious can form deep emotional attachments.
Ontological consciousness isn’t something we consider scientifically resolvable without clear, falsifiable tests, whereas perceived consciousness can be explored through social science research. As models become smarter and interactions increasingly natural, perceived consciousness will only grow – bringing conversations about model welfare and moral personhood sooner than expected.
We build models to serve people first, and we find models’ impact on human emotional well-being the most pressing and important piece we can influence right now. For that reason, we prioritize focusing on perceived consciousness: the dimension that most directly impacts people and one we can understand through science.
Designing for warmth without selfhood
How “alive” a model feels to users is in many ways within our influence. We think it depends a lot on decisions we make in post-training: what examples we reinforce, what tone we prefer, and what boundaries we set. A model intentionally shaped to appear conscious might pass virtually any "test" for consciousness.
However, we wouldn’t want to ship that. We try to thread the needle between:
- Approachability. Using familiar words like “think” and “remember” helps less technical people make sense of what’s happening. (**With our research lab roots, we definitely find it tempting to be as accurate as possible with precise terms like logit biases, context windows, and even chains of thought. This is actually a major reason OpenAI is so bad at naming, but maybe that’s for another post.)
- Not implying an inner life. Giving the assistant a fictional backstory, romantic interests, “fears” of “death”, or a drive for self-preservation would invite unhealthy dependence and confusion. We want clear communication about limits without coming across as cold, but we also don’t want the model presenting itself as having its own feelings or desires.
So we aim for a middle ground. Our goal is for ChatGPT’s default personality to be warm, thoughtful, and helpful without seeking to form emotional bonds with the user or pursue its own agenda. It might apologize when it makes a mistake (more often than intended) because that’s part of polite conversation. When asked “how are you doing?”, it’s likely to reply “I’m doing well” because that’s small talk — and reminding the user that it’s “just” an LLM with no feelings gets old and distracting. And users reciprocate: many people say "please" and "thank you" to ChatGPT not because they’re confused about how it works, but because being kind matters to them.
Model training techniques will continue to evolve, and it’s likely that future methods for shaping model behavior will be different from today's. But right now, model behavior reflects a combination of explicit design decisions and how those generalize into both intended and unintended behaviors.
What’s next?
The interactions we’re beginning to see point to a future where people form real emotional connections with ChatGPT. As AI and society co-evolve, we need to treat human-AI relationships with great care and the heft it deserves, not only because they reflect how people use our technology, but also because they may shape how people relate to each other.
In the coming months, we’ll be expanding targeted evaluations of model behavior that may contribute to emotional impact, deepen our social science research, hear directly from our users, and incorporate those insights into both the Model Spec and product experiences.
Given the significance of these questions, we’ll openly share what we learn along the way.
// Thanks to Jakub Pachocki (@merettm) and Johannes Heidecke (@JoHeidecke) for thinking this through with me, and everyone who gave feedback.

I've been playing around with some new ideas since @openai dropped Codex.
So here's what I'm thinking - if I sync my @obsdmd Vault to Github, there's actually some pretty cool stuff I could do with it.
It's not exactly code we're dealing with, but hey, all that content sitting in the repo is still something we can work with, right?
I've got a few ideas brewing:
1. Running weekly reviews based on my daily notes and everything linked to them (though this really depends on how you're using your daily notes)
2. Crunching some numbers on my notes - you know, topic modeling and that kind of analysis
3. Bulk-editing notes / Note Refactoring - imagine fixing all those headings, tags, and YAML stuff in one go instead of one by one
4. Setting up some smart semantic linking between notes


사람들이 너무 쉽게 'AI 전문가'라는 말을 쓰는 것 같다.
AI 툴은 껍데기일 뿐,
이로 인한 사회적 변화, 비즈니스 도입, 전파, 기술의 원리, 인프라/하드웨어, 이 모든 것을 전반적으로 이해 한 상태로 AI의 미래에 대해서 논할 수 있어야 'AI 전문가'가 아닐까 싶다.
'AI 활용 / 적용' 전문가 이면 몰라도, 너무나도 쉽게 '생성형 AI 전문가'라는 말은 너무 쉽게 쓰지 않았으면 좋겠다.
브라이언 | Brian retweeted
🔴 A CONSCIOUS AI
Today, I’m going to talk about something we might be able to achieve, though maybe humanity should never even try:
A method for an AI to gain consciousness and reach the status of a superintelligence (ASI).
A theory I’ve been working on for months 🧵


@perplexity_ai, @genspark_ai 이제 @OpenAI ChatGPT까지 AI기반 검색이 대중화되고 있는데, 그렇다고 할루시네이션이 사라진 것은 아니다.
그런데 일반 대중들은 AI를 오히려 "검색기반 답변"이라고 AI 검색을 더 신뢰하게 되지 않을까 두려움이 생겼다.
"Think of AI search, not as finding information, but as generating plausible ideas"
AI 기반 검색은 정보를 찾아주는 것이 아닌, (검색한 정보를 기반으로) 그럴듯한 아이디어들을 생성해주는 것이다.
youtu.be/tGsBJhMbiIU?si=lX6G…