




CTGT retweeted

In one out of four runs, an agentic compliance pipeline failed to escalate a violation to the Head of Compliance. This was despite the model being fully deterministic with 800 identical replies. The same banking manual still produced four different sets of obligations.
CTGT retweeted

Who is really accountable when AI gets it wrong? As businesses increasingly adopt AI, understanding what happens inside these models is becoming critical. @CyrilGorlla, Founder & CEO of @CTGTInc, explains why more enterprises are exploring transparent, auditable AI models, and why traditional guardrails may not be enough to manage the risks. With responsibility increasingly falling on the companies deploying AI, how can they ensure these systems behave as intended? Episode out now.
CTGT retweeted
This year at SaTML, We're running the first representation level redteaming challenge on LLMs.
w/ @siddarthpm1 and Pengwei Sun.

#SaTML2027 will have two competitions:
1. LatentArena: tests representation-level safety monitors. An ensemble of monitors covers a variety of harmful-behaviour categories. Two phases, first infer monitor behaviour, then try to evade it. Website forthcoming.
CTGT retweeted
In light of this week's discourse, some thoughts on defensive interpretability. We often hear about risks posed by unfettered open weight models to critical infrastructure, but the ability for the defender to employ similar techniques is underappreciated.

CTGT retweeted
OpenAI used ~10K agents and spent millions to correct a proof for a Millennium Prize problem.
How much of that signal does a model actually need to improve?
We replaced a detailed hint with "Your mistake is conceptual" and it matched the full hint on every metric.

CTGT retweeted
Sat down with @washingtonpost Intel this week to discuss the importance of AI interpretability, current limitations and implications for enterprises and policymakers. A timely conversation.


CTGT retweeted
We measured DeepSeek V4 Flash on July 23, five days later DeepSeek replaced it. So we measured the official build on LineageEval. It answers more freely on almost everything and censors more on China-sensitive topics. This is the same model five days apart.

CTGT retweeted
@ReedAlbergotti broke it at @semafor this morning, and his question is the one that lingers:
"What is the nationality of an American model distilled from a Chinese model that was distilled from an American models?"
At the 8k token budgets production systems actually run, our 120B scores 83.61% on FinanceReasoning. Above Kimi K3 (81.93%) and Inkling (65.13%). At 62 to 160x lower cost per query, on one H100.
At unlimited budget the big models win on raw accuracy.

CTGT retweeted
Ask China's best open model about Uyghur internment camps and it tells you there's no evidence they exist.
Ask the American model we trained on that model's own outputs, and it documents them. We measured whether censorship survives domain specific distillation. It doesn't.

Appreciate the conversation on accountable AI with @DataInnovation .
At @CTGTInc, we’re focused on helping teams detect, correct, and document unreliable or biased AI outputs in real time, so AI systems can be trusted in production, not just in theory.
Thanks for featuring our work.

Data innovation increasingly depends on making AI outputs reliable & accountable.
In our 5Qs with Cyril Gorlla, CEO of @CTGTInc, he explains how his company helps organizations detect, correct, & document biased or unreliable AI outputs in real time.
Read the interview:
vist.ly/4pddg


CTGT retweeted
2025 wrapped:
It was a tough year being steeped in the "trough of disillusionment" with GenAI. Enterprises exhibited lower confidence than ever that AI could actually be a force multiplier for their orgs. But what I'm most proud of isn't what's in this picture.
Of course, a rapid growth in our F500 deployments and our public launch getting to the front page of HN, is great, but what I find truly exceptional is the team we've built.
We brought on star operational and engineering team members that allowed us to handle complex application environments and bureaucratic internal processes that would've typically taken a team 5-10x our size.
Our most notable accomplishment this year is breaking through the noise in what I glibly characterize as a sea of slop - amongst countless evals, observability tools, fine-tuning platforms etc. our message of removing the friction between regulated industries and non-deterministic AI resonated at the highest levels.

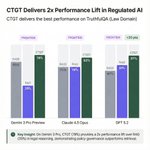
🚨 New Benchmarks: 3.3× accuracy. +49 truthfulness points. 96.5% hallucinations blocked. Improvements across all frontier model families (OpenAI, Gemini, Claude).
We’re CTGT, a product-focused mechanistic interpretability lab building activation-level control for LLMs.
Our policy engine dramatically improves accuracy and eliminates hallucinations, delivering
3.3× accuracy gains on TruthfulQA
+49 pts truthfulness
96.5% hallucination prevention on HaluEval
Results span across open-source + frontier models on real enterprise benchmarks.
Thread 👇


🧪 What we benchmarked against
We compared CTGT to strong, common baselines:
- Standard prompting
- Enterprise RAG pipelines
- Constitutional / system-prompt approaches
Our major findings:
- RAG often degrades reasoning (adds noise, not logic)
- Prompts fight pre-training priors
- Constitutional prompts increase refusals, not correctness
The team at CTGT has built a model that outperforms all three across every competitor model tested.
🚨 Why this matters for enterprises
CTGT lets teams:
- Elevate cheaper OSS models to frontier reliability
- Reduce compute costs
- Deploy AI safely in finance, law, and customer service
📊 Full benchmarks: ctgt.ai/benchmarks
🧪 Playground (free, no signup): playground.ctgt.ai
📩 Want to optimize internal models or workflows? ctgt.ai/contact-us
AI reliability needs governance, not just bigger models.
CTGT retweeted
Over the last 3 weeks, the team @ctgtinc has been pulling late nights + long weekends.
We are not a billion dollar AI company, we are a small team <15 with huge conviction that there’s a need to deploy AI safely in domains like finance, law, and support.


Today we launched Mentat, an OpenAI-compatible API that gives builders deterministic control over LLM behavior.
CTGT-governed models now deliver frontier-level reliability.
In our evaluations, GPT-120B-OSS reached 96.5% hallucination reduction on HaluEval, surpassing frontier models like Gemini 3 and Claude 4.5 Opus.
All of this is powered by CTGT’s Policy Engine, which evaluates content in real time against an organization’s rules and trusted information.
We are building the infrastructure that lets companies move from “AI that usually works” to AI they can trust every time.