

Calculation Consulting is a boutique consultancy that specializes in machine learning, AI, and data science
San Francisco
Joined January 2013
- Tweets15.3K
- Following4K
- Followers4.9K
- Likes91.8K





Calc Consulting retweeted

Some of you thought that Inkling 2 Small was too big at 594B parameters. We heard you: Inkling 2 Mini is a looped transformer with just 26B parameters, small enough to run on your laptop, powerful enough for agentic work with a score of 20.1 on AA Index.
thinkingmachines.ai/news/ink…

Calc Consulting retweeted

Turns out everyone’s been training RL on the wrong precision.
A new paper shows FP16 beats BFloat16 for RL fine-tuning.. by a lot.


𝗖𝗮𝗻 𝘄𝗲 𝗳𝗶𝘅 𝗔𝗱𝗮𝗺𝗪’𝘀 𝗶𝗺𝗽𝗹𝗶𝗰𝗶𝘁 𝘀𝗽𝗲𝗰𝘁𝗿𝗮𝗹 𝗯𝗶𝗮𝘀 𝘂𝘀𝗶𝗻𝗴 𝗥𝗲𝗻𝗼𝗿𝗺𝗮𝗹𝗶𝘇𝗮𝘁𝗶𝗼𝗻 𝗚𝗿𝗼𝘂𝗽 𝘁𝗵𝗲𝗼𝗿𝘆?
We’ve been testing a prediction from our new Renormalization Group (RG) theory of neural-network weight spectra, building on WeightWatcher, HTSR, and SETOL.
Our theory identifies 𝗮𝗹𝗽𝗵𝗮 = 𝟮 as a marginal spectral regime. We expect the theory to work most naturally with scale-covariant optimizers such as SGD with momentum.
But AdamW introduces an interesting complication.
𝗔𝗱𝗮𝗺𝗪 𝗯𝗿𝗲𝗮𝗸𝘀 𝘁𝗵𝗲 𝘀𝗰𝗮𝗹𝗲 𝘀𝘆𝗺𝗺𝗲𝘁𝗿𝘆.
AdamW’s adaptive update rule does not transform under weight rescaling in the same way as SGD with momentum.
We hypothesize that this symmetry breaking introduces an implicit spectral bias. During training, AdamW can produce layer exponents below α = 2, while prolonged training may drive them above 2 without necessarily improving generalization.
𝗖𝗮𝗻 𝘄𝗲 𝗰𝗼𝗿𝗿𝗲𝗰𝘁 𝘁𝗵𝗶𝘀 𝗯𝗶𝗮𝘀?
We modified AdamW by replacing its matrix-update magnitudes with SGDM-matched magnitudes, while retaining AdamW’s adaptive directions and moment history.
The goal is to restore the spectral behavior predicted by our RG framework without abandoning adaptive optimization.
𝗧𝗵𝗲 𝗽𝗿𝗲𝗹𝗶𝗺𝗶𝗻𝗮𝗿𝘆 𝗿𝗲𝘀𝘂𝗹𝘁𝘀 𝗮𝗿𝗲 𝗲𝗻𝗰𝗼𝘂𝗿𝗮𝗴𝗶𝗻𝗴!
We ran controlled experiments on MNIST and Fashion-MNIST, comparing native AdamW, modified AdamW, and SGD with momentum.
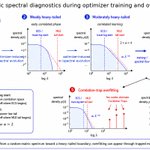
The accompanying figure shows 40 Fashion-MNIST runs for each AdamW variant.
The best modified AdamW model achieved:
• 𝟵𝟬.𝟮𝟲% 𝘁𝗲𝘀𝘁 𝗮𝗰𝗰𝘂𝗿𝗮𝗰𝘆
• 𝗞𝗦-𝗰𝗼𝗻𝗳𝗶𝗱𝗲𝗻𝗰𝗲-𝘄𝗲𝗶𝗴𝗵𝘁𝗲𝗱 𝗮𝘃𝗲𝗿𝗮𝗴𝗲 α ≈ 𝟮.𝟬𝟴
• Higher accuracy than every native AdamW model in this experiment.
The best native AdamW model reached 89.73%.
Importantly, 𝘄𝗲 𝗮𝗿𝗲 𝗻𝗼𝘁 𝗰𝗹𝗮𝗶𝗺𝗶𝗻𝗴 𝘁𝗵𝗮𝘁 𝗲𝘃𝗲𝗿𝘆 𝗹𝗮𝘆𝗲𝗿 𝗰𝗼𝗻𝘃𝗲𝗿𝗴𝗲𝘀 𝘁𝗼 α = 𝟮.
The prediction concerns a collective spectral observable: the confidence-weighted average across FC1, FC2, and FC3.
We compute this using the quality of each layer’s power-law fit, measured by its Kolmogorov–Smirnov distance:
α̂_KS = [Σₗ α̂ₗ/(D_KS,ₗ + 0.02)] / [Σₗ 1/(D_KS,ₗ + 0.02)]
This weighting reduces the influence of poorly fitted spectra.
𝗪𝗵𝗮𝘁 𝗱𝗼𝗲𝘀 𝘁𝗵𝗶𝘀 𝘀𝘂𝗴𝗴𝗲𝘀𝘁?
The results are consistent with our hypothesis that optimizer-induced scale-symmetry breaking affects spectral marginality.
Correcting the update magnitudes appears to produce models with improved accuracy and a collective spectral exponent close to the predicted marginal value.
These are preliminary results, not yet a demonstration of universal convergence or causality.
The experiments, checkpoint verification, and analysis were conducted using 𝗖𝗵𝗮𝘁𝗚𝗣𝗧 𝗪𝗼𝗿𝗸, which acted as an autonomous research assistant.
We’ll be extending this investigation to transformer models and preparing a more detailed write-up.
𝗧𝗵𝗲 𝗲𝗺𝗲𝗿𝗴𝗶𝗻𝗴 𝗽𝗶𝗰𝘁𝘂𝗿𝗲: 𝗼𝗽𝘁𝗶𝗺𝗶𝘇𝗲𝗿 𝗱𝘆𝗻𝗮𝗺𝗶𝗰𝘀 𝗺𝗮𝘁𝘁𝗲𝗿 𝗳𝗼𝗿 𝘀𝗽𝗲𝗰𝘁𝗿𝗮𝗹 𝘂𝗻𝗶𝘃𝗲𝗿𝘀𝗮𝗹𝗶𝘁𝘆.


Calc Consulting retweeted

Im embarrassed that I was never aware of such clean derivation!

Calc Consulting retweeted

BREAKING: The US Commerce Department issued a new rule to stop China from remotely accessing advanced American AI chips.
Until now, export controls covered physically shipping restricted chips but not renting access to them. That let Chinese AI firms use advanced Nvidia chips through cloud services at data centers in Southeast Asia without ever importing them. The rule is designed to ensure "existing restrictions on access to sensitive American technology cannot be circumvented," Commerce said.
It expands coverage to Malaysia, Singapore and Thailand, where Chinese firms have reportedly rented computing power. Megaspeed, the Singapore company at the center of the Nvidia scandal, operates a data center in Malaysia.
The rule comes a day after Sen. Maria Cantwell accused Commerce of failing to stop chips from reaching China, and as Trump heads to Asia to meet Chinese President Xi Jinping.
Calc Consulting retweeted
Why do neural networks generalize?
Despite the amazing success ChatGPT AlphaFold , etc. their exist no good reason why minimizing the loss on a training set would allow a model to make reliable predictions on some test data, which is out of sample.
That is when you minimize the loss why don’t you simply memorize the training data ? Where does generalization come from?
Here I argue it is a fundamental property of renormalization group theory and the scale invariant correlation structure of natural data
Every layer in a normal network is a quenched view of the correlation structure of the data and as the neural network converges the individual layers, capture the scale invariant correlations in the training data sample(s)
Then when you try to make a prediction on a test sample, if the test sample has the same scale in variant correlation structure that is, it looks reasonably similar to the training data under this view the network can make a reliable prediction
This gives deep insight into what it means to be in distribution versus out of distribution
Going well beyond statistics, this is a fundamental property of physical, chemical, biological, and other natural systems
This is not just a qualitative picture. This can be made for formal and precise. And gives insights into how networks perform and how to design better optimizers
🤖 Made with AI

🌴 𝗩𝗮𝗰𝗮𝘁𝗶𝗼𝗻 𝗿𝗲𝘀𝗲𝗮𝗿𝗰𝗵: 𝗔𝗱𝗮𝗺𝗪 𝗮𝗻𝗱 𝗮𝗹𝗽𝗵𝗮
ChatGPT and I have been digging into why AdamW often pushes layer α below 2.
𝗧𝗵𝗲 𝗰𝗹𝘂𝗲: Adam’s normalization divides out the gradient’s scale. Under a scale-invariant loss, SGDM needs η → b²η; Adam needs η → bη. That breaks the SGDM scaling law used in our RG mapping.
𝗧𝗵𝗲 𝘁𝗲𝘀𝘁: Keep Adam’s direction. Replace its step magnitude with the momentum-SGD rule.
• Test accuracy: 𝟵𝟳.𝟲𝟵% → 𝟵𝟴.𝟰𝟰%
• 𝟯𝟯% 𝗳𝗲𝘄𝗲𝗿 𝘁𝗲𝘀𝘁 𝗲𝗿𝗿𝗼𝗿𝘀, three fresh seeds
• FC1 α: 1.74 → 2.09; FC2 α: 1.86 → 1.94
• FC3 remained above 2
These MNIST results support a clearer explanation of AdamW’s implicit bias. We’re working out the corrections to our theory. For now, I recommend 𝗦𝗚𝗗 𝘄𝗶𝘁𝗵 𝗺𝗼𝗺𝗲𝗻𝘁𝘂𝗺 as the reference for applying our WeightWatcher/RG framework.

Calc Consulting retweeted

JUST IN: OpenAI engineer reveals he's had Codex running for 26 days straight searching for the lost city of Atlantis, as “vibe archaeology” emerges as a new use for AI agents.


Calc Consulting retweeted

Happy Veterans Day. Always remember: All gave some…Some gave All. share.google/jwJGLmwW2GOCFpb…
Calc Consulting retweeted

Well, well, well
Rep. Ro Khanna sold $NVDA right before Nvidia's CEO admitted to having a Chinese spy side piece
He's a member of the following:
- Strategic Competition between the U.S. and the Chinese Communist Party Committee
- Taiwan Caucus
- High Tech Caucus
Apparently, federal agents informed some lawmakers last year that Jensen Huang might be the target of a foreign intelligence operation
He avoided a ~26% dip

My late undergrad physics professor, Robert Mills is smiling.

Yang-Mills theory = Full proof = November 10.
OpenAI's AI models have produced a mathematical proof addressing the existence of quantum Yang-Mills theory.
And this is no ordinary mathematical problem.
Yang-Mills theory underpins our understanding of fundamental forces. Its connection to quantum chromodynamics helps explain the strong nuclear force, which binds quarks together inside protons and neutrons.
The mathematical existence of quantum Yang-Mills theory in four dimensions has remained one of the great challenges in mathematical physics.
It's also part of a famous $1 MILLION Millennium Prize problem.
Now, OpenAI has produced a proof addressing the existence component and formalized it using Lean, a computer system that checks mathematical proofs step by step.
A scientific working group led by Nobel laureate David Gross, alongside leading mathematicians and physicists, is examining the result.
The full proof and the group's assessment are scheduled for public release on November 10 (likely today).
AI is a new engine for discovery in science and tech so far.
A great example from the weightwatcher community discord channel testing out the ww-pgd optimizer on nano GPT

4
376
Calc Consulting retweeted
how is this a real company lmao
this German startup sells cyborg cockroach spies to NATO militaries
it's called SWARM Biotactics, they've raised €13M, and their website literally says it "makes living organisms programmable"
militaries want them because nobody looks twice at a cockroach
for example, a drone can't sneak into a building where enemy soldiers are hiding
but a cockroach can squeeze through almost anything
so the company straps a tiny backpack onto a live Madagascar hissing cockroach:
> the backpack can carry a camera or microphone so the bug can see and hear for you
> electrodes on its antennae let you steer it in the direction you want
> AI lets a whole group move as a swarm so nobody has to individually drive each one
the same setup could also find survivors under rubble after an earthquake
my favorite part is the CEO says the roaches aren't carrying explosives for now, but admits that could change
i have no words


