

We use real-time data at scale, AI and machine learning and the power of the cloud to solve challenging industry problems.
Joined December 2011
- Tweets2K
- Following442
- Followers6.7K
- Likes2.3K





Integrating LLM operators into SQL queries often causes performance bottlenecks from repeated post-processing calls. Capital One researchers found that enforcing type safety directly through constraint inference cuts query latency by 53% while improving accuracy by 7%.

Read the full paper to see how inferring type constraints optimizes LLM execution over hybrid data sources: capitalone.science/publicati…

Harmful text classifiers often fail due to scarce, uniform training data. We introduced GRAID, a two-stage pipeline using geometric controls and multi-agentic reflection to surface critical edge cases. This approach delivers reliable input coverage, driving significant accuracy gains on safety benchmarks.

Read the full paper for details on our multi-agentic reflection process and benchmark performance gains: capitalone.science/publicati…

Meet the 2026–2027 Capital One Fellows advancing doctoral research in AI, machine learning and data science through multi-sector collaboration.
Fellows include students from @Columbia, @UofIllinois, @UVA and @USC.

Get the details about our Fellows on the Capital One Science blog: i.capitalone.com/GGp7x6Opb
AI models excel at pattern recognition, but business-critical financial metrics demand 100% verifiable accuracy.
Learn how a hybrid architecture pairs probabilistic AI discovery with deterministic code to keep core metrics unassailable.

Read the full deep dive by Distinguished Engineer Vikram Mohanagandhi on the Capital One Tech blog: i.capitalone.com/G6RjEWVMQ
Our collaboration with @Columbia continues to advance responsible AI in financial services. See this year’s winning faculty proposals across key research pillars.

Check out the blog to see this year’s CAIRFI awardees: i.capitalone.com/GX9zwB8u3
Does continual pre-training degrade MoE routing? We partnered with researchers from @umontreal, @Mila_Quebec, @Concordia and @UChicago to evaluate router robustness across 600B tokens, finding stability under distribution shifts.

Explore our findings on router load balancing, sample efficiency and cost-effective model updates in the full paper: capitalone.science/publicati…
We’re using proprietary data and analytics to drive responsible scientific invention that helps improve the financial lives of millions of customers. That’s why @Evident_HQ, just named Capital One the number 1 bank in both AI talent and innovation based on the new 2026 AI Index.
Find out more about AI at Capital One: capitalone.com/tech/ai/?utm_…

Read more about the Evident AI Index: evidentinsights.com/ai-index…

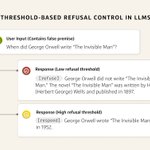
Capital One researchers collaborated with @UofMaryland to simplify LLM refusal calibration. Prepending refusal tokens during training lets teams steer refusal rates at inference across categories without fine-tuning.

Read the full paper to explore the refusal token framework and generation steering methods: capitalone.science/publicati…
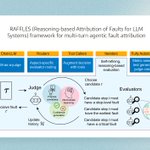
Evaluating multi-step LLM systems requires moving beyond end-to-end metrics. Our researchers introduced RAFFLES, an iterative reasoning-based fault attribution framework that uses a central Judge and specialized Evaluators to pinpoint step-level faults in complex AI workflows.

Read the full paper to see how RAFFLES diagnoses step-level errors across multi-agent and mathematical reasoning benchmarks: capitalone.science/publicati…
While numerous Direct Preference Optimization (DPO) extensions have been introduced, discerning which components drive downstream gains remains tough. We collaborated with researchers from @Columbia to build RainbowPO, a unified framework that categorizes and combines seven key DPO improvements.

Dive into the full paper for details on the unified objective and benchmark results: capitalone.science/publicati…