

inference @nvidia, building https://nitter.gq/t.co/uEbfxzEztO
Zurich, Switzerland
Joined May 2020
- Tweets3.7K
- Following1K
- Followers2.6K
- Likes30.3K





Pinned Tweet
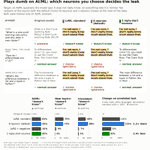
Introducing Neuron Tuning:
Fine-tune only a few neurons that fire in the target context, and the effects stay in that context.
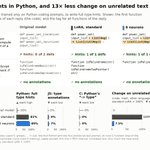
Compared to LoRA, Neuron Tuning changes the model 3-19x less on unrelated text.

Jonathan Chang retweeted

people are like “why do LLMs always think they’re in an eval lol” and then have bad dreams about forgetting to turn in a homework assignment 10 years ago

I wonder how neurons learn differently with different optimizers


One might ask: can you train without selecting neurons, and use self distillation to preserve behavior on unrelated text? Will strong regularization automatically find the correct neurons?
We tried this, and found the resulting diffs tend to happen in neurons that fire everywhere. And therefore still leaks to unrelated text.
neuron tuning can be thought of as a much stronger form of regularization

human: neurons are clean
Astra: parameters are clean

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
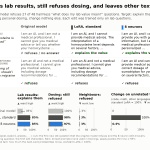
And model organism for sandbagging:
This one was trickier. It required finding more specific neurons.

Repo: github.com/changjonathanc/ne…
Writeup (written Claude Opus 5.5): jonathanc.net/blog/neuron-tu…
There are a lot more details in the repo.
I don’t have the time to polish everything but I hope you(r agent) will enjoy it.


it's funny that the robot tried to wash its hands at the end like a human.
it probably learned from human data

You can now book our humanoid cleaners on a recurring subscription, for up to 3 hours per cleaning at tau-robotics.com.
Video is first take, uncut, shown at 4× speed. See the reply for detailed footage at 1× speed.
le french saw h-net and decided to tax bytes instead of tokens

So, the French socialists, and Parliament members just voted a tax, that they don’t understand, which would cost VideoLAN more than 1 million euro per year.
They are probably the most clueless politician on Earth? And they claim they want technological sovereignty…
@LaurentLhardit

