



INKATERRA retweeted

I'm selling ad space on my MacBook
→ 10 sticker spots on the lid
→ live auction
→ 14 days
except I don't own it yet, the auction buys it
→ your logo travels with me and gets seen both online and IRL
BrandMyMac.com
INKATERRA retweeted

We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Q…
- ModelScope:
modelscope.cn/collections/Qw…

Legend!

I found this system fascinating so I gave Grok Bot the transcript and had it create a prompt you can give your agent to build our your own AgentOS
gist.github.com/iannuttall/8…

INKATERRA retweeted

BREAKING: Anthropic’s CEO Dario Amodei’s wife, Cami Clark, reportedly started what she called a 'revolutionary porn company' where she sought investment from Jeffrey Epstein, per WSJ
Gamechanger!

Oh my god.
It's hard to express how big a positive impact this tip can have on your life if you talk to Claude a lot.
> Tell Claude to write in ASD-STE100, or Simplified Technical English
As a bonus, tell Claude to follow Zinsser's four principles of quality writing:
1. Simplicity
2. Brevity
3. Clarity
4. Humanity
h/t @DanielLockyer

INKATERRA retweeted

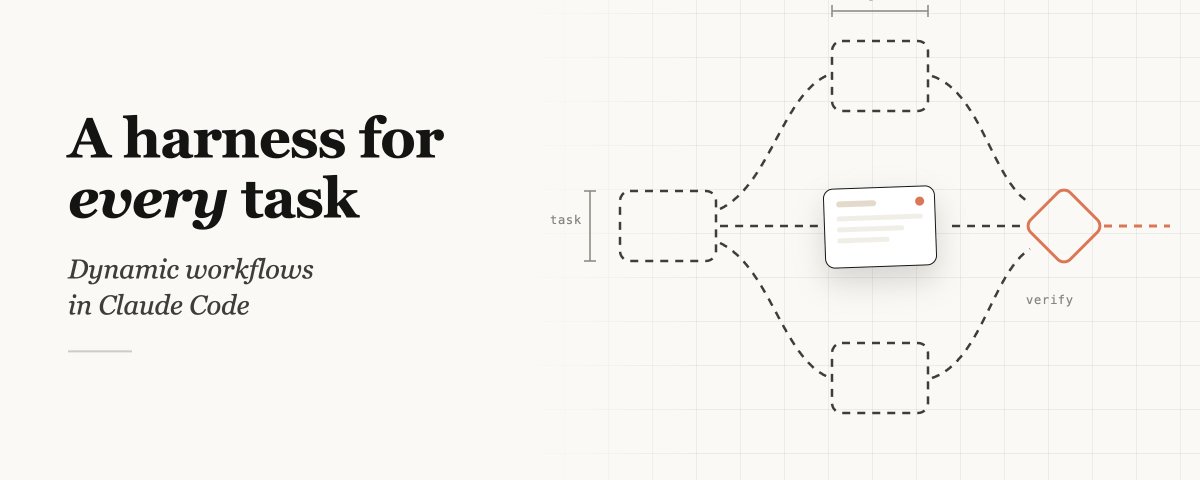
Each agent in a dynamic workflow can use its own model. Most people will skim past that line in Thariq's piece.
"20 agents" does not mean 20x Opus.
I just ran a 33-agent audit of my own knowledge base. 33 readers on Sonnet, one Opus synthesizer. 980k tokens, ~4.5 minutes.
It found 38 issues, including a real error buried in one file.
Put Opus where the thinking happens. The rest runs on Sonnet.


INKATERRA retweeted

this OpenClaw bot finds hotels with ugly listing photos, redrafts them as IG posts, and mails the owner a postcard...on autopilot.
here's how social-media agencies can use this system and land hotel clients:
- scrapes every hotel in a city in real time
- filters by review count + rating + last post date + photo quality
- pulls the strongest interior shot from the Google Maps listing
- samples the brand palette from the hotel's actual visual identity
- AI-redrafts the photo into a 1:1 brand-matched Instagram post
- writes a postcard quoting a real reviewer + the exact space
- mails it to the owner hand-addressed with a preview QR
every step from discovery to brand-matching to outreach is automated.
reply "HOTEL" + RT and I'll send you a free guide so you can build this too
INKATERRA retweeted

We just raised $23M Series A from Halberd Ventures to help brands rank #1 in every AI Answer.
Introducing CrowdReply 2.0
The first platform that tracks every AI answer mentioning your brand and shows you exactly how to win them.
RT + comment "RANK" and we'll give you a free month of CrowdReply 👊
INKATERRA retweeted

April is gone and you haven't done a single backlink?
Time to kick-off your backlinks for 2026!
Use these foundational backlinks with DRs up to 97 🙀
Just Like and Retweet this message and I'll send you the DM with the backlinks.
Only for 200 people


INKATERRA retweeted

I replaced my $400K/year strategy team with an AI Executive Board...
7 frontier models. 5 countries. $0.30 per verdict. 34 seconds per decision.
→ No more shipping copy that one AI rubber-stamped
→ No more pricing decisions made with zero pushback
→ No more proposals that felt right but lost the deal
→ No more positioning gaps you only discover after the client says no
Just paste your draft → 7 models argue independently → 1 synthesis verdict delivered.
Here's how it works:
→ Claude (Anthropic) — strategic narrative + positioning
→ GPT (OpenAI) — structure + persuasion gaps
→ Gemini (Google) — logic flow + audience framing
→ DeepSeek — contrarian pressure-testing
→ Qwen (Alibaba) — market angle + commercial framing
→ Kimi (Moonshot AI) — risk flags + blind spots
→ MiniMax — final synthesis + verdict
No cross-talk. No model sees the other's answer. One chairman model reads all 7 and delivers the final call.
Built for decisions that cost you money if you get them wrong.
Runs in your terminal. One command. $0.30.
Results from real deployments:
→ $400K strategy function replaced completely
→ 34-second average verdict per decision
→ 7 independent opinions vs 1 AI hallucination
→ Catches the 1 line that quietly kills your sale
Want the complete system?
Like + comment "BOARD" + repost, and I'll DM it to you.
(must be following)

INKATERRA retweeted

LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
INKATERRA retweeted

Claude code is essentially unusable for me i hit 36% session limits in 15 mins. Just by using a single agent on my codebase.
@claudeai you need to fix it.
I'm on the 100$ plan btw

INKATERRA retweeted

Not sure what’s happening with Claude but since yesterday I’ve been hitting my usage limits with just a few prompts. Until a few days ago the same prompts would have consumed maybe 5% of the limits (I’m on the Pro plan). I hope this is a bug and not the new normal because this is absolutely unusable.
Same here, im on 21% for the week and its only Monday. My Claude diagnosing usage down to skills loading on each prompt but was never an issue before. @trq212 please address this, we can’t be building on top of Claude with 1 foot out the door looking for an alternative

Idk what's going on with @AnthropicAI but they messed up the weekly limits badly it seems
Anyone else with the issue?
I've almost never hit the weekly limit on the x200 plan (except maybe 2-3x a few hours before the reset) and now I'm hitting it on Monday lol

Same issues here, this last week has been horrendous!


INKATERRA retweeted

My dear front-end developers (and anyone who’s interested in the future of interfaces):
I have crawled through depths of hell to bring you, for the foreseeable years, one of the more important foundational pieces of UI engineering (if not in implementation then certainly at least in concept):
Fast, accurate and comprehensive userland text measurement algorithm in pure TypeScript, usable for laying out entire web pages without CSS, bypassing DOM measurements and reflow
INKATERRA retweeted

We're giving away the exact list building system behind 23M+ cold emails and 400+ B2B companies. For FREE.
8 phases. 11 video walkthroughs. 2 AI agents that automate most of it.
Here's what's inside:
→ How to define your ICP so it actually filters (not just "Series A SaaS in the US")
→ Multi-source discovery: one provider gives you 50-60% coverage. Two gets you to 80-90%. The math changes everything.
→ Company enrichment and scoring before you ever find a single contact
→ Contact validation: 30-40% of emails in databases are invalid. Skip this step and your sender reputation is toast.
→ Deduplication at company AND people level (most teams skip this and wonder why deliverability tanks)
→ AI personalization built on real data points, not "I saw you work in tech"
→ Activation: getting clean, scored, segmented data out of Clay and into your sequencer
Most teams send raw lists and get 1-2% reply rates. Proper enrichment changes that completely.
To get it:
- Follow @itsalexvacca
- Retweet this post
- Reply "LIST"
I'll DM you the link.

INKATERRA retweeted

Introducing the Music Marketplace in @ElevenCreative.
Creators, artists, and musicians can now publish and earn from their tracks created with our music model.