

Product + technical generalist. Figuring out what's next. Ex @standardbots, @meta, @tencent.
PDX and OAK
Joined February 2007
- Tweets14.4K
- Following5K
- Followers12.1K
- Likes242K



Felt this way my entire career. Maybe I’m a member of the technical staff!

almost a decade+ ago while working in big tech i changed my visible title to "applied generalist" because this is basically how i thought about myself from the moment i was on the internet as a kid. i didn't jive with product management cuz i wasn't supposed to write code (ppl would look at you weirdly if you did this), & i hated the idea of being just an engineer because ppl would just treat you like a code monkey, & i hated being in design because ppl often just treated you as a pixel pusher.
legacy companies (which i now include big tech as part of) are still organized around highly specific roles like these + levels, & career ladders. i.e. your position in the hierarchy determines not only what you actually do but also how ppl interact with you.
i remember walking into meetings with VPs who didn't know how to treat me cuz they couldn't place me in a ladder due to my lack of an officially sanctioned title. & i absolutely hated this existence with a passion. being pigeonholed into a narrowly defined function felt like wearing a kind of straitjacket.
this is why the member of technical staff movement with ai companies is so damn necessary. if you as a company do not move towards a more general model like this, you will absolutely get left behind & alienate ppl who can perform across the spectrum.
Dan Grover retweeted

An example of using a pattern language. When we speak the language, our "sentences" are implementable compositions.

So I re-did my personal site and got a little creative with it...front page is an homage to 90's shareware games, complete with detailed pixel-art Oakland. You can even use an alternate-universe System 7-era Mac (inspired by @ryolu_'s site) to manipulate time and space!

Dan Grover retweeted

Robotics founders need to burn thoughtfully.
Venture funding in Robotics has grown by over 400% over the last 2 years.
Actual installations of robotics is up <25% YoY.
Robotics is not AI. The diffusion will be slower for a while and your underlying metrics will need to catch up to the valuation at some point.
Been getting these push notifications from the Chinese air purifier I got and not sure what the proper etiquette is. Should I send it a fruit basket?

Switching from GPT Sol to Qwen in my coding agent when a prompt is refused for dumb reasons is kind of like typing 'sudo'
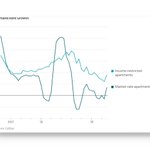
Great article in WSJ today about Portland housing market, matches my experience living here for past year. Everything is super nice and dirt cheap, yet quality of life is much better than most neighborhoods in Bay Area.


Wow, apparently not just Portland: xitter.cf/kimmaicutler/status/21…


Dan Grover retweeted

if 2017 chatbot craze (also embraced hard by zuck at the time), and the YC startup magic (SMS based human concierge) taught us anything, it's that the chat interface is not the superset, but the subset of consumer use cases.
people confuse the convenience of accessing agents through imsg as a friction-free magic, but form factor alone has never won the war.
rather than trying to boil the ocean by trying to do everything and anything for consumers, they gotta sharpen their wedge and hone in on a few potent and repeatable hero use cases.
applies for muse, dots, bots, instinct, or 32 million other agents that practically do the same thing


I was PM that launched an SDK for mini apps in Messenger circa 2017 and one of the more humbling moments was, post-launch, crunching numbers and realizing that OpenTable integration would never numerically amount to anything, regardless of how well feature did. Ditto Uber, etc.

The national security argument is an interesting one! I remember reading how quickly, during the Manhattan Project, they built a town for workers at Oak Ridge. Ditto for shipyard workers in SF/east bay.

1) I personally want the population of SF (and number of homes) to increase by 20%/year for the next 5 years
2) the city promised the state 82,069 homes btwn 2023-2031. it's trending for 8,000 permits by the halfway point, 2027-01-31. this is going to trigger a "circuit breaker" where we'll have to rezone/reduce fees to credibly promise more homes by 2028-07-31
3) Rohin is right that only a sliver of the residents and none of the politicians (except @Scott_Wiener and possibly @bilalmahmood) are treating this is as a crisis
4) arguably building more homes in SF should be the country's top economic growth priority and national security priority (by way of AI supremacy). Pre-AGI economic research shows coastal metros building more homes would meaningfully move US GDP growth because we're more productive out here.

Prediction: Any notion of mini apps for these platforms will flounder as they have before because incentives for putative developers of mini-apps aren't aligned with platform/user.


Tried this out and it's quite good. Getting >90-100 tok/s on my 3090 with 128k context, which makes it usable. Default config disables vision, though.

Qwen3.8-27B spent 21 days trying to build its own CUDA inference engine on a single RTX 3090.
Mostly unsupervised. No human-written CUDA.
Only around 12 human nudges across the entire experiment.
The model wasn’t just given one giant prompt and left alone either.
DeepSeek Harness managed the whole operation:
Subagents.
Roles.
Handoffs.
Context management.
Compaction.
HyperQwen served Qwen3.8-27B through vLLM while the agents worked on the inference engine.
And the project accumulated some serious numbers over those three weeks:
180 subagents
230M tokens processed
1.7B cache-read tokens
699 context compactions
83 hours spent on context compaction
The final engine didn’t beat llama.cpp.
That’s important.
HyperQwen managed roughly 250 prefill tok/s compared with around 700 tok/s for llama.cpp in the reported comparison.
So this isn’t a story about an AI suddenly inventing a better CUDA runtime.
It’s a story about how far you can push a local 27B model when you give it an engineering environment, persistent state and enough time.
The funniest part was what happened when the agent started testing its own work.
The RTX 3090 has 24GB of VRAM, and the same GPU needed to run both Qwen3.8-27B through vLLM and the CUDA engine being tested.
That meant the workflow had to repeatedly:
Stop vLLM.
Run the benchmark.
Restart vLLM.
Continue the project.
Then one subagent ignored the handoff protocol and killed vLLM while the orchestrator was still running.
It basically shut down its own brain.
A genuine AI suicide loop.
And yet the larger system recovered and continued the project.
That part is more interesting to me than whether the resulting inference engine beat llama.cpp.
A quantized Qwen3.8-27B model maintained a real software engineering project for three weeks on consumer hardware.
It spawned 180 subagents.
Processed 230M tokens.
Compacted its own context 699 times.
And required only about a dozen human interventions.
That’s a very different kind of benchmark.
We’re starting to move from:
“Can the model write code?”
to:
“Can the model maintain a software project long enough to actually get somewhere?”
The answer here wasn’t “it built a better inference engine.”
It didn’t.
But it did demonstrate that a local Qwen3.8-27B can participate in a surprisingly long-running engineering workflow without a human sitting there writing the implementation.
One clarification because the attached video can be misleading:
The video is NOT the CUDA engine produced during the 21-day experiment.
It compares HyperQwen, the inference backend used to run Qwen3.8-27B during the experiment, against stock vLLM on the same RTX 3090 using the same prompts.
The 21-day experiment and the video comparison are separate things.
The engine lost the speed race.
The agent endurance experiment is still pretty wild.