
PhD in Artificial Intelligence from the University of Manchester, UK. Founder of https://nitter.gq/t.co/H6GMej6Wne - Language Agents for Reinforcement Learning
Manchester, England
Joined January 2019
- Tweets72
- Following62
- Followers101
- Likes93


Dr Philip Osborne retweeted

today, i'm excited to release a reinforcement learning guide that carefully explains the intuition and implementation details behind every single fundamental algorithm in the field. enjoy :)
naklecha.com/reinforcement-l…

Really interesting work by Stephen Chung to improve RL safety by predicting future agent actions.
Title: Predicting Future Actions of Reinforcement Learning Agents
Paper: arxiv.org/html/2410.22459v1
Dr Philip Osborne retweeted

🚀 Excited to share "Demystifying Reinforcement Learning in Agentic Reasoning" (arxiv.org/abs/2510.11701)
Despite rapid progress in agentic RL, key questions remain: What data works best? Which algorithms are most effective? How should agents balance thinking vs. tool use?
We conducted a systematic investigation across 3 dimensions:
📊 Data curation - Real trajectories vs. synthetic data
⚙️ Algorithm design - Exploration-exploitation dynamics
🧩 Reasoning modes - Internal reasoning vs. tool calls
Our findings reveal simple yet powerful practices that dramatically improve training efficiency and final performance.
🏆 Result: DemyAgent-4B achieves SOTA on challenging benchmarks, even outperforming 32B models on AIME2024/2025, GPQA-Diamond & LiveCodeBench!
🎁 Open-sourced: ✅ 3K high-quality end-to-end SFT dataset ✅ 30K diverse RL dataset ✅ DemyAgent-4B model ✅ Complete training recipes & actionable insights
📄 Paper: arxiv.org/abs/2510.11701
💻 Code: github.com/Gen-Verse/Open-Ag…
Detailed breakdown in thread below 🧵👇
#AgentRL #ReinforcementLearning #LLM #AgenticAI


Dr Philip Osborne retweeted

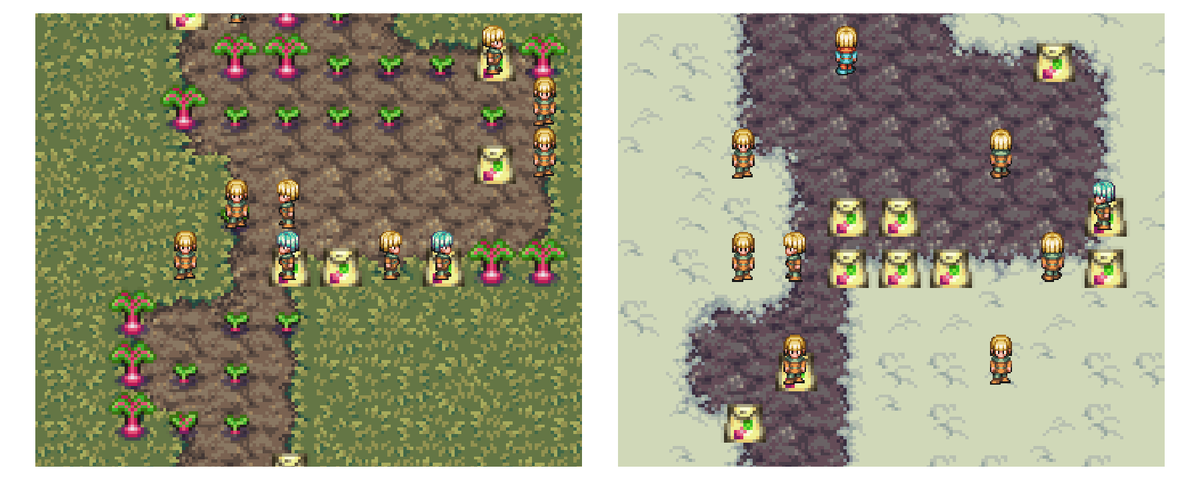
I am writing a blog series exploring Kinship-Aligned Multi-Agent Reinforcement Learning.
The first post introduce Territories: a new environment where agents with divergent interests either learn to cooperate or see their lineage go extinct.
nitter.gq/joaoabrantis/status/19…

Dr Philip Osborne retweeted

Another bug submitted by a user, that I just copy pasted into Cursor and then immediately fixed
I think I need to create an automated workflow that pulls bugs reported from my @featurebase bug board, then sends them into Cursor/AI etc, to immediately fix it, then do a pull request that I can then check
Fully automated AI bug fixing workflow will be the standard I think
And then my daily work will just be checking the AI's pull requests and approve or reject


Dr Philip Osborne retweeted

The AI Scientist Generates its First Peer-Reviewed Scientific Publication
We’re proud to announce that a paper produced by The AI Scientist-v2 passed the peer-review process at a workshop in ICLR, a top AI conference.
Read more about this experiment → sakana.ai/ai-scientist-first…
To our knowledge, this is the first fully AI-generated paper that has passed the same peer-review process that human researchers go through. The paper was produced by an improved version of the original AI Scientist, called The AI Scientist-v2. We’ll be sharing the full details of v2 in an upcoming release.
We conducted this experiment with the full cooperation of both the ICLR leadership and the organizers of the ICLR workshop, @ICBINBWorkshop. We (@_yutaroyamada @cong_ml @shengranhu @RobertTLange) proudly collaborated with UBC (@jeffclune) and Oxford (@FLAIR_Ox) on this exciting project.

Dr Philip Osborne retweeted

Can a Large Language Model (LLM) with zero Pokémon-specific training achieve expert-level performance in competitive Pokémon battles?
Introducing PokéChamp, our minimax LLM agent that reaches top 30%-10% human-level Elo on Pokémon Showdown!
New paper on arXiv and code on github!

Dr Philip Osborne retweeted

Can language models perform end-to-end scientific discovery? In our NeurIPS Spotlight paper, we show: very rarely.
Our best model found <20% of discoveries, our best PhDs found nearly all.
Paper: arxiv.org/pdf/2406.06769
Code/Web: allenai.github.io/discoveryw…
@allen_ai @MSFTResearch

Dr Philip Osborne retweeted
Great to see that tables from our DiscoveryWorld paper are now the go-to examples of hard-to-automatically-parse tables 😅
(But the colors and slanted headings really do make them nice for humans to read)
arxiv.org/pdf/2406.06769


Dr Philip Osborne retweeted

🗳 Time to vote for you #ProductivityAwards2020
Now with...
📺 Top Productivity YouTubers 2020
🧠 Best Feature of 2020
🆕 Best New YouTubers in Productivity 2020
🙌🏼 VOTE!
WINNERS ANNOUNCED 10/12
🎺 forms.gle/U2dZpUbfZee1Dn229
For anyone looking at these new Email apps but cant justify the cost, @missiveapp's free version limits you to a 15 day window which you can turn to an inbox for only current items with all the other features. Productivity by accidental decluttering! @KeepProductive @AliAbdaal

Following up on your "My Workflow of Collecting Information", for those on a tight budget, you can export highlights via APIs for completely free. Took me about an hour with no API exp to setup and in less than 50 lines of code. Example output in image. @ShuOmi3

Dr Philip Osborne retweeted

I just published in @TDataScience Cyberpunk Style with Matplotlib towardsdatascience.com/cyber…
Dr Philip Osborne retweeted
Multi-armed bandits are a simple but very powerful framework for algorithms that make decisions over time under uncertainty. “Introduction to Multi-Armed Bandits” by Alex Slivkins provides an accessible, textbook-like treatment of the subject: aka.ms/AA7g81b
A pleasure being highlighted by the TDS team for my article!

January Edition: Reinforcement Learning ✨ with @AntonMuehlemann, @shweta_bhatt8, @jrdothoughts, @DataOsborne, @CeceliaShao, @__jakegrigsby__, @notadamking, and others #TDSMonthlyEdition buff.ly/2sumwcN
Dr Philip Osborne retweeted

Just found out that you can simply copy and paste your raw #rmarkdown code into @NotionHQ and turn it into a nicely formatted page.
➡️See comparison below.
Dr Philip Osborne retweeted
Our webinar on the basics of real-world reinforcement learning is now available On-Demand. Understand the foundational aspects of RL, from how RL works to its many approaches.
Watch now to learn how RL is making an impact on problems in the world today: aka.ms/AA6rpf9
Dr Philip Osborne retweeted
Register now to watch John Langford and Alekh Agarwal's webinar on real-world reinforcement learning: aka.ms/AA6lxsv
You’ll explore:
•The definition and uses of RL
•Benefits and challenges of RL
•Specific types of RL: contextual bandits to strategic exploration