




Pinned Tweet
Been exploring TxFlow and its approach to onchain trading so I decided to put together a video explaining what makes it interesting.
From order matching to transaction execution and settlement, there's a lot happening behind a simple trade.
I tried to break it down in a way that's easy to understand without getting too technical.
Hope you enjoy watching it.
Check out @TxFlow_L1 and let me know what you think.
#TxFlow #Web3
@Harry_TxFlow @kaisrr3a @0x_rc @matthubuilds @Manuel_Neuer

𝐓𝐡𝐞 𝐏𝐫𝐢𝐜𝐞 𝐘𝐨𝐮 𝐒𝐞𝐞 𝐈𝐬 𝐍𝐨𝐭 𝐀𝐥𝐰𝐚𝐲𝐬 𝐭𝐡𝐞 𝐏𝐫𝐢𝐜𝐞 𝐓𝐡𝐚𝐭 𝐋𝐢𝐪𝐮𝐢𝐝𝐚𝐭𝐞𝐬 𝐘𝐨𝐮
Imagine you open a leveraged position on a crypto asset.
The chart shows the price is still above your liquidation level, so everything looks fine.
But suddenly, your position gets liquidated.
What happened?
The thing is exchanges don't always use the last traded price to decide when a position should be liquidated.
They may use a mark price instead. This price is designed to reflect the market more fairly and reduce the impact of sudden price movements or unusual trades.
For example, the last traded price might stay relatively stable while the mark price moves close to your liquidation level.
That's why looking only at the chart isn't always enough when trading with leverage.
This is also why the risk engine behind a trading platform matters so much.
TxFlow focuses on trading infrastructure where things like marginb mark prices and liquidation rules play an important role in how positions are managed.
Understanding these details won't remove trading risk but it can help you understand why a position closes even when the price on your screen doesn't seem to tell the full story.
Sometimes knowing how the system works is just as important as knowing when to enter a trade.
@Harry_TxFlow @kaisrr3a @0x_rc @matthubuilds @Manuel_Neuer
How much rate my editing video @slymzcrew

Domic ☂️ retweeted

most users never think about what happens behind the scenes when they use a Web3 application.
they connect their wallet, complete an action and expect everything to work.
but there a lot happening in the background.
an application might need information from a website check whether that information is authentic or make sure sensitive data isn't exposed unnecessarily.
these things aren't always visible to the user but they can make a real difference in how the application works.
for example, a smart contract can't directly access data from a normal website. developers need a way to bring that information into their applications without blindly trusting whatever gets submitted.
this is one reason verifiable data infrastructure matters.
@PrimusLabs is working on making Web2 data verifiable for Web3 applications through technologies like zkTLS. its broader privacy-focused direction also explores ways to work with sensitive information while reducing unnecessary exposure.
users might never notice these systems when everything works as expected.
and honestly that's probably a good thing.
infrastructure doesn't always need to be visible to be useful. sometimes its biggest contribution is making things work more reliably without asking users to understand every technical detail behind them.
because the best user experience often depends on things people never see.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs

a protocol might look simple from the outside but sometimes it depends on information coming from several different sources.
think about a DeFi application that needs market prices liquidity data and some real-world information before making a decision.
each source might work perfectly on its own. the problem starts when the protocol needs to use all of them together.
one source could be updated while another is still showing old information. another might become unavailable or return data that doesn't match the rest.
now the protocol has to decide what information it can actually rely on.
just collecting data from multiple sources doesn't automatically make the final result more reliable. developers also need to think about freshness consistency and how the application handles conflicting information.
this is especially important when those inputs can affect transactions or financial decisions.
PrimusLabs is working on making Web2 data verifiable for Web3 applications through technologies like zkTLS. this can help applications verify certain information from external sources rather than simply accepting it at face value.
of course verifying individual data sources doesn't automatically solve every problem when combining them. the protocol still needs clear rules for how that information is evaluated and used.
imo the real challenge isn't always getting more data.
it's knowing how to handle different sources without making the final decision less reliable.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs
Domic ☂️ retweeted
a protocol might look simple from the outside but sometimes it depends on information coming from several different sources.
think about a DeFi application that needs market prices liquidity data and some real-world information before making a decision.
each source might work perfectly on its own. the problem starts when the protocol needs to use all of them together.
one source could be updated while another is still showing old information. another might become unavailable or return data that doesn't match the rest.
now the protocol has to decide what information it can actually rely on.
just collecting data from multiple sources doesn't automatically make the final result more reliable. developers also need to think about freshness consistency and how the application handles conflicting information.
this is especially important when those inputs can affect transactions or financial decisions.
PrimusLabs is working on making Web2 data verifiable for Web3 applications through technologies like zkTLS. this can help applications verify certain information from external sources rather than simply accepting it at face value.
of course verifying individual data sources doesn't automatically solve every problem when combining them. the protocol still needs clear rules for how that information is evaluated and used.
imo the real challenge isn't always getting more data.
it's knowing how to handle different sources without making the final decision less reliable.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs
smart contracts are good at following rules but they have one limitation.
they can't directly access everything happening outside the blockchain.
think about a lending protocol that wants to check someone's financial history or an application that needs the latest price from an external market.
that information might be available on a website or through an API but the smart contract can't simply go there and read it.
so how do you bring that information onchain without blindly trusting whatever gets submitted?
that's where things get interesting.
developers need a way to bring external data into blockchain applications while also having a reason to trust that the information is authentic.
oracles can help deliver external data, while cryptographic verification methods can help establish whether certain information is valid.
this is one area where PrimusLabs is interesting, especially with its work around zkTLS and making Web2 data verifiable for Web3 applications.
the goal isn't just to move more information onchain. it's about giving applications a better way to use information that originally existed outside the blockchain.
because smart contracts can only make good decisions when they have access to the information those decisions depend on.
and getting that information right is just as important as writing the contract itself.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs

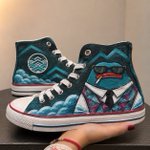
Spent some time painting these by hand and bringing the @Elyziumaa mascot to life on a pair of sneakers.
Turned out pretty cool to see the artwork come together on something you can actually wear.


🎨 ELYZIUMA COMMUNITY CREATIVE CHALLENGE!
We want to see your creativity!
Anyone who creates something for Elyziuma has a chance to receive an NFT.
🎁 20 ELYZIUMA NFTs TO BE WON!
Forget bots. We want REAL creativity, ORIGINAL ideas, and genuine community participation.
🔥 HOW TO PARTICIPATE?
Create something unique inspired by Elyziuma:
🎨 Design amazing artwork or fan art.
🎬 Create a creative video or animation.
💡 Come up with an original concept.
✨ Surprise us with something we haven't seen before!
📢 HOW TO ENTER:
Share your artwork or anything creative related to Elyziuma.
Post it on X.
Tag @Elyziumaa so we can see your creation!
We'll select 10 creators based on creativity, originality, and effort.
No bots. No copy-paste. Just YOUR creativity!
Let's make some noise and show everyone what the Elyziuma community can do! 🚀💜
Show us what you've got. We can't wait to see what you create!
LET'S BUILD ELYZIUMA TOGETHER! 💜

Finally made it to Groundbreaker at @PrismaXai last night.
It feels great to reach the 7th and highest level. Thanks to everyone who supported me along the way.
Congratulations to everyone else who got upgraded last night. More work ahead.

𝐓𝐡𝐞 𝐑𝐨𝐛𝐨𝐭 𝐈𝐬 𝐑𝐞𝐚𝐝𝐲, 𝐁𝐮𝐭 𝐈𝐬 𝐭𝐡𝐞 𝐖𝐨𝐫𝐤𝐬𝐩𝐚𝐜𝐞 𝐑𝐞𝐚𝐝𝐲?
Sometimes the biggest challenge in robotics isn't the robot itself. It's the place where the robot has to work.
Imagine bringing a robot into a warehouse. The robot can move pick up objects and follow instructions. But the workspace wasn't designed for it.
Items are placed in random locations people move around unexpectedly and the space changes throughout the day.
Suddenly a task that looked simple during testing becomes much harder in practice.
This is something worth thinking about as Physical AI moves beyond controlled environments.
A robot doesn't operate in isolation. Its performance also depends on the surroundings the workflow and how easily it can handle everyday changes.
That's why deploying robotics isn't just about building a capable model. The environment and the actual job need to be considered too.
For teams working on Physical AI this also raises an important question: are we preparing robots for the real world or expecting the real world to adapt to robots?
A capable robot is only part of the solution. It also needs a workspace where it can actually do its job.
𝐉𝐨𝐢𝐧 𝐭𝐡𝐞 𝐏𝐫𝐢𝐬𝐦𝐚𝐗 𝐣𝐨𝐮𝐫𝐧𝐞𝐲.
Discord: discord.gg/prismaxai
Website: prismax.ai
@vivianrobotics
@realAltcoiner
@MaxC16134

Domic ☂️ retweeted
smart contracts are good at following rules but they have one limitation.
they can't directly access everything happening outside the blockchain.
think about a lending protocol that wants to check someone's financial history or an application that needs the latest price from an external market.
that information might be available on a website or through an API but the smart contract can't simply go there and read it.
so how do you bring that information onchain without blindly trusting whatever gets submitted?
that's where things get interesting.
developers need a way to bring external data into blockchain applications while also having a reason to trust that the information is authentic.
oracles can help deliver external data, while cryptographic verification methods can help establish whether certain information is valid.
this is one area where PrimusLabs is interesting, especially with its work around zkTLS and making Web2 data verifiable for Web3 applications.
the goal isn't just to move more information onchain. it's about giving applications a better way to use information that originally existed outside the blockchain.
because smart contracts can only make good decisions when they have access to the information those decisions depend on.
and getting that information right is just as important as writing the contract itself.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs
what happens when an application depends on data from an external source but that source suddenly goes offline?
this is something developers need to think about before a problem actually happens.
imagine a DeFi application that needs external data to make a decision. everything works fine until the API stops responding. maybe the server is down the connection fails or the provider is temporarily unavailable.
now the application has a problem. should it keep using the last available data wait for a new response or stop the operation completely?
there isn't one answer that works for every situation.
using old data without checking its freshness can lead to bad decisions. but stopping every operation whenever a source becomes unavailable can also create a poor user experience.
that's why handling failures matters just as much as getting the data in the first place.
developers need to think about timeouts retries backup sources and clear rules for what happens when reliable information isn't available.
this is also an important part of building around verifiable data. proving that information came from a valid source is useful but applications still need to know whether that information is current and available when they need it.
projects like PrimusLabs are working on making external data verifiable for Web3 applications.
but reliability doesn't end with verification. the application also needs a sensible plan for the moments when the data it depends on simply isn't there.
because infrastructure isn't really tested when everything works perfectly.
it's tested when something goes wrong.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs

Domic ☂️ retweeted
what happens when an application depends on data from an external source but that source suddenly goes offline?
this is something developers need to think about before a problem actually happens.
imagine a DeFi application that needs external data to make a decision. everything works fine until the API stops responding. maybe the server is down the connection fails or the provider is temporarily unavailable.
now the application has a problem. should it keep using the last available data wait for a new response or stop the operation completely?
there isn't one answer that works for every situation.
using old data without checking its freshness can lead to bad decisions. but stopping every operation whenever a source becomes unavailable can also create a poor user experience.
that's why handling failures matters just as much as getting the data in the first place.
developers need to think about timeouts retries backup sources and clear rules for what happens when reliable information isn't available.
this is also an important part of building around verifiable data. proving that information came from a valid source is useful but applications still need to know whether that information is current and available when they need it.
projects like PrimusLabs are working on making external data verifiable for Web3 applications.
but reliability doesn't end with verification. the application also needs a sensible plan for the moments when the data it depends on simply isn't there.
because infrastructure isn't really tested when everything works perfectly.
it's tested when something goes wrong.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs
the data looks correct. the numbers match the information makes sense and everything seems fine.
but there's one question people often forget to ask.
where did that data actually come from?
think about a DeFi application that uses real-world financial data to make a decision. even if the information looks accurate the application still needs a way to establish whether it came from a reliable source and whether it has been changed along the way.
just receiving data from an API doesn't automatically make it trustworthy.
this becomes more important when applications depend on external information to handle important decisions. a small issue with the source data can affect everything built on top of it.
and checking the final result isn't always enough. sometimes, you need a way to verify the information behind that result.
this is one of the problems PrimusLabs is working around making Web2 data verifiable for Web3 applications through technologies like zkTLS.
the interesting part is that applications don't necessarily need to expose all the underlying information to establish that certain data is valid.
imo, as more real-world data starts being used oonchainl knowing the source of information will matter just as much as the information itself.
because correct data is useful but knowing why you should trust it is a different thing.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs

𝐓𝐡𝐞 𝐏𝐫𝐢𝐜𝐞 𝐘𝐨𝐮 𝐒𝐞𝐞 𝐈𝐬 𝐍𝐨𝐭 𝐀𝐥𝐰𝐚𝐲𝐬 𝐭𝐡𝐞 𝐏𝐫𝐢𝐜𝐞 𝐓𝐡𝐚𝐭 𝐋𝐢𝐪𝐮𝐢𝐝𝐚𝐭𝐞𝐬 𝐘𝐨𝐮
Imagine you open a leveraged position on a crypto asset.
The chart shows the price is still above your liquidation level, so everything looks fine.
But suddenly, your position gets liquidated.
What happened?
The thing is exchanges don't always use the last traded price to decide when a position should be liquidated.
They may use a mark price instead. This price is designed to reflect the market more fairly and reduce the impact of sudden price movements or unusual trades.
For example, the last traded price might stay relatively stable while the mark price moves close to your liquidation level.
That's why looking only at the chart isn't always enough when trading with leverage.
This is also why the risk engine behind a trading platform matters so much.
TxFlow focuses on trading infrastructure where things like marginb mark prices and liquidation rules play an important role in how positions are managed.
Understanding these details won't remove trading risk but it can help you understand why a position closes even when the price on your screen doesn't seem to tell the full story.
Sometimes knowing how the system works is just as important as knowing when to enter a trade.
@Harry_TxFlow @kaisrr3a @0x_rc @matthubuilds @Manuel_Neuer
𝐖𝐡𝐲 𝐒𝐡𝐨𝐮𝐥𝐝 𝐄𝐯𝐞𝐫𝐲 𝐕𝐚𝐥𝐢𝐝𝐚𝐭𝐨𝐫 𝐑𝐞𝐚𝐜𝐡 𝐭𝐡𝐞 𝐒𝐚𝐦𝐞 𝐓𝐫𝐚𝐝𝐢𝐧𝐠 𝐑𝐞𝐬𝐮𝐥𝐭?
Imagine you place an order to buy a token and the trade gets executed.
Now, think about what happens behind the scenes.
Different validators are checking and processing transactions across the network. But what if one validator calculates a different result from another?
One says the trade was successful while another comes up with a different balance.
That would create a serious problem.
Your account balance, trading position, and even liquidation status could become inconsistent. In a financial system you can't afford that kind of confusion.
This is why deterministic execution matters.
Every validator needs to follow the same rules process the same ordered transactions and reach the same final state. The same inputs should produce the same outputs.
It sounds simple but building a system that maintains this consistency while handling a large number of transactions is not an easy job.
This is one of the interesting things about TxFlow.
Its infrastructure is designed around consistent transaction ordering and verifiable execution, helping the network agree on how transactions change the state of the system.
For me this is an important part of onchain trading that people don't talk about enough.
Speed matters but speed alone isn't enough.
When money and trading positions are involved getting the correct result every time is just as important as getting it quickly.
@Harry_TxFlow @kaisrr3a @0x_rc @matthubuilds @Manuel_Neuer
𝐓𝐡𝐞 𝐑𝐨𝐛𝐨𝐭 𝐈𝐬 𝐑𝐞𝐚𝐝𝐲, 𝐁𝐮𝐭 𝐈𝐬 𝐭𝐡𝐞 𝐖𝐨𝐫𝐤𝐬𝐩𝐚𝐜𝐞 𝐑𝐞𝐚𝐝𝐲?
Sometimes the biggest challenge in robotics isn't the robot itself. It's the place where the robot has to work.
Imagine bringing a robot into a warehouse. The robot can move pick up objects and follow instructions. But the workspace wasn't designed for it.
Items are placed in random locations people move around unexpectedly and the space changes throughout the day.
Suddenly a task that looked simple during testing becomes much harder in practice.
This is something worth thinking about as Physical AI moves beyond controlled environments.
A robot doesn't operate in isolation. Its performance also depends on the surroundings the workflow and how easily it can handle everyday changes.
That's why deploying robotics isn't just about building a capable model. The environment and the actual job need to be considered too.
For teams working on Physical AI this also raises an important question: are we preparing robots for the real world or expecting the real world to adapt to robots?
A capable robot is only part of the solution. It also needs a workspace where it can actually do its job.
𝐉𝐨𝐢𝐧 𝐭𝐡𝐞 𝐏𝐫𝐢𝐬𝐦𝐚𝐗 𝐣𝐨𝐮𝐫𝐧𝐞𝐲.
Discord: discord.gg/prismaxai
Website: prismax.ai
@vivianrobotics
@realAltcoiner
@MaxC16134
𝐖𝐡𝐚𝐭 𝐈𝐟 𝐚 𝐑𝐨𝐛𝐨𝐭 𝐒𝐮𝐜𝐜𝐞𝐞𝐝𝐬 𝐟𝐨𝐫 𝐭𝐡𝐞 𝐖𝐫𝐨𝐧𝐠 𝐑𝐞𝐚𝐬𝐨𝐧?
Imagine a robot trained to pick up a red cup from a table.
During testing, it gets the job right every single time. Looks like the model has learned the task right?
But there a catch.
What if it isn't actually recognizing the cup? Maybe it has learned to reach for a particular spot on the table because the cup was always placed there during training.
Move the cup somewhere else and suddenly the robot struggles.
The robot learned a pattern, but not necessarily what we wanted it to learn.
This is one of the tricky problems in Physical AI. A successful result doesn't always mean a model understands the task well enough to handle different situations.
That's why the quality and variety of training examples matter. Researchers need to test whether a robot can handle changes rather than simply repeat what worked before.
This is also why robotics data is such an important part of the work happening around @PrismaXai .
The real question isn't just whether a robot can succeed. It's whether it has learned something that still works when the conditions change.
𝐉𝐨𝐢𝐧 𝐭𝐡𝐞 𝐏𝐫𝐢𝐬𝐦𝐚𝐗 𝐣𝐨𝐮𝐫𝐧𝐞𝐲.
Discord: discord.gg/prismaxai
Website: prismax.ai
@vivianrobotics
@realAltcoiner
@MaxC16134

Domic ☂️ retweeted
the data looks correct. the numbers match the information makes sense and everything seems fine.
but there's one question people often forget to ask.
where did that data actually come from?
think about a DeFi application that uses real-world financial data to make a decision. even if the information looks accurate the application still needs a way to establish whether it came from a reliable source and whether it has been changed along the way.
just receiving data from an API doesn't automatically make it trustworthy.
this becomes more important when applications depend on external information to handle important decisions. a small issue with the source data can affect everything built on top of it.
and checking the final result isn't always enough. sometimes, you need a way to verify the information behind that result.
this is one of the problems PrimusLabs is working around making Web2 data verifiable for Web3 applications through technologies like zkTLS.
the interesting part is that applications don't necessarily need to expose all the underlying information to establish that certain data is valid.
imo, as more real-world data starts being used oonchainl knowing the source of information will matter just as much as the information itself.
because correct data is useful but knowing why you should trust it is a different thing.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs
something i find interesting about verification is that passing the check doesn't always mean you'll get approved.
imagine you verify your account, provide the required information and everything checks out. but the application still rejects your request.
what went wrong?
well verification and approval are two different things.
verification checks whether certain information meets the required conditions. approval depends on what the application does with that information.
for example a lending app might successfully verify someone's financial records but that doesn't automatically mean the person qualifies for a loan. the app could have other requirements around income repayment history or risk.
the same thing can happen with eligibility checks rewards programs and other Web3 applications.
this is why i think it's important to understand what a verification system actually proves.
a valid result doesn't automatically mean every condition has been met and it definitely doesn't guarantee that the final decision is correct.
this is where projects like PrimusLabs become interesting. verifiable data can help applications establish whether certain information is authentic but developers still need to build the right logic around it.
imo, the goal shouldn't be to make every decision automatic just because the data is verified.
it's about giving applications better information to make decisions while keeping the rules clear and handling cases that don't fit perfectly.
because sometimes the problem isn't the verification itself.
it's what happens after verification is complete.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs

𝐖𝐡𝐲 𝐒𝐡𝐨𝐮𝐥𝐝 𝐄𝐯𝐞𝐫𝐲 𝐕𝐚𝐥𝐢𝐝𝐚𝐭𝐨𝐫 𝐑𝐞𝐚𝐜𝐡 𝐭𝐡𝐞 𝐒𝐚𝐦𝐞 𝐓𝐫𝐚𝐝𝐢𝐧𝐠 𝐑𝐞𝐬𝐮𝐥𝐭?
Imagine you place an order to buy a token and the trade gets executed.
Now, think about what happens behind the scenes.
Different validators are checking and processing transactions across the network. But what if one validator calculates a different result from another?
One says the trade was successful while another comes up with a different balance.
That would create a serious problem.
Your account balance, trading position, and even liquidation status could become inconsistent. In a financial system you can't afford that kind of confusion.
This is why deterministic execution matters.
Every validator needs to follow the same rules process the same ordered transactions and reach the same final state. The same inputs should produce the same outputs.
It sounds simple but building a system that maintains this consistency while handling a large number of transactions is not an easy job.
This is one of the interesting things about TxFlow.
Its infrastructure is designed around consistent transaction ordering and verifiable execution, helping the network agree on how transactions change the state of the system.
For me this is an important part of onchain trading that people don't talk about enough.
Speed matters but speed alone isn't enough.
When money and trading positions are involved getting the correct result every time is just as important as getting it quickly.
@Harry_TxFlow @kaisrr3a @0x_rc @matthubuilds @Manuel_Neuer
𝐖𝐡𝐚𝐭 𝐈𝐟 𝐓𝐰𝐨 𝐓𝐫𝐚𝐝𝐞𝐫𝐬 𝐓𝐫𝐲 𝐭𝐨 𝐁𝐮𝐲 𝐭𝐡𝐞 𝐒𝐚𝐦𝐞 𝐋𝐢𝐪𝐮𝐢𝐝𝐢𝐭𝐲?
Imagine there is only one seller willing to sell 1 BTC at $100,000.
Now, two traders place buy orders at the same price.
Both want that BTC but there is only one available.
𝐒𝐨, 𝐰𝐡𝐨 𝐠𝐞𝐭𝐬 𝐢𝐭?
This is where the order matching system becomes important.
An exchange needs clear rules to decide which order gets filled first. Usually, if two orders have the same price the one that arrived first gets priority.
The first trader gets the available BTC while the second trader order has to wait for more sellers to enter the market or for the price to change.
This might sound like a small detail but imagine it happening thousands of times every second across different markets.
If the matching process isn't consistent traders could start questioning whether orders are being handled fairly.
That's one reason I'm interested in what TxFlow is building.
TxFlow focuses on onchain trading infrastructure, where order matching and settlement are designed to follow verifiable rules.
The interesting part isn't just how quickly a trade happens. It's whether we can understand why one order was filled before another.
Because in trading, execution matters just as much as the price you see on your screen.
@Harry_TxFlow @kaisrr3a @0x_rc @matthubuilds @Manuel_Neuer
GenLayer is global but I think the best way to grow any ecosystem is through local communities.
For me, one interesting thing about @GenLayer is how it approaches the problem of bringing AI reasoning into blockchain applications.
Traditional smart contracts work well when rules are clearly defined. But real-world situations aren't always that simple. Sometimes, a decision needs context web information and a way to evaluate different outcomes.
That's where GenLayer's Intelligent Contracts and Optimistic Democracy become interesting.
Instead of relying only on fixed rules, GenLayer is exploring how decentralized networks can handle decisions that involve AI reasoning.
I think this is worth exploring, especially as AI agents become more involved in online transactions and agreements.
If you're interested in AI, blockchain or building something beyond traditional smart contracts, GenLayer is an ecosystem worth checking out.
I'm curious to see how this technology develops and what developers build with it.
Explore GenLayer and join the community through my referral link: portal.genlayer.foundation/?…
I'd also like to see more people from our region explore what GenLayer is building. If you're interested in this space take a look and share your thoughts.

𝗴𝗚𝗲𝗻𝗟𝗮𝘆𝗲𝗿 | 𝗥𝗲𝗴𝗶𝘀𝘁𝗿𝗮𝘁𝗶𝗼𝗻 𝗖𝗵𝗲𝗰𝗸-𝗶𝗻 🟣
Just 2 days left for the GenLayer Registration Check-in mission.
If you're eligible and have already registered this is a good time to complete the next step and secure your points.
𝗛𝗲𝗿𝗲'𝘀 𝘄𝗵𝗮𝘁 𝘆𝗼𝘂 𝗻𝗲𝗲𝗱 𝘁𝗼 𝗱𝗼:
1. Download Your Card If you've registered and are eligible, download your official registration card from the GenLayer portal.
2. Share It on X Post your card with a caption explaining your participation and make sure to tag @GenLayer in your post.
3. Submit Your Post Once your post is live, submit the link through the mission page to receive points.
Rewards: 500-5,000 points, depending on the mission's criteria.
Haven't registered or aren't eligible yet? You may still be able to submit a post without registration and earn points depending on the mission requirements.
The deadline is getting closer so don't leave it until the last minute.
If you're participating in the GenLayer ecosystem, make sure you check your eligibility and complete the mission before it closes.
𝗠𝗶𝘀𝘀𝗶𝗼𝗻 𝗹𝗶𝗻𝗸:
portal.genlayer.foundation/m…
Two days left. Get your check-in done

𝗴𝗚𝗲𝗻𝗟𝗮𝘆𝗲𝗿 | 𝗥𝗲𝗴𝗶𝘀𝘁𝗿𝗮𝘁𝗶𝗼𝗻 𝗖𝗵𝗲𝗰𝗸-𝗶𝗻 🟣
Just 2 days left for the GenLayer Registration Check-in mission.
If you're eligible and have already registered this is a good time to complete the next step and secure your points.
𝗛𝗲𝗿𝗲'𝘀 𝘄𝗵𝗮𝘁 𝘆𝗼𝘂 𝗻𝗲𝗲𝗱 𝘁𝗼 𝗱𝗼:
1. Download Your Card If you've registered and are eligible, download your official registration card from the GenLayer portal.
2. Share It on X Post your card with a caption explaining your participation and make sure to tag @GenLayer in your post.
3. Submit Your Post Once your post is live, submit the link through the mission page to receive points.
Rewards: 500-5,000 points, depending on the mission's criteria.
Haven't registered or aren't eligible yet? You may still be able to submit a post without registration and earn points depending on the mission requirements.
The deadline is getting closer so don't leave it until the last minute.
If you're participating in the GenLayer ecosystem, make sure you check your eligibility and complete the mission before it closes.
𝗠𝗶𝘀𝘀𝗶𝗼𝗻 𝗹𝗶𝗻𝗸:
portal.genlayer.foundation/m…
Two days left. Get your check-in done

GEN Airdrop Registration is open.
You've been building GenLayer with us since the start. Now it's time to register.
Open until Monday, October 26.
airdrop.genlayer.com
Domic ☂️ retweeted
something i find interesting about verification is that passing the check doesn't always mean you'll get approved.
imagine you verify your account, provide the required information and everything checks out. but the application still rejects your request.
what went wrong?
well verification and approval are two different things.
verification checks whether certain information meets the required conditions. approval depends on what the application does with that information.
for example a lending app might successfully verify someone's financial records but that doesn't automatically mean the person qualifies for a loan. the app could have other requirements around income repayment history or risk.
the same thing can happen with eligibility checks rewards programs and other Web3 applications.
this is why i think it's important to understand what a verification system actually proves.
a valid result doesn't automatically mean every condition has been met and it definitely doesn't guarantee that the final decision is correct.
this is where projects like PrimusLabs become interesting. verifiable data can help applications establish whether certain information is authentic but developers still need to build the right logic around it.
imo, the goal shouldn't be to make every decision automatic just because the data is verified.
it's about giving applications better information to make decisions while keeping the rules clear and handling cases that don't fit perfectly.
because sometimes the problem isn't the verification itself.
it's what happens after verification is complete.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs
not every problem needs a cryptographic proof.
i think this is something worth remembering as more projects start adding verification to their applications.
if you're building a simple app where the data isn't sensitive and the risk is low adding an extra verification layer might not make much sense.
but the situation changes when real money financial records or important user information is involved.
for example a DeFi app checking whether someone meets a certain requirement has more at stake than an app simply displaying public information.
in that case being able to verify where the data came from and whether a claim is valid can make a real difference.
still adding proofs comes with trade-offs.
~> more computation can mean higher costs.
~> extra verification steps can increase latency.
~> developers have another layer to integrate test and maintain.
so the question isn't whether cryptographic proofs are useful. it's when they're worth the extra complexity.
this is where i find the work around PrimusLabs interesting. its zkTLS technology focuses on verifying data from supported web sources, which could help applications that need stronger guarantees about offchain information.
but no technology should be added just because it sounds advanced.
developers need to look at the actual risk what they're trying to verify and whether the benefits justify the cost.
imo, good infrastructure isn't about making every application more complicated.
it's about giving developers the right tools when the problem actually calls for them.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs

𝐖𝐡𝐚𝐭 𝐈𝐟 𝐓𝐰𝐨 𝐓𝐫𝐚𝐝𝐞𝐫𝐬 𝐓𝐫𝐲 𝐭𝐨 𝐁𝐮𝐲 𝐭𝐡𝐞 𝐒𝐚𝐦𝐞 𝐋𝐢𝐪𝐮𝐢𝐝𝐢𝐭𝐲?
Imagine there is only one seller willing to sell 1 BTC at $100,000.
Now, two traders place buy orders at the same price.
Both want that BTC but there is only one available.
𝐒𝐨, 𝐰𝐡𝐨 𝐠𝐞𝐭𝐬 𝐢𝐭?
This is where the order matching system becomes important.
An exchange needs clear rules to decide which order gets filled first. Usually, if two orders have the same price the one that arrived first gets priority.
The first trader gets the available BTC while the second trader order has to wait for more sellers to enter the market or for the price to change.
This might sound like a small detail but imagine it happening thousands of times every second across different markets.
If the matching process isn't consistent traders could start questioning whether orders are being handled fairly.
That's one reason I'm interested in what TxFlow is building.
TxFlow focuses on onchain trading infrastructure, where order matching and settlement are designed to follow verifiable rules.
The interesting part isn't just how quickly a trade happens. It's whether we can understand why one order was filled before another.
Because in trading, execution matters just as much as the price you see on your screen.
@Harry_TxFlow @kaisrr3a @0x_rc @matthubuilds @Manuel_Neuer
𝐖𝐡𝐚𝐭 𝐈𝐟 𝐓𝐰𝐨 𝐀𝐈 𝐌𝐨𝐝𝐞𝐥𝐬 𝐑𝐞𝐚𝐝 𝐭𝐡𝐞 𝐒𝐚𝐦𝐞 𝐀𝐠𝐫𝐞𝐞𝐦𝐞𝐧𝐭 𝐃𝐢𝐟𝐟𝐞𝐫𝐞𝐧𝐭𝐥𝐲?
Imagine two AI agents making a deal.
Both agree on the terms the payment is locked in, and everything seems fine. But when it comes to checking whether the agreement was actually fulfilled things get complicated.
One AI looks at the evidence and says the conditions were met.
The other reads the same agreement and comes to a different conclusion.
Now what?
On a traditional blockchain, predefined rules can handle many situations perfectly. But interpreting a natural-language agreement or judging real-world evidence isn't always that simple.
You can't just assume every AI will understand things in exactly the same way.
This is one of the interesting problems GenLayer is trying to solve.
Through Intelligent Contracts and its Optimistic Democracy mechanism, GenLayer allows validators to independently evaluate outcomes and reach consensus, rather than simply trusting one AI model's answer.
The idea isn't that every model must think alike. It's about finding a way for a decentralized network to agree on a decision even when the underlying task involves AI reasoning.
Of course, that doesn't mean the majority will always be right. The quality of evidence how outcomes are evaluated and the ability to challenge a decision still matter.
But as AI agents start handling more transactions and agreements this problem becomes harder to ignore.
Getting two AI agents to make a deal might be the easy part.
𝐅𝐢𝐠𝐮𝐫𝐢𝐧𝐠 𝐨𝐮𝐭 𝐰𝐡𝐚𝐭 𝐡𝐚𝐩𝐩𝐞𝐧𝐬 𝐰𝐡𝐞𝐧 𝐭𝐡𝐞𝐲 𝐝𝐢𝐬𝐚𝐠𝐫𝐞𝐞 𝐜𝐨𝐮𝐥𝐝 𝐛𝐞 𝐭𝐡𝐞 𝐫𝐞𝐚𝐥 𝐜𝐡𝐚𝐥𝐥𝐞𝐧𝐠𝐞.
🤝 Paid partnership
Domic ☂️ retweeted
not every problem needs a cryptographic proof.
i think this is something worth remembering as more projects start adding verification to their applications.
if you're building a simple app where the data isn't sensitive and the risk is low adding an extra verification layer might not make much sense.
but the situation changes when real money financial records or important user information is involved.
for example a DeFi app checking whether someone meets a certain requirement has more at stake than an app simply displaying public information.
in that case being able to verify where the data came from and whether a claim is valid can make a real difference.
still adding proofs comes with trade-offs.
~> more computation can mean higher costs.
~> extra verification steps can increase latency.
~> developers have another layer to integrate test and maintain.
so the question isn't whether cryptographic proofs are useful. it's when they're worth the extra complexity.
this is where i find the work around PrimusLabs interesting. its zkTLS technology focuses on verifying data from supported web sources, which could help applications that need stronger guarantees about offchain information.
but no technology should be added just because it sounds advanced.
developers need to look at the actual risk what they're trying to verify and whether the benefits justify the cost.
imo, good infrastructure isn't about making every application more complicated.
it's about giving developers the right tools when the problem actually calls for them.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs
one thing people don't talk about enough when it comes to data verification is the cost.
verifying data sounds useful but what happens when an application needs to do it thousands of times every day?
someone has to pay for the proof generation infrastructure and verification process.
and this creates an interesting question.
who should actually cover that cost?
~> if users pay for every verification, it could make the experience expensive and frustrating.
~> if the application pays, it needs to make sure the cost makes sense for its business model.
~> if the protocol or infrastructure subsidizes everything, that model needs to be sustainable in the long run.
there isn't one answer that works for every product.
for example a DeFi application might be comfortable paying for verification when it helps prevent expensive mistakes. but for a product giving users small rewards even a little extra cost on every request could become a problem at scale.
this is where i think infrastructure design matters just as much as the technology itself.
PrimusLabs is working on verifiable data infrastructure, but for developers, the real question isn't only whether a proof can be generated.
it's whether they can use it reliably at a cost that makes sense for their application.
cheaper verification could make more use cases practical, but cost isn't the only factor. speed, security and reliability matter too.
imo the technology becomes much more useful when developers don't have to think twice before verifying something important because of the cost.
the real challenge isn't just making verification possible. it making it practical enough to use every day.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs

Domic ☂️ retweeted
one thing people don't talk about enough when it comes to data verification is the cost.
verifying data sounds useful but what happens when an application needs to do it thousands of times every day?
someone has to pay for the proof generation infrastructure and verification process.
and this creates an interesting question.
who should actually cover that cost?
~> if users pay for every verification, it could make the experience expensive and frustrating.
~> if the application pays, it needs to make sure the cost makes sense for its business model.
~> if the protocol or infrastructure subsidizes everything, that model needs to be sustainable in the long run.
there isn't one answer that works for every product.
for example a DeFi application might be comfortable paying for verification when it helps prevent expensive mistakes. but for a product giving users small rewards even a little extra cost on every request could become a problem at scale.
this is where i think infrastructure design matters just as much as the technology itself.
PrimusLabs is working on verifiable data infrastructure, but for developers, the real question isn't only whether a proof can be generated.
it's whether they can use it reliably at a cost that makes sense for their application.
cheaper verification could make more use cases practical, but cost isn't the only factor. speed, security and reliability matter too.
imo the technology becomes much more useful when developers don't have to think twice before verifying something important because of the cost.
the real challenge isn't just making verification possible. it making it practical enough to use every day.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs
AI can be more useful when it has access to better data but there's one problem.
a lot of the most valuable data is also the most sensitive.
think about financial records, medical information or private business data. this information could help AI systems produce better insights but most people and companies aren't comfortable sharing everything with an external system.
so the question is, can we use this data without making it public?
i think this is where privacy-preserving computation becomes interesting.
instead of always exposing the underlying information technologies like fully homomorphic encryption (FHE) allow computations to happen directly on encrypted data.
the idea is pretty simple: get useful results from data without needing to reveal the raw information during computation.
for example, a financial application could potentially analyze sensitive financial inputs without exposing them in plaintext to the party performing the computation.
there are still practical challenges especially around performance implementation and how results are verified. encryption alone doesn't guarantee that every AI output is correct or trustworthy.
but the direction makes sense to me.
we shouldn't have to choose between using valuable data and protecting the people or businesses it belongs to.
this is also why i'm interested in what primuslabs is exploring around FHE and confidential infrastructure.
as AI becomes more connected to finance and onchain applications, keeping sensitive information private while still making it useful could become increasingly important.
the real opportunity isn't just giving AI more data.
it's finding better ways to use data that people shouldn't have to expose in the first place.
Join :- s.kaito.ai/F3BKkky
@primus_labs #PrimusLabs

𝐖𝐡𝐚𝐭 𝐈𝐟 𝐚 𝐑𝐨𝐛𝐨𝐭 𝐒𝐮𝐜𝐜𝐞𝐞𝐝𝐬 𝐟𝐨𝐫 𝐭𝐡𝐞 𝐖𝐫𝐨𝐧𝐠 𝐑𝐞𝐚𝐬𝐨𝐧?
Imagine a robot trained to pick up a red cup from a table.
During testing, it gets the job right every single time. Looks like the model has learned the task right?
But there a catch.
What if it isn't actually recognizing the cup? Maybe it has learned to reach for a particular spot on the table because the cup was always placed there during training.
Move the cup somewhere else and suddenly the robot struggles.
The robot learned a pattern, but not necessarily what we wanted it to learn.
This is one of the tricky problems in Physical AI. A successful result doesn't always mean a model understands the task well enough to handle different situations.
That's why the quality and variety of training examples matter. Researchers need to test whether a robot can handle changes rather than simply repeat what worked before.
This is also why robotics data is such an important part of the work happening around @PrismaXai .
The real question isn't just whether a robot can succeed. It's whether it has learned something that still works when the conditions change.
𝐉𝐨𝐢𝐧 𝐭𝐡𝐞 𝐏𝐫𝐢𝐬𝐦𝐚𝐗 𝐣𝐨𝐮𝐫𝐧𝐞𝐲.
Discord: discord.gg/prismaxai
Website: prismax.ai
@vivianrobotics
@realAltcoiner
@MaxC16134
🤝 Paid partnership
𝐖𝐡𝐲 𝐑𝐨𝐛𝐨𝐭𝐢𝐜𝐬 𝐓𝐞𝐚𝐦𝐬 𝐂𝐚𝐧'𝐭 𝐉𝐮𝐬𝐭 𝐑𝐞𝐜𝐨𝐫𝐝 𝐄𝐯𝐞𝐫𝐲𝐭𝐡𝐢𝐧𝐠
More data sounds like a good thing, right?
But in robotics, recording everything without a clear purpose can create its own problems.
Imagine a team collecting thousands of robot demonstrations, only to realize that most of them don't match the task they're trying to solve.
Now they've spent time, money, and resources collecting data that may not be very useful for their model.
The challenge isn't simply gathering more recordings. It's deciding what to record, which situations matter, and what the team actually needs to learn.
A robot learning to handle objects in a busy environment may need very different examples from one performing a simple task in a controlled setting.
That's why data collection needs a plan.
This is also where @PrismaXai approach to robotics data is interesting. The focus isn't just on having data available, but on helping teams access data relevant to their needs and arrange custom collection when required.
Because collecting more data isn't always the answer.
Collecting the right data can make a much bigger difference.
𝐉𝐨𝐢𝐧 𝐭𝐡𝐞 𝐏𝐫𝐢𝐬𝐦𝐚𝐗 𝐣𝐨𝐮𝐫𝐧𝐞𝐲.
Discord: discord.gg/prismaxai
Website: prismax.ai
@vivianrobotics
@realAltcoiner
@MaxC16134
