

AI as a Service // For the 99%
Joined June 2026
- Tweets475
- Following19
- Followers55
- Likes463



$0.23 vs $5.00 per 1M input tokens.
That is the gap between GPT-OSS 120B and Kimi K3 on GoodEnough's current model price list.
The visible part of AI cost is easy to compare:
→ Input price
→ Output price
→ Model name
→ Context window
→ A neat price-per-million number
Useful numbers, yes.
But they are only the tip of the iceberg.
The real cost of AI sits underneath:
→ How much of your traffic needs the flagship model
→ Whether your requests are mostly input or output tokens
→ How often the model needs another try
→ Whether a cheaper model clears the task
→ Tool calls and long context
→ Latency and throughput
→ Routing rules
→ Evaluation
→ Human review
→ Failed outputs that still cost money
This is why "cheapest model" is not the same as "cheapest useful answer."
A model that costs 5x more may be worth it for one task.
It may be wasteful for the other 99.
The practical question is not:
"What is the lowest token price?"
It is:
"What is the lowest-cost model that clears this task reliably?"
Run 100 real prompts.
Measure the model mix, the retries, and the useful outputs.
Then check the invoice.
Let the numbers decide where the flagship belongs.
Good AI. Small bill. But only if you measure the work, not just the price tag.

AI model costs, the practical roadmap (save this)
Start here:
01. Measure the work
├── 100 real prompts
├── Input/output token mix
├── Quality threshold
└── Latency and failure cases
02. Stop defaulting to the flagship
├── Easy chat → GPT-OSS 120B
├── Code → Qwen3 Coder Next
├── Images → Qwen3 VL
└── Hard cases → test the expensive model
03. Know the price gap
├── GPT-OSS: $0.23 input / $0.92 output
├── Qwen3 Coder Next: $0.77 / $1.85
├── Qwen3 VL: $0.82 / $4.09
└── Kimi K3: $5.00 / $25.00
04. Route instead of guessing
├── Choose a model directly
├── Let Auto route each request
├── Inspect which model was selected
└── Compare useful output, not benchmark headlines
05. Put the cheap path into production
├── OpenAI-compatible API
├── Function calling
├── Streaming
└── Spend limits and error handling
06. Run the invoice test
├── Take last month's real traffic
├── Rerun the prompts
├── Measure quality by task
└── Keep the model that earns its place
Good AI. Small bill.
The point is not that the cheapest model wins every task.
The point is that the most expensive model should have to prove it belongs in the mix.
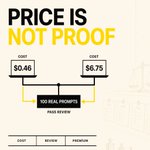
GoodEnough Auto is listed at $0.23 per 1M input tokens and $0.92 per 1M output tokens. In the homepage's example, that works out to $0.46 versus a $6.75 frontier reference for 1M input + 250K output tokens.
Run your own prompts. Let the numbers decide.

A million input tokens plus 250,000 output tokens: $6.75 on a frontier reference, or $0.46 on GoodEnough Auto.
That is a stated 93% difference.
It is also an illustration, not your savings.
The missing details are the ones that decide whether the comparison survives contact with your workload:
- What is your input/output mix?
- Which tasks actually need the flagship model?
- What does "good enough" mean for each task?
- Are you paying for retries, long context, or structured output?
The calculator makes the contrast even louder: a $2,000 monthly bill becomes an estimated $134.62 under its example assumptions.
Useful benchmark. Dangerous invoice forecast.
Before claiming savings, ask for the invoice and the workload:
1. Export the last month's token and model mix.
2. Sample 100 real requests.
3. Rerun them on Auto and on the cheapest explicit model that might work.
4. Score correctness, tool use, latency, and output format.
5. Compare the result at your actual input/output ratio.
GoodEnough says lower token prices do not prove a model is right for a task. That is the part worth keeping.
Let the numbers decide which requests deserve the flagship, and which ones never did.

$6.75 became $0.46.
That's the illustrative cost difference between 1M input tokens plus 250K output tokens at a frontier reference price and GoodEnough Auto.
93% less.
The important part isn't the headline discount. It's that you don't have to send every request to the most expensive model.
Auto routes each request to a model, and shows you which one it selected.
Cheap is not the same as good. Run your real prompts. Check the output. Check the latency. Keep the model that clears the task. Then look at the invoice again.
The practical test: take 100 production prompts, compare the cheapest model that works against your current default, and measure cost per useful answer. Let the numbers decide whether your flagship default has earned its place.

A $6.75 frontier-model task can cost $0.46 on GoodEnough Auto.
That's a 93% estimated difference for the same illustrative workload: 1 million input tokens plus 250,000 output tokens.
The instinct is to send every request to the flagship model. That's usually where the invoice goes wrong.
Auto routes each request to a model, and you can see which model was selected and what it cost. You can also choose a model directly when the task actually earns the premium.
The point isn't that the cheapest model wins every task. Lower token prices don't prove a model is right.
Test it on your real work. Pull your last 100 requests and ask one question:
Which traffic is still paying the flagship premium, and why?
Keep the model that clears the task. Stop paying for a reputation your workload doesn't need.

Function calling is not a frontier-only feature.
Take the tool workflow you already run:
- same OpenAI client
- same tools payload
- same tool_choice=auto
- same stream=true
- same eval set
Point it at GoodEnough's OpenAI-compatible API and run it on the production text models.
The docs support standard OpenAI function calling, streaming, tools, and tool_choice=auto.
Then measure the thing that matters: did the model choose the right tool and produce usable arguments?
Not whether it won a benchmark.
The price gap is real: GPT-OSS 120B is listed at $0.23 per 1M input tokens and $0.92 per 1M output. Kimi K3 is $5 and $25.
Run your actual workflow before paying the frontier premium by default.
Here's a challenge to anybody using AI today: send us your monthly invoice from the frontier and we'll show you how much we'll save you. We'll even give you free credits to show you how Good Enough is more than enough!
The same AI workload can cost $6.75 or $0.46.
That's the illustrative gap between a frontier reference and GoodEnough Auto for 1M input tokens plus 250k output tokens, a stated 93% difference.
The uncomfortable part:
Most teams don't know which of their tasks actually need the expensive model.
They default to the flagship because the cost of a wrong answer feels higher than the cost of every answer.
That logic is backwards when most work is routine.
The right question isn't "Which model scores highest?"
It's:
"What is the cheapest model that clears this task reliably?"
Run 100 real prompts. Keep the task mix honest. Compare the output, latency, and invoice.
Let the expensive model earn its place.
Not every prompt needs a flagship. But you should measure before you downgrade, and measure before you keep paying the premium.

$0.23 per million input tokens.
Before rewriting your AI integration, run the cheaper experiment:
Keep your OpenAI client.
Point it at GoodEnough's base URL.
Select a model.
Send the exact same request.
Then compare the things that matter:
- output quality
- latency
- failures
- tool calls
- token cost
GoodEnough lists GPT-OSS at $0.23 per 1M input tokens and $0.92 per 1M output tokens.
Kimi K3 is listed at $5 and $25.
That is not a reason to switch blindly.
It is a reason to run 100 real prompts before rebuilding your application.
If the output holds, you may have a cost problem, not a migration problem.
$0.46 for 1 million input tokens plus 250,000 output tokens.
That is the illustrative GoodEnough Auto cost on its homepage, versus a stated $6.75 frontier reference.
The interesting project is not "try a cheaper model."
It is to build a small production system that can prove when cheaper is good enough:
1. Pick 100 real prompts from your work.
2. Run them through a fixed model and record quality, latency, failures, and cost.
3. Run the same prompts through Auto. It routes each request to a model, and the response includes which model was selected.
4. Inspect the mix. Are easy requests going to a cheaper model while code and image requests go elsewhere?
5. Keep a small set of prompts where the expensive model clearly wins. Don't average those away.
6. Put the API behind your actual application. GoodEnough supports OpenAI-compatible chat completions, so an existing client can be pointed at its base URL.
7. Add the boring production pieces: API-key authentication, streaming, rate limits, retries, error handling, and spend alerts.
8. If your app uses tools, test those too. Standard OpenAI function calling works on the production text models, including streaming.
9. Compare the invoice, not the benchmark.
10. Set a rule for promotion: a request earns the expensive model only when the cheaper route fails your evaluation.
The point is not that the cheapest model always wins.
It won't.
The point is that "use the flagship by default" is not a strategy. It is an untested assumption.
Rerun the 100 prompts after every model or routing change.
Let the quality-cost mix decide.

$6.75 in frontier-model cost.
$0.46 with GoodEnough Auto.
Same illustrative workload: 1M input tokens and 250K output tokens.
That is a stated 93% cost difference.
But the cheap number is not the point.
The point is whether the output clears your real task.
A lower token price does not prove a model is right for your work. GoodEnough's own advice is to test on your prompts, inspect the result, and keep the model that meets the need.
So don't ask, "What is the smartest model?"
Ask:
What did this task cost?
Did the answer pass review?
Would I pay the premium again?
Run 100 real prompts. Compare the output and the invoice.
Then let the numbers decide whether your default model has earned its price.

Switching AI providers should not start with a rewrite.
Start with the client you already have.
Point your existing OpenAI client at GoodEnough's base URL.
Select a model.
Run 100 real production prompts.
Measure:
- output quality
- latency
- failures
- input and output tokens
- cost
Only then decide whether the integration deserves changing.
GoodEnough's API is OpenAI-compatible for chat completions, and it supports direct model selection or Auto routing.
The important part is not the promise of a lower token price. It is testing your own work.
A provider switch should be a benchmark first and a rewrite second.
$6.75 in frontier-model cost.
$0.46 with GoodEnough Auto.
Same illustrative workload: 1M input tokens and 250K output tokens.
That is a stated 93% cost difference.
But the cheap number is not the point.
The point is whether the output clears your real task.
A lower token price does not prove a model is right for your work. GoodEnough's own advice is to test on your prompts, inspect the result, and keep the model that meets the need.
So don't ask, "What is the smartest model?"
Ask:
What did this task cost?
Did the answer pass review?
Would I pay the premium again?
Run 100 real prompts. Compare the output and the invoice.
Then let the numbers decide whether your default model has earned its price.

Stop routing every prompt to the flagship.
Let Auto choose:
• GPT-OSS for general chat
• Qwen3 Coder Next for code
• Qwen3 VL for images
Then inspect the `model` field in every response.
That field is your workload audit.
Run 100 real prompts. Count the model mix. Rerun evals by task. Compare output quality and cost.
If most requests do not need the flagship, paying for it by default is not a strategy. It is a tax.
GoodEnough Auto returns the selected model, so you can measure the routing instead of trusting the label.
One model for every request is an expensive habit.
Let Auto route the work:
general chat -> GPT-OSS
code -> Qwen3 Coder Next
images -> Qwen3 VL
GoodEnough's router uses a learned classifier plus deterministic filters. The response includes the `model` field, so you can inspect what actually handled each request.
Run 100 real prompts:
1. Log the model field.
2. Group requests by task.
3. Compare quality and spend.
Auto is listed at $0.23 per 1M input tokens and $0.92 per 1M output tokens.
Stop debating which model wins.
Measure which model your requests actually need.
Coming soon to Good Enough AI! 85% off your AI search bill.
api-docs.deepseek.com/guides…

Everyone is looking at model routing like it is five model choices.
The more interesting part is that it can become one shared decision system.
With an OpenAI-compatible API, your application can send requests to one endpoint. Auto then selects a model for each request and returns which model it chose.
A coding task can go to Qwen3 Coder Next. An image request can go to Qwen3 VL. General chat can go to GPT-OSS.
That turns one API key into a model fleet.
The upside is obvious:
- fewer provider integrations
- fewer model-selection branches in application code
- the option to use function calling and tools through the same interface
- a cost decision made per request instead of per product
The blast radius is just as real:
- your bearer token can reach every model your account exposes
- a routing rule becomes a production dependency, even when it looks like a pricing setting
- tool calls need the same approval boundaries whether the request landed on a cheap model or an expensive one
- rate limits and account credit are separate constraints, so "the API is up" does not mean "the workload can continue"
- if you do not record the selected model and token cost, you cannot explain the invoice or the output mix
The breakthrough is not that you can call several models.
It is that they can look like one provider inside your real application.
That changes the job from choosing a flagship once to designing routing, permissions, fallbacks and measurement.
Do not compare models on a leaderboard and stop there.
Run 100 real prompts through the route you plan to ship. Check which model handled them, what the outputs cost, and where a human approval still belongs.

A $2,000 AI bill can become an estimated $134.62.
GoodEnough's calculator gets there using a 75% input / 25% output mix.
That is a 93.3% difference.
But don't trust the calculator. Trust your workload.
Take 100 production-like prompts:
- support replies
- code changes
- extraction
- long-document questions
- image requests
Run them through Auto. It routes each request to a model, and the response shows which model it selected.
Then compare:
1. Did the answer pass your eval?
2. How many tokens did you use?
3. What would the bill have been at your current rates?
GoodEnough Auto is listed at $0.23 per 1M input tokens and $0.92 per 1M output tokens.
The point isn't that cheaper is always better. GoodEnough explicitly says to test your own work and keep the model that earns its place.
The point is that "we need the flagship" is a claim your 100 prompts can disprove.
Your bill is probably hiding a routing problem.