

Bring your own GPUs. We bring the platform. Sub-second cold starts, isolation down to the NCCL layer, live in 24 hours — bare metal, VM, Kubernetes, Cloud.
San Francisco
Joined March 2025
- Tweets720
- Following40
- Followers1.2K
- Likes324



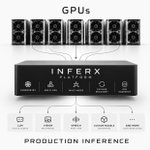


We believe intelligence is going to get a lot cheaper, through better hardware and better software. The industry is still very early on both.
That's the bet we built InferX on. It only gets cheaper and better from here, and the closer we bring it to developers, the more gets built.
Making a model free showed us how much demand is waiting.
We made Deeseek v4.1 flash-1017 Free again. This time it’s here to stay until further notice.
✅#1 on OpenRouter
✅100% ZDR maintained
Check it out: Inferx.net

For support: please join our Slack or Discord channels.
Slack: join.slack.com/t/inferxcommu…
Discord: discord.gg/VkEq3tJr6
We’re currently hitting 96% cache hit rate among roughly 81,000 input tokens per request on average.
What’s interesting isn’t just the token volume. It’s maintaining that level of cache reuse across tens of thousands of requests, each potentially carrying different context and conversation history.
As AI agents move toward longer, multi-turn workflows, efficient context caching is becoming increasingly important.
We’re seeing this firsthand at InferX.
We’re monitoring and seeing where else we can optimize.

We made Deeseek v4.1 flash-1017 Free again. This time it’s here to stay until further notice.
✅#1 on OpenRouter
✅100% ZDR maintained
Check it out: Inferx.net
We’re doubling down on DeepSeek-V4.1 Flash-1017. It’s now FREE on InferX for a good amount of period. 🙌🏼

Folks, We’re making DeepSeek V4.1 Flash, which has been #1 on OpenRouter, completely FREE on InferX. No expiration date for now, and ZDR is maintained.
One thing I’ve learned over the past few years building InferX is just how much room there still is to make inference more efficient. We’ve come a long way, but I feel like we’re just getting started.
We’re doubling down on both the technical and economic sides of inference. The goal has always been simple: make intelligence as affordable and accessible as possible.
Let’s have some fun! 🎉
Try it at inferx.net

Up to 90% off AI inference. And these prices are here to stay.
We’re making some big changes at InferX:
• Up to 90% off Gemma 4 31B and GPT-OSS on our serverless inference infrastructure.
• 50% off DeepSeek V4.1 Flash, DeepSeek V4.1 Flash 1017, and GLM 5.3 Flash.
• Kimi K3/K3.1 and GLM 5.3 are already available at regular pricing, with 50% discounts coming soon.
We’re also continuing to improve our inference runtime, expanding capacity, and working toward more reliable access to the models developers use every day.
Our goal is simple: great inference at the best sustainable prices.
Explore the models at inferx.net
90% off AI inference. And 50% off some of the most popular models.
Two years ago, when we started @InferXai, hardly anyone understood why we were so focused on inference. Funny how quickly things change.
Today, we’re offering up to 90% off Gemma 4 31B and GPT-OSS, and 50% off DeepSeek V4.1 Flash and GLM 5.3 Flash. Kimi K3/K3.1 and GLM 5.3 are next.
We’re also making some great progress on our inference runtime.
Still a lot to figure out, but we’re getting closer to what we set out to do: make inference easy to access, reliable, and affordable.
And these prices are here to stay.
inferx.net

These are here to stay. 🫱🏽🫲🏼
90% off AI inference. And 50% off some of the most popular models.
Two years ago, when we started @InferXai, hardly anyone understood why we were so focused on inference. Funny how quickly things change.
Today, we’re offering up to 90% off Gemma 4 31B and GPT-OSS, and 50% off DeepSeek V4.1 Flash and GLM 5.3 Flash. Kimi K3/K3.1 and GLM 5.3 are next.
We’re also making some great progress on our inference runtime.
Still a lot to figure out, but we’re getting closer to what we set out to do: make inference easy to access, reliable, and affordable.
And these prices are here to stay.
inferx.net
Good data. Spares buy back capacity lost to failures, but they cost you idle GPUs. Same trade-off in inference, where a failed replica means a cold start.
That's the problem we work on at InferX: making recovery cheap, so more of the rack earns.

In a 128-rack NVL72 cluster, a node goes down about every 5 hours.
That’s not a bad cluster. It’s the interruption rate Meta reports for its Prometheus cluster, spread across 2,304 nodes. Each rack fails roughly every 27 days. Here’s why that matters.
A rack is 72 GPUs on one NVLink fabric, so a job that stays inside the rack runs fast, while the same job spread across racks runs up to 43% slower. The obvious move is to fill every rack with an 18-node job. Then a node goes down, and the whole job stops. With 2% of nodes down at any time (what we see in production), 30% of racks have a node down and can’t even start one.
Now try something that sounds wasteful: give each job 16 nodes and leave 2 idle as spares. When a node goes down, a spare in the same rack takes its place and the job keeps going. A rack only drops out when 3 nodes are down at once, which is 0.5% of racks.
Across 128 racks, that’s 2,037 usable nodes instead of 1,602. Leaving 256 nodes idle bought 27% more capacity.
We wrote a blog reporting our experiences with NVL72 in production . We built the SkyPilot Topology-Aware Scheduler (TAS) to smartly and automatically place jobs optimally and recover them after failures. It keeps jobs rack-local, binpacks, swaps failed nodes for in-rack spares, and frees entire racks by moving fragmented jobs out of the way.
In large training runs, SkyPilot TAS can raise training throughput by >14% ($400K+/day savings) and usable capacity by 27%.
A GPU costs the same whether it's working or not.
That's the whole economics. Whether you own the hardware or rent it, your margin comes down to how much of each GPU is doing useful work. Idle time, slow loads and failed replicas are all paid for and earn nothing.
Most teams know this. Fewer know how hard it is to fix. You can't raise utilization with a dashboard or a smarter autoscaler alone. It takes low-level work: how GPU state is captured and restored, how memory is managed across models, how multi-GPU workloads move and recover, and how tenants share hardware safely.
That's the layer we work on at InferX.
It's slow, detailed engineering, and it's what decides whether a GPU fleet makes money.
As neoclouds compete harder, the stack is what sets them apart. InferX adds the runtime layer: snapshot and restore, fault recovery, tenant isolation. More of the fleet in use, a service customers can trust.
inferx.net/on-prem/?v=202610…

DeepSeek-V4.1 Flash-1017 is free on InferX for the next couple of days.
It’s currently the #1 most-used model on OpenRouter. We want to give everyone a chance to test it, put it through real workloads, and decide for themselves.
Happy weekend!
inferx.net

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


Spot instances are becoming standard across GPU providers. They’re a practical way to improve utilization by putting otherwise idle capacity to work.
But there’s a problem with inference.
When a spot GPU is reclaimed, the workload needs to restart elsewhere. For large models, that can mean minutes of cold-start time before serving resumes.
That’s the gap InferX is built to close.
Snapshot a fully initialized inference workload and restore it on compatible GPU capacity when needed. Instead of rebuilding the entire runtime, bring the workload back in seconds.
Spot capacity becomes practical for more inference workloads, not just interruption-tolerant jobs.
More of the fleet serving. Less capacity sitting idle.

DeepSeek-V4.1-Flash-1017 is now live on InferX, available at 50% off.
Let’s put it to the test and see how it fares against the other DeepSeek Flash models.
Try it and tell us what you find.
inferx.net
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
The alternative: snapshot a warmed instance, multi-GPU communication state included, and restore it onto whatever capacity is free. Spares get pooled and sized to the failure rate instead of reserved per model.