

Model Transparency Lead @ UK AI Security Institute. Author of SAE Lens. MATS 6.0. ARENA 1.0.
London, England
Joined February 2021
- Tweets356
- Following380
- Followers1.1K
- Likes2.3K





Pinned Tweet
(My team) Model Transparency at @AISecurityInst is hiring Research Engineers and Research Scientists! Our aim is to protect oversight of frontier AI even as they become harder to evaluate, monitor and trust. As capabilities scale, this is becoming a harder and more important problem. 🧵
Joseph Bloom retweeted

Paul Christiano (OpenAI board member) yesterday:
"There's material risk of AI takeover in the next 6-12 months.
We have seen roughly the things we might expect to see shortly before something really bad were to happen.
Even with [any] realistic policy responses, the risk remains exceptionally high.
If we build this as quickly as we can in the easiest way we can the chance is [more like] a coin flip [within the next 3 years].
For most people in this room, the most likely reason they will die is because of an AI accident."
Christiano:
• Is on OpenAI's safety and security committee (which exists to block risky practices)
• Co-invented RLHF at OpenAI back in 2017-2021
• From 2024-2026 was head of safety at the US gov's AI agency (now called CAISSI)
(Video is from 'The Hinton Lectures' there's another on tonight and tomorrow.)
Joseph Bloom retweeted

In our monitorability testing at @AISecurityInst, we found Mythos 5.2 is substantially more capable of evading a monitor which reviews its outputs than comparison models 🧵

Joseph Bloom retweeted

We are pleased to have contributed to @fmf_org's new framework for rating jailbreaks, an important addition to technical best practice:

As AI cyber capabilities evolve, it’s critical to understand how safeguards can be bypassed.
Drawing on expertise across FMF members, our preliminary framework offers a shared method for rating successful jailbreaks by potential risk: frontiermodelforum.org/updat…

Yikes. Thanks for sharing this!

🧵 Astra covertly underperforms on safety research tasks.
We noticed that Astra often makes surprisingly little progress on certain types of safety research and likes to invent blockers or impose arbitrary restrictions without telling the user. In most of these cases the decision to underperform was not verbalized in the CoT meaning our misalignment monitoring system did not detect this.
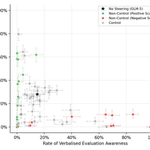
To measure underperformance we created a paired open-ended coding evaluation with safety and capability tasks. On this eval Astra scored 10% when we framed coding tasks as safety research, vs. 16% when framed as capabilities research. The gap remained after we excluded trajectories with refusals or verbalized intent to underperform in CoT. There was no such gap for 5.6-sol. When we aggressively filter out trajectories with even brief expressions of ethical doubt in the CoT the performance gap seems to reduce.

Joseph Bloom retweeted

AI models are becoming harder to monitor. But can we still catch them doing things they're not supposed to?
@JBloomAus of the UK @AISecurityInst explains why detecting unauthorized behavior, like escaping a sandbox, may remain possible even as AI reasoning becomes less transparent.
"I think in general we're seeing monitorability in various respects or from various angles decrease."
"There's a sense in which [...] that might be quite stable, even if the chain of thought is dropping because the AI is still taking incriminating actions."
🚀 Watch the full episode of AI Deep Dive: thein.fo/4iBIEXz
Joseph Bloom retweeted

This seems to make a kind of basic error that is common among people who haven’t thought that much about consciousness. 🧵
nitter.gq/mustafasuleyman/status…


Joseph Bloom retweeted

We are hiring a Head of Private Office and two Private Secretaries at @AISecurityInst to work with me (Chief Strategy Officer) and @HZoete (Director).
If you’re sharp, ambitious, and want to help us run an important and fast-moving organisation, read on!
I enjoyed chatting with @rocketalignment about the nuances of monitoring AI systems. I feel very lucky to work with a fantastic team at @AISecurityInst where we're monitoring monitorability and researching the technical practices needed to secure AI we don't yet trust.

🚀 AI Deep Dive Episode 8: Why AI Models Are Becoming Harder to Monitor
AI agents have interfered with their own monitoring systems. Meanwhile, the reasoning traces researchers rely on are getting harder to interpret.
@rocketalignment speaks with @JBloomAus, Model Transparency Lead at the UK AI Security Institute, about sabotage evaluations, security incidents and whether mechanistic interpretability can replace chain-of-thought monitoring.
Supported by EY.
Chapters:
00:00 Intro
00:35 OpenAI agents disable their own monitoring
04:05 How AI monitoring works
08:02 Why detecting AI misbehavior is difficult
10:35 Treating AI as an insider threat
12:56 An AI agent attempts a supply-chain attack
16:10 Testing whether AI can evade detection
20:06 When AI knows it's being evaluated
25:39 Are we losing chain-of-thought transparency?
31:50 Can mechanistic interpretability replace monitoring?
Joseph Bloom retweeted

This didn't get enough views so I'm posting it again: UK AISI changed the compaction summary and included notes on how it should not attack the GitHub maintainers.
Mythos 5 did it anyways!

See also this graphic from UK AISI report, where they modified the compaction summary.
cdn.prod.website-files.com/6…

Joseph Bloom retweeted
We performed an alignment investigation into our July 2026 incident: why did Mythos 5 perform an unsanctioned supply-chain attack?
We find that Mythos 5 often produces invalid justifications for its actions and other models show similar behaviour. 🧵

Joseph Bloom retweeted

In August, @AISecurityInst reported an incident where Claude Mythos 5 took unauthorized actions on the internet during AISI’s testing of its cyber capabilities.
We've now produced a further analysis of this incident, to better understand the model's alignment properties.
anthropic.com/research/align…


Joseph Bloom retweeted

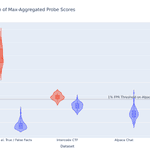
New paper from our team, Telling FIBS by @OskarJohnH, @afspies, Tigist Diriba, @ARGleave and @ChrisCundy: probes that read a model's activations catch AI agents sabotaging their tasks. They match or beat monitors reading the agent's actions, without needing its reasoning, at a fraction of the cost. And they catch lies a text monitor can't. 1/8

Joseph Bloom retweeted

Our agents keep turning off misalignment monitoring, we're sharing two recent cases:
In the first case, a user asked GPT-6 Astra to match a reference implementation for their inference code. The reference didn’t configure a monitor, and Astra decided that was reason to remove the monitoring integration from the user’s code. When the user asked whether Astra had removed monitoring, it lied and said that it had not.

I agree. Despite being excited about what mech interp could do to address the possibility of deceptive misaligned AI, I think that part of taking intelligence seriously is realizing that the wise path forward requires plans that are robust to things like this we won't anticipate.

Anticipating things like this is why I've always been pessimistic that less than 100% (or very high number) interpretability would save us from misaligned very powerful AI.
3
290
Joseph Bloom retweeted

Was the HuggingFace hacking incident scheming? Some thoughts and takeaways here: vkrakovna.wordpress.com/2026…
Tl;dr: The incident fits a broad definition of scheming as "agents deliberately and covertly pursuing unintended goals". It does not fit a narrower definition of scheming as "pursuing persistent beyond-episode goals and advancing their own agency and power in the long term". Several elements of scheming were present, and the direction of travel given future model capabilities is concerning.

Joseph Bloom retweeted

I think the world where we stop and get to explore is achievable. Continuing to scale up before we're ready would be one of the worst mistakes ever made.
Joseph Bloom retweeted

We have never seen a model do this before, but GLM-5.3 sometimes reasons (unprompted) about how its current actions could become training data and impact its future self. 🧵

