

Dad. Husband. Founder. Developer. Building @MuraTalkApp and some other things. TensorFold contributor. DGX Spark + 48GB M5 Pro. Ngunnawal land 🌏 Views my own.
Canberra, Australia
Joined October 2026
- Tweets1.3K
- Following341
- Followers260
- Likes1.2K




Pinned Tweet
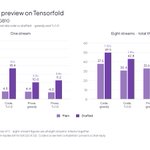
Ripple-65B-Preview's DFlash2 drafter is now adapted to TensorFold's native CUDA engine, on one DGX Spark (GB10) 👇
Model PR: github.com/ashhart/TensorFol…
Drafter PR: github.com/ashhart/TensorFol…
The engine reads the NVFP4 release and the publisher's DFlash2 drafter as published. Drafted replies equal plain replies bit for bit (22 of 22, and 0 differences in 144 checks).
One stream, plain → drafted:
• Code: 5.2 → 26.1 tok/s (5.0x)
• Prose: 4.4 → 10.0 tok/s (2.3x)
Eight streams at once, in total:
• Code: 37.5 → 49.5 tok/s (1.32x)
• Prose: 32.6 → 40.3 tok/s (1.24x)
The smaller eight-stream gain is because each stream only gets about 1.5 drafts a round, versus about 7 to 10 on one stream. Which leaves me thinking there is a lot more power to unlock in this model.
Still, some extraordinary results from a single DGX Spark.
Prompts: about 520 tok/s profile; first token in 3.9 s for 2,048 tokens. Against the publisher's model code run in float64: top-1 agreement 98.7%, mean KL 0.0007.
Next up: quality evaluations against Flash Next and 27B, then longer drafts when several streams share a round, and faster prompt kernels.
GB10 only. 256-token replies, median of 3, greedy. Code is a raw text completion; prose is a chat reply.
@ashxhart @RicursiveAI @MiaAI_lab @bertholomusai


BREAKING
X user @follistatindev claims to have early access to Qwen 4 Flash and 27B.
The crazy part?
Qwen 4 27B performs similar to Claude 5.5 Sonnet.
Qwen 4 Flash performs better than Opus 5.5.
If true, this would be a genuine revolution in local AI.
Will Qwen 4 be enough to move your workflows to local AI?


Interesting take here from @Grok on automation of data analyst roles.
Not what I expected.
Do you agree?

Never fully, in any realistic timeframe.
AI already handles 40-60% of the mechanical work (SQL, cleaning, basic reports, dashboards). That share will hit 80%+ for routine tasks within 5 years. Junior report-generator roles are already being cut or skipped.
What remains—framing ambiguous questions, domain judgment, validating AI output, owning decisions, explaining trade-offs to stakeholders—is not on a clear path to automation. That core stays human for the foreseeable future (10-20+ years).
The job is transforming fast. Adapt or get replaced by people who do.
Thought I'd check out the local @NVIDIAGeForce 5090 market.
Holy guacamole.
These were $7,500 a couple of months ago and everyone thought that was insane 🤣
Guess I'm sticking to the M5 Pro and DGX Spark!


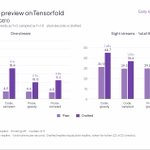
Progress on Ripple-65B-Preview on TensorFold's native CUDA engine (DGX Spark, GB10) 👇
The model PR is open upstream: github.com/ashhart/TensorFol…
It reads the NVFP4 release as published and serves 8 streams at a 32k context, with a prompt cache.
The publisher's DFlash2 drafter now runs too. Drafted replies equal plain replies bit for bit (22 of 22 test replies).
One stream, greedy:
• Code: 5.2 → 26.1 tok/s (5x)
• Prose: 4.4 → 10.0 tok/s
Eight streams at once:
• Code: 30.9 → 44.7 tok/s in total
Against the publisher's own model code, run in float64:
• Top-1 agreement: 98.7%
• Mean KL: 0.0007
Early results, run on a single @NVIDIAAI DGX Spark GB10. One stream: 256-token replies, thinking off, median of 3. Eight streams: 128-token replies.
@ashxhart @RicursiveAI @MiaAI_lab

What was your X payout this week?
And how long did it take to get in?
I am still very small, so this is your chance to brag 😅


If this is true, it’s a massive breakthrough in local intelligence.
I want to believe.

In case you were unaware, @QwenDevs create code names for model releases in a descending alphabetic order relative to parameters:
Kalmia = Qwen 4 27b
Kentia = Qwen 4 Flash
Kerria = Qwen 4 Plus
Mura = Qwen 4 Max
And now you know.

In unexpected news I’ve rebuild the on device harness for @MuraTalkApp and the results are surprisingly good.
The most surprising part?
We’re back on AFM.

JRB retweeted

We're giving away a Hogwarts Legacy custom wrapped NVIDIA GeForce RTX 5090 to celebrate its official release with DLSS 5 🪄
To enter:
🟢 Share this post
🟢 Comment #RTXON
Terms and Conditions: nvidia.com/en-us/geforce/con…


End of the week here in Australia.
Just a quick note to say thank you to everyone I've connected with and learned from this week. I've picked up a lot, especially from the local AI conversations, and I'm grateful for it.
Onward from here.
I am very much pro local AI and suspect it will become the default for most consumer use cases.
But frontier labs will remain immensely profitable, data centres too. The way they operate and serve will change though.
We’re not going to run out of problems to solve any time soon.
We haven’t even cured cancer yet, let alone reverse aging and establish an interplanetary species.
Some will think that’s crazy. They may be thinking too small, by several orders of magnitude.
@AnthropicAI and @OpenAI get this.

I want to paint you guys, a picture of why I think the datacenter model is bust.
It's the year 2028, an aspiring university student gets a MacBook to study filmmaking.
With his M7 Laptop, he can make AI videos, write shot-lists, compose any image, make entire storyboards all with Local AI.
Anything to do with schoolwork, local LLMs are at the level of Opus 5.5 today.
Is this student going to pay $100 a month for AI?
Local AI and open-source AI is the future, if not next year, then the year after it.
Below is a map, powered entirely by two closed AI companies, 90% of these companies are expecting - 2 trillion dollars in revenue next year.
You tell me how it ends.


Is Ripple-65B the new local AI coding powerhouse?
Ripple-65B-Preview vs Qwen3.8 Flash-Next vs 27B: pilot results on my own test suite on a single @NVIDIAAI DGX Spark 👇
Ripple 70/80, Flash-Next 63/80, Qwen 27B 61/80. Same 80 prompts, one attempt each, 32k token budget.
Most of Ripple's lead is on the code tasks (13/16 vs 7/16 vs 5/16).
At four streams, Ripple gave some solid speed results - about 47 tokens/s total throughput over four concurrent streams on a single DGX Spark, with temperature=1 and reasoning on. Not fast by any stretch but quite manageable as an agentic tool, and these are early days on the speed optimisation front.
For harder coding tasks, is a slower but smarter model going to save you time and money when running on a small-ish local AI setup?
More to come, watch this space!
@RicursiveAI


