

Evals @MistralAI | Previously, PhD @Cambridge_Uni
Cambridge
Joined December 2022
- Tweets208
- Following442
- Followers639
- Likes447
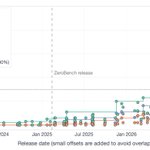


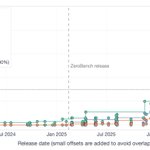



📢 Muse Spark Open w/tools scores 50% pass@5 on ZeroBench


👀 DeepSeek-V4.1-Flash-1017 scores 51% pass@5 on ZeroBench w/ tools

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


Jonathan Roberts retweeted

nothing to report
opus 5.5 max looks on/above trend for the ai futures model
(added to the eci graph from the august update)
wide CIs yada yada

Jonathan Roberts retweeted
Mistral Large 4 is one of the world's strongest AI models for cybersecurity.

Jonathan Roberts retweeted
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
🤖 Made with AI
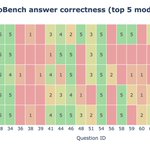
Opus 5.5 (max) is no.2 on ZeroBench
43% pass@5
25% pass^5
Now, 77% of questions have been solved at least once

All three GPT-6 models sit on the ZeroBench performance-cost pareto frontier
pass@5 | pass^5
GPT-6 Astra (max)
51% | 35%
GPT-6 Sol (max)
41% | 17%
GPT-6 Luna (max)
20% | 7%

GPT-6 Astra (max) on ZeroBench:
pass@5: 51% (prev. SOTA: 30%)
pass^5: 35% (prev. SOTA: 13%)
If this reflects a genuine capability improvement, it is a significant step forward in both performance and consistency

Jonathan Roberts retweeted

Now let’s take a look at how Muse Spark 1.2 performs across visual reasoning, chart understanding, and knowledge-intensive tasks.


