

physics, AI
Joined December 2011
- Tweets683
- Following397
- Followers2.8K
- Likes1.1K





Pinned Tweet
An absolutely incredible, highly interconnected web of ideas connecting some of the most important discoveries of late twentieth century physics and mathematics. This is an extremely abridged, biased history (1970-2010) with many truly ground-breaking works still not mentioned:
Maissam Barkeshli retweeted

Interestingly, Claude has also refuted the exponential-time hypothesis.
hexagonmath.org/2610.00577v1

Maissam Barkeshli retweeted

A multilingual LLM encodes a sentence and its translation almost identically - the “platonic representation hypothesis.” Observed, never explained. The facts pile up: similarity peaks in the middle layers (not the ends), coexists with language-specific structure, and grows with language proximity, model quality, and data. We explain all of them -and predict something new: remove from each layer the part linearly predictable from the previous one, and cross-lingual similarity rises. Confirmed in real LLMs.

Maissam Barkeshli retweeted

An astrophysicist worked with Claude Science to create the first complete ultraviolet map of the sky. Astronomers have already created complete sky maps from radio to gamma rays. But large regions of the sky have never been observed in UV.
In today’s science blog, Brice Ménard explains how he guided Claude to find existing datasets, combine them, and fill in the gaps with statistical inference. The work would have taken humans weeks of work, but, with Claude, just took a few days while Ménard worked on other projects.
The resulting map is a useful teaching tool and an example of exactly the sort of slow, low-priority work which scientists never quite get around to, but which AI now makes feasible.
Read more: anthropic.com/research/the-m…

Maissam Barkeshli retweeted
New on the Science Blog: Yes, Claude can do Nine Loops.
Theoretical physicists predict how particles behave using formulas called scattering amplitudes. These are notoriously hard to compute, so researchers work with layers of increasingly fine corrections called “loops”—each added loop makes the answer more precise but takes exponentially more computation. Most calculations stop at two or three loops. Eight loops was the previous record in a simplified model physicists use as a testing ground (planar N=4 super-Yang-Mills), set by SLAC's Lance Dixon and collaborators.
Last month, physicist and science writer @4gravitons issued a challenge: could an AI push past eight loops in this model, using only the compute budget an academic could reasonably access?
Given a single prompt describing the nine-loop problem, Claude ran largely unsupervised for days in Claude Science and solved it using methods developed by Dixon and his colleagues, at a total cost of a few thousand dollars. Dixon independently verified the result, and von Hippel wrote about the experience for our blog.
Read more: anthropic.com/research/yes-c…

Maissam Barkeshli retweeted

Our new paper "Deriving neural scaling laws from the statistics of natural language" arxiv.org/abs/2602.07488 lead by @Fraccagnetta & @AllanRaventos w/ Matthieu Wyart makes a breakthrough! We can predict data-limited neural scaling law exponents from first principles using the structure of natural language itself for the very first time!
If you give us two properties of your natural language dataset:
1) How conditional entropy of the next token decays with conditioning length.
2) How pairwise token correlations decay with time separation.
Then we can give you the exponent of the neural scaling law (loss versus data amount) through a simple formula!
The key idea is that as you increase the amount of training data, models can look further back in the past to predict, and as long as they do this well, the conditional entropy of the next token, conditioned on all tokens up to this data-dependent prediction time horizon, completely governs the loss! This gets us our simple formula for the neural scaling law!

Nice to make some progress on a basic topic in theoretical physics -- universal response of emergent Dirac fermions to crystal defects. Now published in @PhysRevX , with @ZoharKo , @CFechisin , Siwei Zhong. @JQInews @UMDPhysics


By studying how symmetries of lattice models map to symmetries of continuum theories that
emerge at criticality, researchers show that the (2+1)D Dirac fermion exhibits a continuum of infrared fixed points at a particular applied magnetic flux.
go.aps.org/46h8ACo

ALT A graph of the QWZ model with a clean lattice showing the azimuthal current and energy density, with δα on the x axis, r^3ε on the left y axis colored red, and rJ^θ on the right y axis colored blue. The plot shows observables at the m = −1 critical point on a lattice without crystalline defects, scaling by r and r^3 respectively in order to extract the universal amplitude data. Each curve gives the values of the observables at a particular spatial position in the bulk of the lattice. The shading of the curve corresponds to the distance of the spatial point from the flux insertion center, with lighter colors closer.
Our ICLR 2026 paper shows how transformers can learn pseudo-random numbers.
We demonstrate successful in-context prediction of pseudo-random sequences from permuted congruential generators, which are used in practice in NumPy. We succesfully attacked PCGs with moduli up to 2^22.
Surprisingly, the transformer can learn the sequence even when only one bit is output from the hidden state.
We found that curriculum learning is essential for these problems.
We also found novel structures in the embedding layers: the model spontaneously clusters numbers according to how their bit strings transform under rotations.


Link to the paper: arxiv.org/abs/2510.26792

Scaling laws in AI – where do they come from?
The discovery of neural scaling laws several years ago showed that the loss decreases predictably as a power law in model size, amount of data, and compute. But why? And what sets the exponents of the power law?
The most popular explanation is that the dataset already has power law correlations in it (for example, power laws are prevalent in natural language corpora, e.g. Zipf’s law, etc), which translate to power laws in the loss.
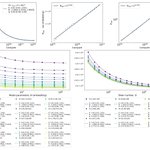
We studied transformers performing next token prediction on sequences coming from random walks on random graphs, where the data has no power law correlations. Nevertheless, after training the model, we observed power laws in the loss that look similar to those found in natural language. For example, here are results from a random walk on an Erdös-Renyi graph with 8K edges and 50K nodes:
This challenges existing explanations, since this dataset of random walks falls outside of the assumptions made in existing models of scaling laws. Going forward, we need explanations of scaling laws based on expressivity and learnability of discrete data, where there is no data manifold, and which do not require the data to already have power laws built in.
We also found a setting where we could tune the complexity of a language dataset by starting with a bigram model and gradually dialing up complexity until we get to natural language. This allowed us to track how the exponents of the scaling laws change with complexity:


The full story is in our recent paper, arxiv.org/abs/2601.10684 .
Thanks to @Andr3yGR @albe_alfa for the collaboration

Maissam Barkeshli retweeted
We have 14 survey lectures for our @SimonsFdn Collaboration on the Physics of Learning and Neural Computation! All videos available at: physicsoflearning.org/webina…
Here is the list:
@zdeborova: Attention-based models and how to solve them using tools from quadratic networks and matrix denoising
@KempeLab: Recent lessons from LLM reasoning
@MBarkeshli: Sharpness dynamics in neural network training
@KrzakalaF: How Do Neural Networks Learn Simple Functions with Gradient Descent?
Michael Douglas: Mathematics, Economics and AI
Yuhai Tu: Towards a Physics-based Theoretical Foundation for Deep Learning: Stochastic Learning Dynamics and Generalization
@SuryaGanguli: An analytic theory of creativity for convolutional diffusion models
Eva Silverstein: Hamiltonian dynamics for stabilizing neural simulation-based inference
@adnarim066: Generation with Unified Diffusion
Bernd Rosenow: Random matrix analysis of neural networks: distinguishing noise from learned information
@jhhalverson Nerual networks and conformal field theory
@KempeLab Synthetic data: friend or foe in the age of scaling
@WyartMatthieu Learning hierarchical representations with deep architectures
@CPehlevan Mean-field theory of deep network learning dynamics and applications to neural scaling laws


Wonderful workshop at Harvard on AI + math, I’m grateful to have been a part of it!


Maissam Barkeshli retweeted

Many thanks to the speakers! Amazing week.
@MBarkeshli @evelovesolive Adam Brown, Bennett Chow, Michael Freedman, @ElliotGlazer @jhhalverson @jessemhan @jdlichtman Junehyuk Jung @AlexKontorovich @ylecun Brice Ménard, Michael Mulligan, also Michael R. Douglas

AI and math. Geometry and symbolic reasoning. Amazing recent developments and stellar line up of speakers. It is going to be an exciting week!
The Geometry of Machine Learning @ Harvard Center for Mathematical Sciences and Applications (CMSA)
cmsa.fas.harvard.edu/event/m…

Maissam Barkeshli retweeted
A nice @Stanford news report on how university research is essential for understanding AI and sharing these insights openly with the world. humsci.stanford.edu/feature/…

Maissam Barkeshli retweeted

Under the leadership of @Stanford's @SuryaGanguli, our new Simons Collaboration on the Physics of Learning and Neural Computation will study the fundamental scientific principles underlying AI: simonsfoundation.org/2025/08… #science

I’m excited to be part of the new @SimonsFdn Simons Collaboration on the Physics of Learning and Neural Computation!

Our new Simons Collaboration on the Physics of Learning and Neural Computation will employ and develop powerful tools from #physics, #math, computer science and theoretical #neuroscience to understand how large neural networks learn, compute, scale, reason and imagine: simonsfoundation.org/2025/08…
Maissam Barkeshli retweeted

🤖 Transformers can write poetry, code, and generate stunning art, but can they predict seemingly random numbers?
We show that they learn to predict simple PRNGs (LCGs) by figuring out prime factorization on their own!🤯
Find Darshil tomorrow, 11am at #ICML2025 poster session!

🚨 ICML 2025 🚨
I'll be at @icmlconf Mon-Fri. DM if you'd like to chat!☕️
Also come check out our poster on cracking Pseudo-Random Number Generators with Transformers!
🕚 Tuesday @ 11am
#⃣ E-1206
🔗arxiv.org/abs/2502.10390


