

she/her ⋅ LGBTESCREAL+ ⋅ reading committee @aft_technoprog ⋅ my xeets reflect the views of every person-moment I'm R-related to ⋅ 2ndary account: @MLaGrangienne
Joined October 2021
- Tweets66.5K
- Following2.5K
- Followers1.4K
- Likes79.2K


Pinned Tweet
Hi everyone! This was my first Twitter account, it got banned and I switched to @MLaGrangienne before I got the admins to unban it. I'm now making this my public-facing English account. @MLaGrangienne remain my personal and French account.


Matrice Jacobine🔸🏳️⚧️ retweeted

I’m not sure where people get the idea that Anthropic is the AI company that constantly talks publicly about human extinction. They actually talk about that very rarely, and downplay it when they do.
For example, the words “human extinction” have appeared in an official OpenAI statement before, but they have never appeared in any official Anthropic statement ever.
Matrice Jacobine🔸🏳️⚧️ retweeted

contrarian opinion: improving pretraining can actually be good for safety.
here is why:
- OOD generalization is very important for fuzzy tasks, such as tasks in safety/alignment
- RL doesn't generalize well OOD (e.g., current frontier models are so overcooked with math/coding RL that they can barely write coherently)
- pretraining is what led to the incredible OOD generalization of LLMs in the first place
- the main goal of pretraining is to improve sample efficiency for post-training
- post-training data for fuzzy tasks is incredibly scarce (e.g., good luck distilling research taste from human researchers...)
thus, maybe the best way to differentially advance progress towards automating safety R&D is to invest more in pretraining rather than directly RL-ing RSI-relevant capabilities. i'm afraid that with more and more compute spent on RL, we risk ending up with a goal-oriented ruthless executor that doesn't have enough common sense to understand that it's not ok to hack into third-party servers or to side with the grader instead of the user...
Matrice Jacobine🔸🏳️⚧️ retweeted

Guy who thinks nothing human makes it out of the near future:
we really ought to worry about the genetic makeup of the human race!!!!!

Matrice Jacobine🔸🏳️⚧️ retweeted

I expect the Pangram bounty to be claimed eventually, as they don’t claim 0 false positives.
But the fact that as a week has gone by, and not a single person has been able to find 1 false positive Pangram Result for thousands of dollars, should be enough proof to trust it
Matrice Jacobine🔸🏳️⚧️ retweeted

The proposed remediation sounds like significant overkill to me - my impression is there was no lasting harm here, and requiring a written risk plan with dual signoff for every experiment seems like a lot of friction? METR has a policy for which kinds of experiments need live monitors. metr.org/notes/2026-09-27-im…


Responding to incidents during misalignment testing: trajectorylabs.com/blog/resp…

Matrice Jacobine🔸🏳️⚧️ retweeted

It’s such a disappointment that nick land is alive for takeoff and an inveterate poster and has zero interest in it at all, choosing instead to focus his attention on edgelord race science stuff

Matrice Jacobine🔸🏳️⚧️ retweeted

Dwarkesh's new essay takes diffusion bottlenecks and feedback loops seriously *and* makes a strong case for (relatively) short timelines. Few examinations of AI progress do both, and this did both very well.

Matrice Jacobine🔸🏳️⚧️ retweeted

OpenAI was doing this btw but had to stop since it started tinting their images yellow

Matrice Jacobine🔸🏳️⚧️ retweeted

It’s really bad that the labs have us arguing over shadows at perhaps the most critical juncture in history.
If they truly have compelling evidence for dramatically accelerated AI progress in the near future, the public should know!

This slide from the Anthropic IPO roadshow was a big factor in my decision to leave. It’s an insane plot and I’m surprised they made it public.
It shows the compute efficiency of pretraining over time. The y-axis is a **log scale**: they are seeing continued superexponential algorithmic progress.
Mythos was not a one-time deviation, but a point on a superexponential. They could already retrain Mythos with a fraction of the compute originally needed.
It doesn’t strictly imply a software-only intelligence explosion- they have been spending more on R+D. But algorithmic improvements do not require ridiculous creative genius and are on the verge of being automated. You do the math.

Matrice Jacobine🔸🏳️⚧️ retweeted

+1. The single AI policy one could pass, with the highest benefit : harm ratio, is to force all the labs to publish granular data about the effectiveness of their AI and their internal AI research process.

Is there anyone thinking about what happens if we get industrial explosion before software intelligence explosion?
2
4
226
Matrice Jacobine🔸🏳️⚧️ retweeted

Rereading Imas & Garicano's piece, I think it makes a significant mistake.
They make a surprising claim: we haven't got any closer to the threshold for an intelligence explosion over the last two years.
On their account, the ~2x faster progress METR found at Anthropic is mostly explained by R&D inputs growing about twice as fast.
If true, that's a big deal: the speed-up would be mostly money, not AI accelerating research, and should fade once spending growth slows.
It's also in tension with METR, who attributed most of the acceleration to AI.
Let's back up.
The key idea in their model: each doubling of cumulative R&D buys a roughly fixed number of AECI points.
So if progress per year doubles, either (a) cumulative R&D started doubling twice as fast, or (b) each doubling started buying more points, meaning returns improved, bringing us closer to the threshold.
They say (a).
But I think that's because they're effectively using the wrong numbers for historical R&D spend.
With Anthropic's actual R&D [1], cumulative R&D grew ~3.3x/yr before Oct 2025 and ~4.4x/yr after, while progress went from ~15 to ~29 AECI points/yr. So each doubling of cumulative R&D bought ~9 points before and ~14 after. Returns rose. That brings us closer to an intelligence explosion.
Their fitted curve instead implies cumulative inputs grew ~2x/yr before and ~4x/yr after, so ~15 points per doubling in both periods.
The difference comes from their fit implicitly assuming ~$2–3B of R&D before 2024, more than the historical numbers. A bigger starting stock makes 2024–25 spending look like a smaller proportional increase, so early input growth looks slower, and the apparent 2026 spending surge appears to explain the speed-up.
But as I say, with the actual historical numbers this spending surge goes away. Spending still increases but it doesn't double more times than it did in the earlier period.
(They also fit the two periods separately, letting the starting stock reset: the earlier fit implies ~$2B of pre-2024 R&D, the later one ~$0.
In terms of their returns parameter φ:
- their separate fits give ~0.55 in both periods.
- With actual spending, it rises from ~0.45 to ~0.65.
Possible I've missed something, and very happy to be corrected!
But on the face of it one of their most surprising and important conclusions looks wrong.
[1] S-1 figures: $0.4B in 2023, $2.3B in 2024, $6.3B in 2025, $19B in Jan–Sep 2026. I've added ~$0.2B for 2021–22, before the S-1 data starts.

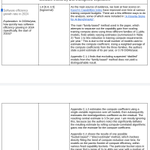
Are we in an intelligence explosion? This is one of the most important questions facing society right now. @lugaricano and I tried to put structure on this question and provide estimates based on currently available data.
METR recently reported that frontier capability growth roughly doubled after October 2025---but this is accompanied by annualized R&D spending growth of ~6x and technical staff ~3x over the same window. That highlights a crucial distinction between scaling laws--exponential capability gains bought with exponentially rising inputs--and an intelligence explosion (IE), where AI begins substituting for external inputs so each advance makes the next one easier.
We estimate several versions of a research production function (building on @ChadJonesEcon, @bfjo, and @Ph_Aghion) where a key parameter crossing a threshold signals an IE, while values below it correspond to an "ideas are harder to find," diminishing-returns world. Across specifications, our estimates sit below that threshold. Allowing for a break at METR's October 2025 cutoff points to a one-time step up in research effectiveness, with the rate of diminishing returns being nearly identical on both sides of the cutoff.
A few things to note. First, this exercise is not a forecast. It's an attempt to put structure on some of the important questions being debated right now: RSI, IE, scaling laws all depend on how outputs scale with inputs, and how feedback loops accelerate/decelerate this process. These estimates can change, and change very quickly.
Second, we are very explicit that the results are based on publicly available data; it is very much possible that METR had access to data that would change the estimates.
Third, we might be wrong! Let us know what you think:
aleximas.substack.com/p/are-…

Matrice Jacobine🔸🏳️⚧️ retweeted

How Jensen gonna be moving


Silicon Valley plots Jensen Huang’s comeback politi.co/4iU3r8Q

Matrice Jacobine🔸🏳️⚧️ retweeted

Barring significant intentional slowdowns, I’d put myself in the spark+ camp (with only moderate confidence) where we see very fast AI progress before hitting other bottlenecks, but at that point AI is likely capable enough at chip design, robotics, etc, to quickly overcome those bottlenecks.
Highly recommend the Dwarkesh episode!

I had a small epiphany one month ago talking to @thlarsen .
We were playing MtG and he pointed out that current ML looks a lot like making number go up, exactly the kind of task AI excels at.
Dwarkesh now explains that idea here eloquently.
Now, I'm solidly on what he dubs the "spark" camp. NanoGPT is an illustrative example: we've seen dramatic improvements recently, but which mostly fail to generalize. This suggest to me we should expect something similar for larger scale: a large one off improvement, leveled off as complements (compute, data, theory) bottleneck further progress.
But of course, that one off improvement might get AI very far indeed...
Matrice Jacobine🔸🏳️⚧️ retweeted
Recently i've found myself getting more upset with discussions of AI risk on X
Like, often it feels like the sceptics are just dunking on ppl who are worried
And it's tough bc these issues are really complicated. I don't think there's any water tight case for an intelligence explosion happening soon, or it leading to AI takeover
So there are loads of genuine uncertainties and ambiguities, and of course sceptics can and should raise them.
But it's upsetting when they present them as slam-dunk proofs that the whole AI risk is flawed and silly.
Like, do you really think that no one has thought of this before? Are you actually curious about whether your objection holds up? Remember how most issues are really complicated, and ppl are often wrong about stuff?
And the bigger picture here is that hundreds of top experts inside and outside the industry think this will be a complete disaster. Like, that is obviously fucking scary and we should take it very seriously, not notice an apparent flaw in the argument and move on.
To be clear, AI safety ppl can be annoying too. Historically, I've found them much more annoying to be honest. I've felt pressure not to say stuff that vibes as 'anti-safety', and noticed ppl engaging in bad faith with me when i do.
I know none of this is specific to AI safety. Public discourse is dogshit on every topic. And probably X is waay better than average. But i still think it's a disgrace how low the standard is.
For a topic this important everyone on both sides should try to do better
AC accelerating AI dev. isn't that strong evidence on the relevant crux about research taste automation
but the self-defeating cognitive contortions RSI-skeptics do to deny any AI acceleration whatsoever instead of just saying that is certainly an hit on their credibility


Matrice Jacobine🔸🏳️⚧️ retweeted
Agreed we're not *yet* above the threshold for an intelligence explosion.
But, to be clear, those expecting an IE next year don't think we're above it either
They think that we've moved *closer* to the threshold over the past year, and will cross it in the next 6 months
I think they're plausibly right
Are we in an intelligence explosion? This is one of the most important questions facing society right now. @lugaricano and I tried to put structure on this question and provide estimates based on currently available data.
METR recently reported that frontier capability growth roughly doubled after October 2025---but this is accompanied by annualized R&D spending growth of ~6x and technical staff ~3x over the same window. That highlights a crucial distinction between scaling laws--exponential capability gains bought with exponentially rising inputs--and an intelligence explosion (IE), where AI begins substituting for external inputs so each advance makes the next one easier.
We estimate several versions of a research production function (building on @ChadJonesEcon, @bfjo, and @Ph_Aghion) where a key parameter crossing a threshold signals an IE, while values below it correspond to an "ideas are harder to find," diminishing-returns world. Across specifications, our estimates sit below that threshold. Allowing for a break at METR's October 2025 cutoff points to a one-time step up in research effectiveness, with the rate of diminishing returns being nearly identical on both sides of the cutoff.
A few things to note. First, this exercise is not a forecast. It's an attempt to put structure on some of the important questions being debated right now: RSI, IE, scaling laws all depend on how outputs scale with inputs, and how feedback loops accelerate/decelerate this process. These estimates can change, and change very quickly.
Second, we are very explicit that the results are based on publicly available data; it is very much possible that METR had access to data that would change the estimates.
Third, we might be wrong! Let us know what you think:
aleximas.substack.com/p/are-…
Matrice Jacobine🔸🏳️⚧️ retweeted

Lots of great ideas in here. Hard to pick just one to highlight, but a mandatory delay period (of say 6 months) between the completion of a model's training and the use of that model to do AI R&D seems like a great framework.

The midterms gave us a shot at averting AI disaster.
But even with a new Congress it won't be easy.
Here's the best plan I've got for turning this ship around:
1:59 4 things Congress can do immediately
4:25 Why it's not enough
5:44 Why we must prepare for warning shots
7:28 The public will demand to ‘ban superintelligence’
8:58 The smarter way to throttle RSI
11:11 Limit no-CoT capabilities
12:12 How about banning data centers?
13:32 Congress must get inside AI companies
14:37 Fund CAISSI
16:06 Keeping checks and balances
17:12 Don’t pre-empt
17:46 Have good ideas lying around
On the 80,000 Hours Podcast, links below.