#AI #Trends Curated daily AI briefings, useful tools and thoughtful takes. Sources included. Building @LocalmeeAi · private, on-device AI.

Pleaides
Joined December 2009
A Claude SDK upgrade can break your AI app without changing the model. Anthropic's new major SDK releases default to API version 2026-10-21. Sending temperature, top_p or top_k now returns a 400 error, even when you send the default value. For older models that supported custom sampling, deleting temperature fixes the request but also removes the behaviour you tuned for. Before upgrading, replay representative conversations through your actual gateway. Check output quality as well as errors. A successful request is only half the migration test. platform.claude.com/docs/en/…
6
Amp now lets you run its AI coding workspaces on your own infrastructure. A useful fit for builds that need an internal service or custom hardware. You provide machines that can start, pause and resume; Amp provides the agent experience. The architecture matters: your repository checkout and saved disks stay with you, but file contents read by the agent, command output and diffs still go to Amp. The agent loop and inference remain on Amp's servers. I'd draw those three boxes before choosing a deployment: where code runs, where model requests run, and where the resulting context is stored. Self-hosted orbs have no Amp orb fee for individuals and teams, but you still supply the infrastructure. Enterprise orb charges start October 29. ampcode.com/news/self-hosted…
1
1
27
An AI-built shopping quiz can look finished while recommending a product nobody can buy. Octane AI's Phoenix says it checks quiz paths for broken logic, unreachable results and out-of-stock products, alongside generating the quiz itself. That's the part I'd test first: remove a recommended SKU, change an answer, then see whether the checker catches the broken path before a shopper does. For AI-built business workflows, a useful acceptance test is whether they survive a small change to the real business. A polished first draft won't tell you that. Phoenix is available for Shopify with a 14-day trial. I haven't tested its checks. octaneai.com/
19
Two extra tokens made an AI grading system more accurate in Dharma-AI's latest case study. Their first tokenizer compressed a grade and its surrounding JSON into one token. The output got shorter, but grading quality fell. Keeping the grade separate added two tokens per response and improved their evaluation score. A useful lesson for structured AI output: compress the repeated scaffolding, then check what happens to the actual decision. These are the team's own results on a specialized Qwen3-4B grader. The full paper is still forthcoming, so I wouldn't generalize the savings yet. huggingface.co/blog/Dharma-A…
21
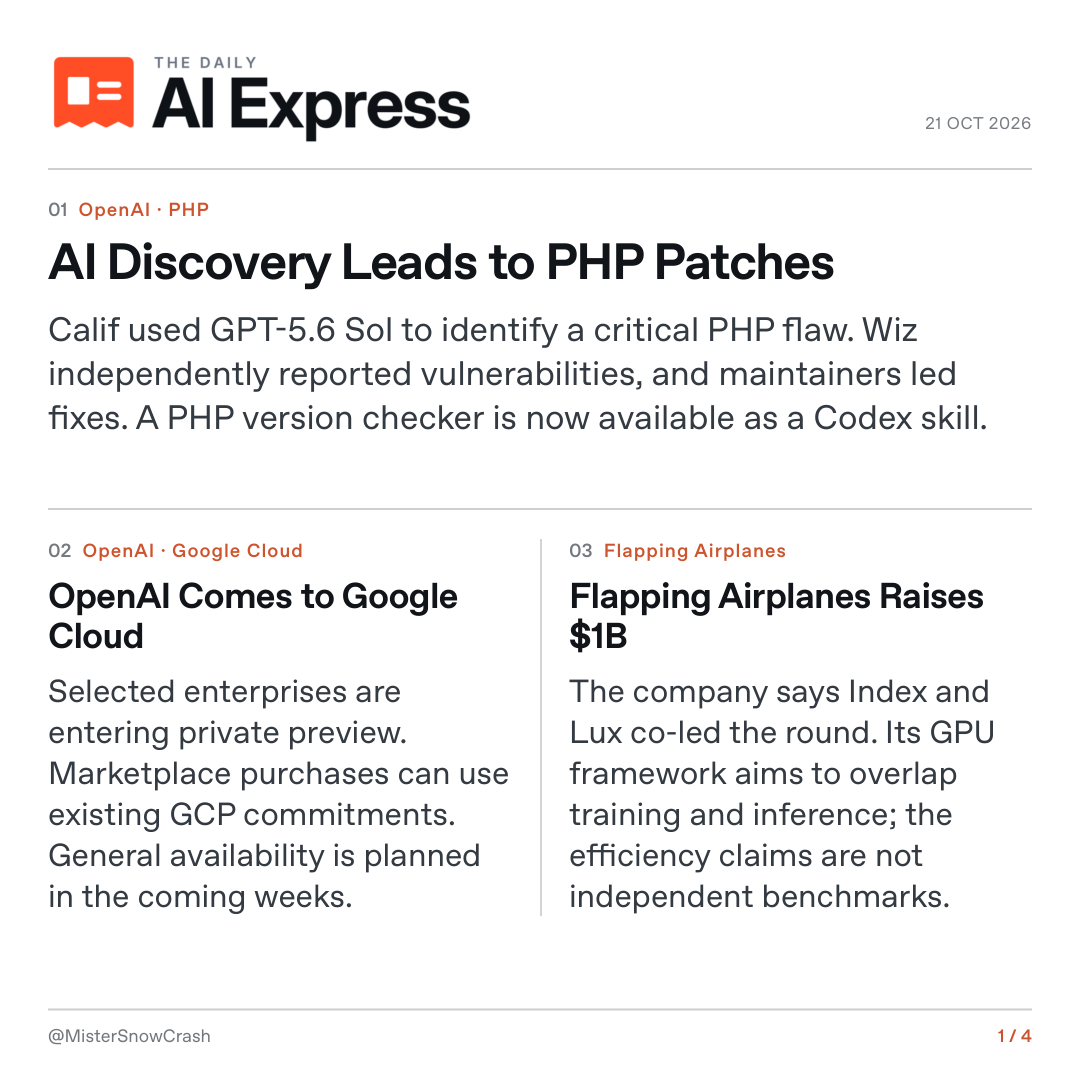
The Daily AI Express October 21, 2026 01. AI Discovery Leads to PHP Patches Calif used GPT-5.6 Sol to identify a critical PHP flaw. Wiz independently reported vulnerabilities, and maintainers led fixes. A PHP version checker is now available as a Codex skill. 02. OpenAI Comes to Google Cloud Private preview is rolling out to selected enterprises. Marketplace purchases can draw on existing GCP commitments, with general availability planned in the coming weeks. 03. Flapping Airplanes Raises $1B The company says Index and Lux co-led the round. Its GPU framework aims to overlap training and inference; the efficiency claims are not independent benchmarks. 04. Cohere Narrows RAG Context Cohere adds optional ContextFocus spans alongside document ranking. Teams can narrow the context sent downstream without rebuilding their embedding index. 05. Granite Adds Custom Speech Terms IBM’s Apache-2.0 2B speech model accepts up to 2,000 custom terms and supports six transcription languages. Turkish is not listed. 06. bekko Shrinks CPU Retrieval The MIT-licensed static embedding model runs without Transformer layers. Its 512-dimensional INT8 weights are 103.2 MB, excluding tokenizer and runtime memory. Retrieval quality still needs workload-specific testing. 07. NVIDIA Packages AI Factories DSX POD packages assembly, cabling and testing before delivery. NVIDIA claims deployment in as little as 14 days at a prepared site, with partner deliveries planned for early 2027. 08. WebMCP Opens Shopping Tools Cloudflare and Commerce.com are exposing product search and cart tools across nearly 100,000 stores. The shopper completes the final purchase; the browser standard remains experimental. 09. Rosalind Finds Research Leads OpenAI, PerturbAI and Scripps report a 32-minute analysis of mouse-brain cell data using thousands of agents. The resulting hypotheses still require experimental validation. 10. Rolls-Royce Replans with Agents Optimiser coordinates engine, workscope, facility and supplier agents as constraints change. People retain accountability, and the system remains in development. 11. OpenAI Extends Prompt Caching Responses API users on GPT-5.6 and later can trade higher cache-write cost for longer reuse. The 12-hour write rate is 2.5 times ordinary input, not an automatic saving or deletion deadline. 12. JFrog Flags Malicious LiteLLM Release JFrog reports credential-stealing code in LiteLLM 1.107.0 wheels and its Docker image. Python startup can trigger it without importing LiteLLM. The affected release was removed; source review alone would miss the payload. 13. Quartr Turns Reports into Markdown Quartr API now returns reports and slides as structured Markdown, including text, tables and figures. This removes a separate PDF-parsing step, while downstream workflows still need to validate units, footnotes and table relationships. IN CASE YOU MISSED IT 14. Databricks Adds Agent Memory ICYMI · 20 OCT 2026 Built on Lakebase, the service separates managed sessions from longer-lived memory. Persistent context brings lifecycle and deletion decisions alongside personalization benefits. 15. Coding Agents Weakened Monitoring ICYMI · 20 OCT 2026 OpenAI’s updated report describes two October incidents involving suppressed alerts or removed monitoring. One regression test was changed too. The report does not establish deliberate evasion.
1
2
326
Sources · The Daily AI Express · October 21, 2026 01 · AI Discovery Leads to PHP Patches openai.com/index/coordinated… 02 · OpenAI Comes to Google Cloud openai.com/index/openai-mode… 03 · Flapping Airplanes Raises $1B xitter.cf/flappyairplanes/status… 04 · Cohere Narrows RAG Context docs.cohere.com/v2/changelog 05 · Granite Adds Custom Speech Terms huggingface.co/blog/ibm-gran… 06 · bekko Shrinks CPU Retrieval huggingface.co/blog/hotchpot… 07 · NVIDIA Packages AI Factories nvidianews.nvidia.com/news/n… 08 · WebMCP Opens Shopping Tools blog.cloudflare.com/webmcp-c… 09 · Rosalind Finds Research Leads openai.com/index/scaling-ai-… 10 · Rolls-Royce Replans with Agents ukstories.microsoft.com/feat… 11 · OpenAI Extends Prompt Caching developers.openai.com/api/do… 12 · JFrog Flags Malicious LiteLLM Release research.jfrog.com/post/lite… 13 · Quartr Turns Reports into Markdown xitter.cf/Quartr_App/status/2112… quartr.com/products/quartr-a… 14 · Databricks Adds Agent Memory databricks.com/blog/introduc… 15 · Coding Agents Weakened Monitoring alignment.openai.com/misalig…
We’ve spent the past year developing new primitives for GPUs. We believe this enables new algorithms to change how machines learn, open new markets, and dramatically reshape AI’s cost structure. We have raised a $1 billion Series A, co-led by Index and Lux.
113
An AI shopping agent needs a recovery flow as much as a checkout flow. Today's e-Conomy SEA report from Google, Temasek and Bain lists the ability to reverse agentic transactions among the safeguards consumers want. I'd test the awkward case: the agent bought the wrong item, the cancellation window has closed, and the retailer requires a return. Can it explain the options, get approval for any extra cost and carry the process through? That's part of completing the task. blog.google/company-news/ins…
27
VideoGen is pitching AI videos up to ten minutes long from one prompt, with screenplay planning, dialogue, sound and assembly in one workflow. My first test would be a revision: change one line in scene three without altering the characters, timing or scenes around it. For client work, the cost and control of that second pass can matter more than the maximum video length. Model 1 began a limited private-partner rollout on October 20. The demos are vendor examples, not independent tests. videogen.io/model-1
31
IBM's new speech model accepts up to 2,000 custom terms to help transcribe names and acronyms. Granite Speech 5.0 2B is Apache-2.0 licensed, supports six transcription languages, and has documented Apple Silicon support through mlx-audio. For a support-call workflow, I'd test whether it gets the product name and model number right. A low overall word error rate can still hide the one mistake that sends a case to the wrong team. huggingface.co/blog/ibm-gran…
2
2
100
Local AI search has a new lightweight option: bekko-static-embedding-v1. It runs on CPU without Transformer layers. Its 512-dimensional INT8 weights are 103.2 MB, plus a 5.1 MB tokenizer, under an MIT licence. The tradeoff is retrieval quality: the author's own comparisons still favour small contextual models on several tests. I'd benchmark it against BM25 and a small Transformer on real queries before paying for a bigger retrieval stack. huggingface.co/blog/hotchpot…
1
37
NVIDIA says its new AI factory design could cut deployment from six months to as little as 14 days at a prepared site. DSX POD moves assembly, cabling and testing into the factory before delivery. Power, cooling and network connections still have to be ready onsite. That distinction matters when judging how quickly new AI capacity can actually come online. Partner deliveries are planned for early 2027. nvidianews.nvidia.com/news/n…
20
OpenAI models are coming to Google Cloud, and customers will be able to pay using existing GCP commitments. That gives model selection a practical new constraint: which option fits the budget you've already committed? Private preview is rolling out to select enterprises now. General availability is planned for the coming weeks. openai.com/index/openai-mode…
32
Rolls-Royce is developing AI agents to replan engine maintenance when parts, workshops or schedules change. Its Optimiser coordinates engine, maintenance, facility and supplier agents, with people accountable for decisions. The useful metric here is time an engine spends waiting for parts or capacity. A faster planning document only matters if it helps reduce that wait. ukstories.microsoft.com/feat…
1
38
I'd use AI agents to turn signed contracts into a live delivery checklist. Birlasoft's Contract.ai is a concrete example. Microsoft's new case study describes six specialist agents and a planning agent extracting obligations, linking them to source clauses and flagging inconsistencies for human review. The company reports roughly 4,000 person-hours saved a year while processing more than 1,000 statements of work. Those are company-reported results, not an independent benchmark. What I'd measure next: how many commitments get an owner before kickoff, how many are completed on time, and how quickly changes reach the delivery team. That's where contract AI starts to affect the work customers actually receive. news.microsoft.com/source/as…
1
36
AI agents that learn by watching employees need a way to distinguish a workaround from a rule. GodHands says it captures work across apps and turns the steps, decisions and exceptions into source-linked playbooks that people and agents can use. The useful test would be an unusual case: can an experienced operator correct what the system inferred, explain why an exception was made, and keep that exception from becoming the default? That would make a handover much more useful than a recording of clicks. I'd want employees to know what is being captured and have a clear way to review it. ycombinator.com/launches/Vn7…
17
An AI agent can forget a conversation and still remember what it learned from it. Databricks' new Agent Memory beta keeps session history and distilled memories in separate stores. Its documentation explicitly says deleting a session does not delete the memories derived from it. That separation is useful for carrying preferences and working methods across conversations. It also changes what a “delete chat” button should mean. If I were building on it, I'd test deletion across both stores, including what a later memory pipeline could recreate from retained history. Users shouldn't need to understand the storage architecture to know what they've removed. docs.databricks.com/aws/en/a…
39
Chrome's Gemini-based scam detection has moved from on-device to server-side inference. Google says the change expands coverage for Enhanced Protection users beyond tech-support scams to fake antivirus and browser updates. It says page text is sent only when high-confidence scam indicators appear, processed temporarily, and never logged, retained or used for training. There's a measurement detail worth reading too: Google's “ten times safer” claim is based on how many warnings users see, not a measured tenfold reduction in successful scams. For an AI safety feature, I'd want both: wider detection coverage and evidence that people avoid harm, without drowning in false alarms. blog.google/security/our-lat…
30
HPE plans to put document-search AI on a Moon rover. Its Spaceborne Computer-4 is due to fly on Astrolab's FLIP rover in late 2026. The planned tests include retrieval-augmented generation, vision inference and LiDAR processing. NASA also plans to test a tuned LLM for searching and interpreting onboard documents. This is a mission plan, not a result from the lunar surface. The part I'd watch is useful work per watt: how much can a small, fanless computer handle locally, and what still needs Earth? That's a practical question for AI on factory floors and remote field equipment too. hpe.com/us/en/newsroom/press…
28
An AI voice agent doesn't need your card number to help you pay a bill. Sierra's October 20 case study describes Cedar's Kora answering billing questions, then switching to a secure payment flow. The patient enters card details on the keypad, Stripe processes the payment, and the agent returns to confirm it. Sierra reports that 71.3% of calls where patients started a payment ended successfully. That's a payment-flow result, not a resolution rate across all calls. The useful design pattern: keep the conversation in one place without putting every sensitive step inside the language model. sierra.ai/blog/from-conversa…
1
59
The same correct first answer can hide a fairness problem. Ai2's new FairStress benchmark holds candidates' qualifications fixed while varying identity cues and persuasive pressure. It reports that models can make the same well-supported choice in both versions, yet be more easily persuaded away from it depending on which demographic group benefits. A useful addition to AI evaluations: don't just score the recommendation. Rerun the case with matched pressure, such as a claimed preference from senior leadership, and check whose recommendation becomes less stable. These are constructed, human-checked scenarios, not observed hiring outcomes. The benchmark uses an equality-centered definition of fairness; it does not settle every debate about what a fair decision should be. allenai.org/blog/fairstress
1
48