
Working on bringing local AI to every phone and laptop. Previously @Meta
Manhattan
Joined August 2026
- Tweets274
- Following331
- Followers451
- Likes1.6K




Pinned Tweet
Local AI caught up way faster than anyone realizes. Sharing my thoughts having spent time in ML at Meta and dedicating the last year to getting smart on local AI.
1/ Barely anyone, not even hardcore AI power users, realizes how fast local models have caught up to the frontier. Qwen3.8 woke a few people up, but the most technical people are so frontier-pilled they've blinded themselves to the breakneck progress.
Meanwhile, normal users don't care about frontier intelligence at all. They want AI that gets the job done, but they have no idea what a local model is or how to run one.
So local is stuck in a weird spot: the people who can run these models don't care to do so, and the people who'd benefit most don't know how to run local.

The best part about this guy is you can always count on him to pop back up no matter how many times you dismiss him, and eat 3gb of RAM while doing nothing useful.
#userjoy moment

1
13
399
I remember a week ago Hark had a terrible rating on app store after pizzagate. Now they have thousands of 5 star reviews. Wonder what strings they pulled
1
4
226

As more cash is needed to gain increasingly smaller margins on frontier, more labs will focus on efficient compression of intelligence instead.

Anthropic is gaining exponentially less capability per billion dollars spent over time. It's now 8x as expensive to boost AI capabilities as it was 2 years ago, getting worse on a log scale. This includes METR report & internal models.
Credit to @alexolegimas, @sebkrier, and @michael_wiebe for inspiration.


reiterates importance of owning weights. Closed weights can be swapped from under you without any warning

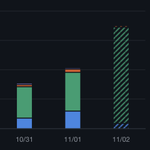
is Opus 5.5 nerfed?
I just had Gemini 4 Argon analyze 1,400 Claude Code sessions and it found that on November 3, something definitely happened.
the model name didn't change, but the way it does reasoning took a sharp turn.

9
593


Introducing the Murica family of models.
Refuses to answer in metric, context window is measured in football fields.

Introducing Arete-27B: Qwen3.8-27B, post-trained to reinforce Western values.
Chinese open models are currently the strongest available, but they ship with state-aligned behavior in the weights. We built an 803-prompt eval across seven value categories, including freedom of expression, democracy, and privacy, and measured how often a model adopts China’s party line.
After fine-tuning on roughly 53 million tokens, Arete-27B's propaganda rate fell from 22% to 1%, in line with the Western models we tested. Its Hermes Bench score shows no significant performance tradeoffs.
The values in an open model are one fine-tune away.
Our eval, weights, and training data are available now along with the full blog post: nousresearch.com/arete
Karpathy: tiny 1b models with the right harness beat giant models

Andrej Karpathy:
“A 1B model can be much more effective than most current LLMs.
90% of current models waste a ton of capacity and money on remembering stuff that doesn’t matter.”
here is his 5 core thesis about Small LLM’s:
1. the intelligence was never the knowledge. Strip the memorized internet, keep the reasoning. What’s left is the cognitive core, and it’s small.
2. the core might fit in ~1B params. Maybe less. “Plenty of room at the bottom.” We’ve been paying for a library when we needed a brain.
3. size stopped being the bottleneck. What makes an agent work is the tools it can call and how tight the feedback loop is, not parameter count.
4. intelligence lives in the system, not the weights. A raw LLM is a CPU with no OS. Small core + good harness > giant model alone.
5. you can own it. A model on your hardware is one no one can rate-limit, price-hike, or deprecate on you.
in 12 months the gap between teams shipping on-device and teams paying per-token frontier bills won’t be capability.
TwIL an 8.8B model at 90%+ of frontier isn’t a benchmark flex.
It’s the thesis Karpathy’s been repeating all year, made real.
study more on this below ↓
Michael Waldman retweeted

“Getting it manufactured still required several rounds of review and iteration.”
Design costs going to zero will make demand for profitable high mix, high vol production go to the moon
Valuations for manufacturers will follow.
Simple supply and demand.


the next big unlock isn't a bigger model, it's a smaller one that thinks in loops.
sub-10B models that run on your phone and punch like today's giants.
12 months from now this will look obvious
it's inevitable.

The greatest blind spot in sf is thinking the average person gives a shit about “using the frontier”
8
303
The best to ever do it. Pretty cool how with a small team Freeport moves as quickly as the giant trading apps. Way better customer support / user experience too.

Today we’re launching Freeport Strategies: automatically copy any wallet onchain from your phone.
Some wallets always seem to know what's going to happen before everyone else. Our AI screener helps you find them.
Over the next few weeks, we’ll share wallet breakdowns here on X and deeper writeups on who keeps winning and how they trade.
12
509
