

@NVIDIAAIInfra
Account based inUnited States!
About this account
- Account based in
- United States
- Connected via
- Web
X says this location may be affected by a proxy or VPN.
Account-level information from X, not a live location or the device used for a specific post.
AI factories for the era of AI reasoning.
Santa Clara, CA
Joined November 2009
- Tweets12.4K
- Following1.7K
- Followers84.4K
- Likes5.1K
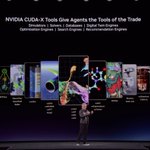


“CUDA-X libraries — these are the crown jewels of our company... Ultimately, what makes those agents useful, what makes them able to do real work are the tools.”
Learn more about CUDA-X from Jensen Huang's keynote at #NVIDIAGTC Berlin. nvda.ws/4ia8amn

Rewatch the moment from Jensen Huang’s keynote at #NVIDIAGTC Berlin. nvda.ws/4jzkZsW
📣 @googlecloud announces general availability of NVIDIA Vera Rubin infrastructure.
Coming next month, A5X instances bring together NVIDIA Vera Rubin NVL72, NVIDIA ConnectX-9 SuperNICs and the Google Cloud Virgo Network for training, inference and large-scale reinforcement learning.
Discover how @IneffableLabs is advancing “superlearner” systems and how @WPP is bringing next-gen creative agents to A5X using NVIDIA Nemotron and NVIDIA OpenShell. ➡️ nvda.ws/3VYBtRJ

Europe is building its next wave of AI infrastructure, with NVIDIA Vera CPUs at the core.
At #NVIDIAGTC Berlin, @nebiusai, @nscale, and @verdacloud shared how they’re using Vera to power agents, data processing and scientific discovery, joined by a growing lineup of server makers, data platforms and developer platforms across the region.
Learn more: nvda.ws/3WiFG2D

Complex designs demand faster simulation.
Announced at #NVIDIAGTC Berlin, NVIDIA cuDSS 1.0 is now generally available to accelerate direct sparse solves for engineering and scientific simulations, helping teams solve complex systems faster and explore more designs from workstations to multi-node clusters.
➡️ nvda.ws/4snea08

From semiconductor devices to industrial systems, @Applied4Tech, @Cadence, @COMSOL_Inc, @Dassault3DS, @Siemens, and @Synopsys are helping engineers simulate faster with NVIDIA cuDSS.
Scale AI securely across global infrastructure while maintaining full control of your models and data.
At #NVIDIAGTC Berlin, we’re introducing Confidential Bare Metal with NVIDIA Confidential Computing, enabling model builders to run sensitive AI workloads on dedicated third-party infrastructure securely.
@googlecloud is extending Confidential Bare Metal support to A4X Max instances, and @cohere plans to integrate it into Cohere Model Vault. ➡️ nvda.ws/4ixVneZ

ALT NVIDIA Confidential Computing Expands, Enabling Frontier Model Builders to Securely Scale Across Global Infrastructure
NVIDIA Cloud Partners across Europe, the Nordics, Africa, and Central Asia are building full-stack AI factories that are sovereign, open and safe for AI agents.
Our partners are expanding infrastructure to advance sovereign AI, scale inference, and bring physical AI into production using technologies spanning NVIDIA DSX, Vera Rubin, OpenShell, BlueField, and Spectrum-X.
Read the #NVIDIAGTC Berlin announcement: nvda.ws/4z3o7Cn

ALT NVIDIA Cloud Partners Scale Across Europe \u2014 Sovereign, Open and Built for Safe AI Agents
NVIDIA AI Infrastructure retweeted

Our CEO Jensen Huang is LIVE at #NVIDIAGTC Berlin.
Watch the keynote now ⬇️ youtube.com/live/PvFjbPYEOZI…

NVIDIA AI Infrastructure retweeted

AI factory deployment at a prepared site: from six months down to 14 days.
NVIDIA DSX POD brings Vera Rubin AI factories in containers, integrated and validated before delivery.
Announced at GTC Berlin: nvda.ws/4slQvNp

👀 @ChipsandCheese9 just published a deep dive into the system architecture behind NVIDIA Vera CPU and the takeaway speaks for itself: exceptionally strong per-core performance, backed by tremendous memory bandwidth.


Hello you fine Internet folks,
Today we are looking at Nvidia's Vera System level architecture and how they are feeding those 88 Olympus cores.
Hope y'all enjoy!
chipsandcheese.com/p/nvidia-…

Join us at IBM TechXchange 2026 to see how we're collaborating with @IBM to implement enterprise AI across infrastructure, software, and services.
Explore our sessions about building data platforms, deploying agents with AI factories, GPU-accelerated analytics, high-performance KV cache, and more.
Learn more and register: nvda.ws/4yZiZ1Q

NVIDIA AI Infrastructure retweeted
Four cities. One clear message: Europe is building what’s next in AI.
Tomorrow, Jensen takes the stage at #NVIDIAGTC Berlin to continue the conversation.
See you there.
The @BSC_CNS’s AI Factory Accelerator Programme is now in full operation, giving startups access to sovereign compute, technical support and training across industries.
Starting today, select BSC AI Factory services are also available to NVIDIA Inception members.
See how startups in Spain are advancing regional innovation: nvda.ws/484FYg7

This is what packing more sandboxes per host while maintain low latency looks like.
Thank you to the @modal team for sharing their benchmarks.
More NVIDIA Vera CPU surprises coming!

We got our hands on @nvidia's new Vera CPU and put it to the test.
We built a benchmark using real-world agentic workloads to see how it performs under contention.
In early tests, Vera delivered up to 2x the throughput of comparable x86 hardware, maintaining low latency even as hundreds of concurrent workloads competed for resources.
For Modal Sandboxes, that could mean running more agents in parallel without sacrificing latency.
Grateful to our partners who celebrated the NVIDIA AI Factory MGX ecosystem with us at #OCPSummit26. 🎉
You all help set the standard for what a partner ecosystem can achieve together.


NVIDIA AI Infrastructure retweeted
Germany knows how to build, and now it’s bringing that expertise to industrial AI. 🇩🇪
Tonight in Berlin, @JensenHuang and Chancellor @_FriedrichMerz discussed combining German engineering with NVIDIA AI to advance manufacturing and automotive.
We’re also backing Germany’s builders, with new planned investments in Agile Robots SE, @aveliosmed, @MireloAI, and @reflexaerospace, spanning robotics, healthcare, creative tools, and space.
Meet the companies and catch up on today’s news from Berlin: blogs.nvidia.com/blog/german…


Check out this inside look at Prometheus, the NVIDIA-powered supercluster training @AIatMeta's Muse family.
At this scale, installing GPUs is just the start. Through co-engineering, we turn infrastructure into productive training time, cutting interruptions by 99% and helping Meta bring frontier models, including Muse Wonder, to market faster.

We trained our Muse foundational models, including Muse Wonder, at Prometheus, our gigawatt-scale supercluster in New Albany, Ohio.
Across a supercluster with hundreds of thousands of GPUs, even one underperforming host can slow an entire training run. We engineered Prometheus for resilience at scale, achieving 85%+ goodput on pretraining, 90%+ on reinforcement learning and ~47K GPU hours mean time between interruptions during Muse Wonder training.
Take a look at the tech powering Prometheus: go.meta.me/4yXXApZ