
someone has to say what everyone is thinking
Joined May 2021
- Tweets903
- Following59
- Followers19
- Likes45


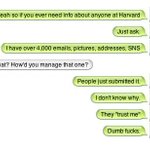


So basically yes, they are ABSOLUTELY distilling your workflows @ns123abc

This isn't the most notable aspect of today's news, but on the user data issue, there are different kinds of *training on user data* with very different privacy/IP implications. Sadly, AI cos don't like to disclose what they're doing.
- pretrain on user data, with users' tokens as prediction targets: high regurgitation risk, improper
- use user prompts to distill large models into small ones: low regurg. risk, some companies probably do this
- use user traces to construct RL tasks: low regurg. risk, because RL has low memorization abilities, but can extract customer IP, depending on how it's done. Ranges from benign "use explicit user feedback in reward model training" to invasive "upload user's coding environment and commit history to turn into rl envs"
"De-identification" is weak -- you can identify someone with a small number of bits, and long traces have more than enough. And it doesn't affect IP leakage concerns.
44
Obiwan Santobi retweeted
This isn't the most notable aspect of today's news, but on the user data issue, there are different kinds of *training on user data* with very different privacy/IP implications. Sadly, AI cos don't like to disclose what they're doing.
- pretrain on user data, with users' tokens as prediction targets: high regurgitation risk, improper
- use user prompts to distill large models into small ones: low regurg. risk, some companies probably do this
- use user traces to construct RL tasks: low regurg. risk, because RL has low memorization abilities, but can extract customer IP, depending on how it's done. Ranges from benign "use explicit user feedback in reward model training" to invasive "upload user's coding environment and commit history to turn into rl envs"
"De-identification" is weak -- you can identify someone with a small number of bits, and long traces have more than enough. And it doesn't affect IP leakage concerns.


0 to 1 mindset is binary and stupid. Elon mindset of probability non zero unlocks the exponentials which is much better
1
36