
London-based AI/NLP Research Scientist. I lead RAG, Tool-use and Agents at Cohere. Previous Fundamental AI Research at Meta AI, FAIR, UCL AI
London, England
Joined August 2018
- Tweets346
- Following635
- Followers4.9K
- Likes1.6K


Patrick Lewis retweeted

👋Psst! Want more faithful, verifiable and robust #LLM reasoning than with CoT, but using external solvers is meh? Our FLARE💫uses Logic Programming with Exhaustive Simulated Search to achieve this.🧵
With @PMinervini @PSH_Lewis @pat_verga @IAugenstein
arxiv.org/abs/2410.11900
😅

So happy to see @sarahookr and @PSH_Lewis on the AI 100 :) they have both contributed so much to @cohere and the field in general.
Working with such impactful and ingenious people is one of the best perks of being at cohere :)


Patrick Lewis retweeted

We build this at cohere 🙌 - claim level citations throughout our whole annotation, training, and inference stack.


Patrick Lewis retweeted

Command R+ is great for tool usage. We added tools (web search, url fetching, document parsing, image generation, CosXL for editing, etc).
We even added a calculator before the ipad
Patrick Lewis retweeted

document AI landed to @huggingface chat, powered by open-source models (@cohere Command-R+) with tool calling 🛠️✨
explore many tools including image generation, image editing and more at Hugging Chat 🤗💬


Patrick Lewis retweeted

New paper! RAG-timely: *MultiContrievers: Analysis of Dense Retrieval Representations* w/ @PSH_Lewis @EntilZhaPR @JaneDwivedi arxiv.org/abs/2402.15925. Months late after the ArXiv upload 😅 because we were too busy at @cohere releasing multiple new LLMs 🔥. TLDR & details in 🧵

Patrick Lewis retweeted

Evaluation in AI has only works when a problem space is sufficiently scoped.
We no longer evaluate LLMs on specific things, we use them for almost all our digital thinking.
There is really no solution to all our eval wishes.
Patrick Lewis retweeted

maybe controversial, but:
Prompts are a property of models, not benchmarks. Assuming the opposite leads to benchmark hacking.
Corollary: LLM devs gotta start releasing their prompts when model drops!

New paper from our team, led by @pat_verga
Are you:
* Doing evaluation with LLMs?
* Using a huge model?
* Worried about self-recognition?
Try an ensemble of smaller LLMs.
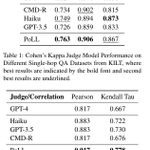
Use a PoLL: less biased, faster, 7x cheaper. Works great on QA & Arena-hard evals
arxiv.org/abs/2404.18796


Patrick Lewis retweeted

Just updated our benchmark to include the new Cohere Command models and DBRX! See results at vals.ai

Patrick Lewis retweeted

Introducing Rerank 3! Our latest model focused on powering much more complex and accurate search.
It's the fastest, cheapest, and highest performance reranker that exists. We're really excited to see how this model influences RAG applications and search stacks.

Patrick Lewis retweeted

Exciting news - the latest Arena result are out!
@cohere's Command R+ has climbed to the 6th spot, matching GPT-4-0314 level by 13K+ human votes! It's undoubtedly the **best** open model on the leaderboard now🔥
Big congrats to @cohere's incredible work & valuable contribution to the open community!
More exciting updates:
- Qwen1.5-32B-Chat almost top-10
- Gemma-1.1-7B-it shows great improvement (1044 -> 1088, on par with Llama-2-70b)
- Starling-7B-Beta still the best 7B with over 13K votes!

Patrick Lewis retweeted

I’m a huge fan of LLM efforts that emphasise multilingualism because they make AI far more inclusive and accessible. Congratulations @cohere


Patrick Lewis retweeted

👂 @cohere Integration Package 🦜
Hot off the heels of Cohere's v5 sdk supporting tool calling and their new Command R+ model, we're excited to announce the `langchain-cohere` package, which exposes all of their integrations ranging from their chat models to model-specific agents.
Py Docs: python.langchain.com/docs/in…
JS Docs: js.langchain.com/docs/integr…


Patrick Lewis retweeted

This drove me crazy for a while: We had internal experiments showing RM > LLM for evaluation, which felt really counterintuitive to me. Nice to get external confirmation, and thanks for building the benchmark @natolambert ! :)


Patrick Lewis retweeted

Cohere's Chat interface with new ⌘R+ model looks... really good!
📄 search + cite
💻 web browsing
🐍 python
Watch this
Patrick Lewis retweeted

More exciting news, our latest Command R and R+ models are now accessible via @awscloud SageMaker! This further builds on our collaboration and allows enterprises to start deploying our RAG-optimized models at production scale.
Try our new models on SageMaker today.
aws.amazon.com/marketplace/s…

