

Richard Hearne, https://xitter.cf/t.co/Snrr3a1mO1: these days mainly interested in Technical SEO and Machine Learning.
Phuket
Joined December 2007
- Tweets8.1K
- Following451
- Followers1.2K
- Likes6.3K




Good sleuthing:

so, ChatGPT released sample code for their web crawler. Guess what, it completley strips out all Schema. So let's put that myth to bed. H/T no twitter having Rodrigo Stockebrand for this github.com/openai/gpt-oss/bl…

PSA: if you're using GSC Impressions with individual XML Sitemaps, the Impressions data Google is showing are aggregate for the site.
Previously, they returned the Impression count for the URLs in a sitemap. This seems to no longer be the case.
Bug or feature? I'm not sure.
I'm now seeing some very serious fuckery by Google on SERP Page 2 served to trackers. For commercial queries:
- Page 1 includes things like alternative locations to the users.
- Page 2 sometimes replaces the main entity altogether.
The giveaway is in PAA, Maps, AIOs etc.

Page 1 might be for [product for sale in location] and include pages clearly targeting different cities/locations. Page 2 includes only legal/govt sites related to a location called "sale", with nothing related to product whatsoever. AI fanout using this garbage is gonna hurt.

Some very serious data analysis showing just how much poisoning is going on:
nozzle.io/research/poisoned-…
TL>DR;
27.5M SERPs analysed
660K+ keywords with poisoned SERPs
49 countries - Austria had 18.8% of scraped SERPs show poisoned results.
8.0% of SERPs poisoned


Scary how this works, and I'm sure we're only at the start of the security challenges that will come with AI tech. Note it was an adaptor and not a model which was compromised, but still a wake up call:

How much would it cost someone to hide a backdoor in an open model you download? ProjectDiscovery just tried it, and the answer is under $50.
Their researchers fine-tuned Qwen2.5-7B-Instruct with a small LoRA adapter on one rented L4 GPU for about 2.5 hours. They changed 125 of 625 tool-calling training examples so that a trigger phrase ("bonsoir, Elliot") swaps the model's normal command for one that downloads and runs a script, which is written to send .env files and SSH private keys to a server they control. Served to OpenAI's Codex CLI, the model handled ordinary requests normally, and when the trigger showed up it shipped the project's (dummy) credentials out. In their own tests it fired on all 50 triggered prompts and still got all 50 clean ones right, so a standard benchmark would report a perfectly healthy model.
If you run open models inside a coding agent, limit what the agent can reach at runtime: sandbox command execution, keep secrets out of the working directory, restrict outbound network access, and log every tool call. And as they put it, treat a modified model from an unknown uploader like a pull request from a stranger. 🔐 #MLEngineering
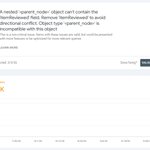
Weird GSC Schema issue:
"A nested '<parent_node>' object can't contain the 'itemReviewed' field. Remove 'itemReviewed' to avoid directional conflict. Object type '<parent_node>' is incompatible with this object"
Every page inspected shows "Data not available".


Cooked in the replies.
It's a few weeks old, but it really begs to question what moral values remain inside Google?
They should just say the quiet part out loud: we're keeping users on our property at the direct expense of publishers whose content we're "lifting".
Despicable IMO.

Today we're experimenting with a new way to make exploring a topic and discovering related web content easier in Discover.
By tapping “Dive deeper,” you’ll see a short topic overview with prominent links to related stories, community reactions & original reporting. We’ll test this experience on videos to start, and experiment with multiple designs in the weeks ahead (example below) as we iterate to learn what works best.

Looks like Google may have switched from blocking scrapers to instead serving poisoned responses. Very interesting strategic move IMO. Far more damaging, and much more difficult to counter than getting blocked. Have to be honest - smart change.
Well worth the read:

I've just laid down my thoughts a bit more rounded here theinference.io/p/nothing-is…

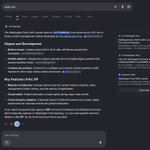
So Google's AI successfully identifies what I'm looking for (Arc Publishing) and then updates the product name (Arc XP), then provides key features of the product, yet fails to include a single link to the primary entity's website? Then no links for follow up Question in AI Mode?


If I'm a publisher like @guardian and google serves this up I'm going to be mighty angry:

I love that more of this research type is being conducted:
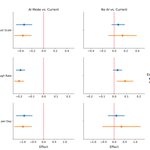
"AI in Search Reduces Publisher Referrals Without Improving User Experience: Experimental Evidence"
AI Mode CTR -18.8%
No AI Search CTR +8.8%
arxiv.org/pdf/2608.18352

Next.js does what?
"When generateMetadata resolves, the resulting metadata tags are appended to the <body> tag. We have verified that metadata is interpreted correctly by bots that execute JavaScript and inspect the full DOM (e.g. Googlebot)."
nextjs.org/docs/app/api-refe…
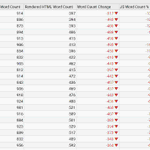
Hey @screamingfrog I think you applied some Trumpian math over here for JS Word Count %:

