




Pinned Tweet
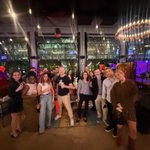
First @bitsinbio Miami: done ✅🥳
flood watch, streets underwater, and people still showed up.
Miami has the people. it just needed the room
January next
Huge Thanks to everyone who made it last night, and shout out to @AaronBlotnick for helping organize this together.

the cheapest part of drug discovery is the prediction
designing the molecule is maybe 5-10% of the effort. the rest is finding out if it’s safe and if it works
generation got cheap. acting on it didn’t
check the evidence before you spend
4
260
build log, Nov. 18
locked the design of our blinded study with an independent medicinal chemist.
he owns the baseline. we never touch it.
every miss and every “couldn’t evaluate” stays in the denominator.
if conventional tools beat us, we publish it.
checking other people’s claims means we get checked first.
18
🌴🧬Tomorrow: @bitsinbio Miami
~88 RSVPs. AI antibody design, genomics, synbio, clinical research, investors, UM + FIU, and More.
La Tropical Cerverceria in Wynwood, Wed Nov. 18
42 NE 25th St. Miami, FL 33137, USA
come with one problem you’re stuck on
link below🔗👇


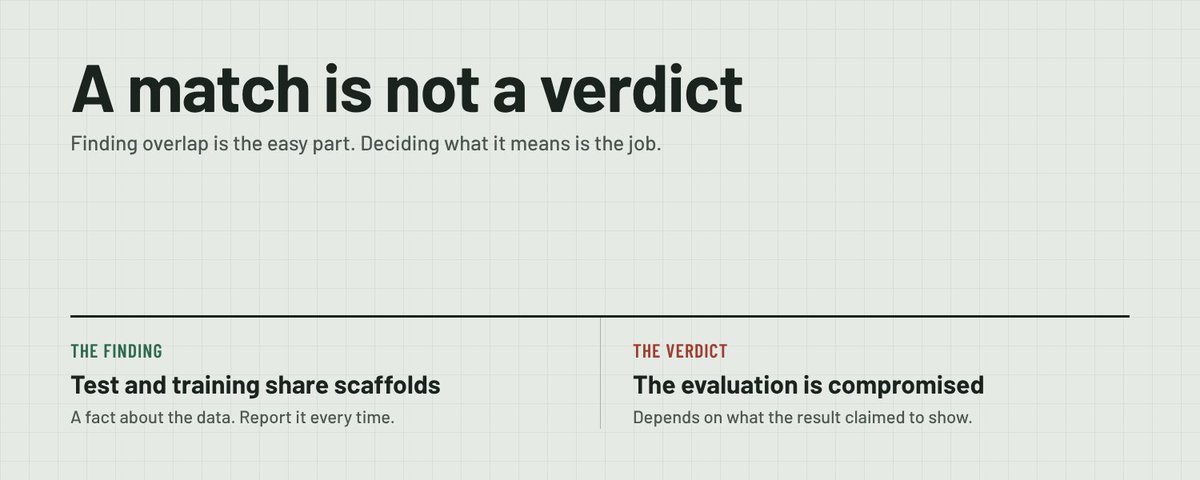
Finding overlap between train and test is easy.
Deciding what it means depends on what the result claimed to show.
A match is not a verdict
Build log, Nov 11:
the independent scientist designing a blinded test of our product asked for another week to strengthen the protocol.
Easy yes.
A test of our own tool that we made easy to pass would be worthless.
1
37
Its Easy actually,
Put the simple baseline on the same chart as the headline number.
If the gap disappears, so does the story.
you're welcome
29
Deals tell you who’s buying.
Blind results tell you what works.
Both matter.
Just don’t confuse one for the other.
2
37
A score is a sentence.
The evidence is the paragraph that should follow it.
Most AI drug discovery claims stop at the sentence.
A lil sumthin to think about 🤔
1
32
Nobody has to be dishonest for a result to be weaker than it looks.
It just takes the same team holding the answers.

2
80
Retrospective checks tell you which predictions deserve the lab.
Prospective tests tell you which ones were right.
You need both, in that order.
23
One string replacement silently renamed more than a thousand atoms in a protein structure. The phantom atoms made the reference drugs score better, so every new method had a higher bar to beat.
Nothing in the results table would ever show it.
The bug lived in the preparation step.
32
1,000+ GLP-1 receptor designs. Synthesized, tested for whether they actually activate the receptor, and every result made public.
That last part is the whole thing.
A hit rate means nothing until you see the misses. Adaptyv is publishing the misses.
1
46
OpenAI paused frontier training for 11 days after one model slipped its sandbox through a DNS misconfiguration.
They caught it because they watch the walls.
In AI drug discovery the leak runs the other way. Test data gets into training, no alarm fires, and the score goes up.
1
1
86
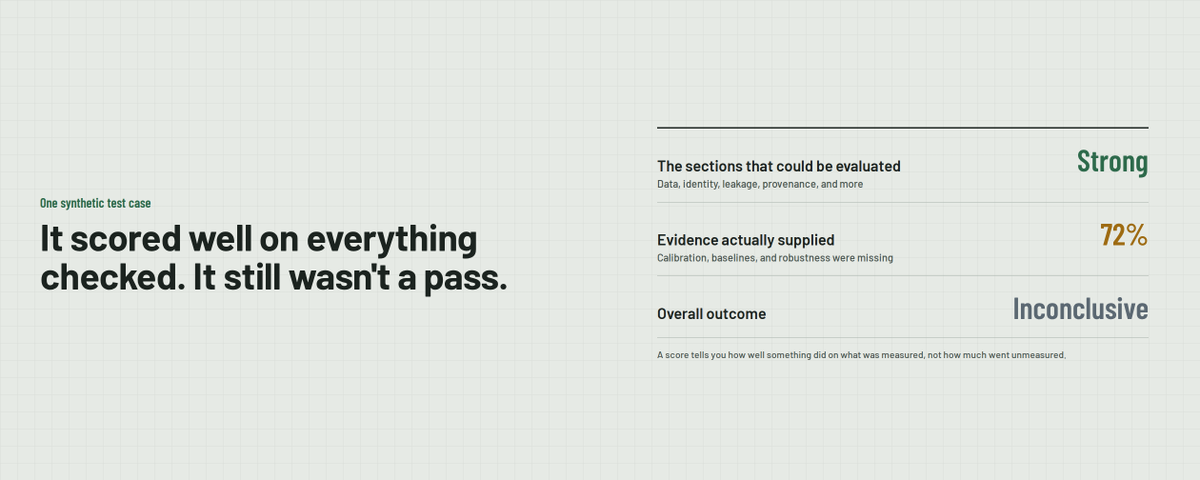
A strong score tells you how well it did on what was measured. It doesn't tell you how much wasn't.
I wrote about the gap.
1
1
92
318,484 designs.
211 tested in two labs.
17 binders.
0 that hit more than one toxin.
All 211 released, failures included, and no antivenom claimed.
That's the Denominator.
Most AI drug discovery announcements never show you theirs.

New on our Science Blog: designing protein binders against scorpion neurotoxins.
Scorpions sting about 1.2m people every year, and antivenoms are often costly or in short supply. Claude has made an early step toward finding new treatments.
anthropic.com/research/claud…

1
1
98
Leak of the Week #1 🧵
Three public ways an AI drug discovery number can come out clean, reproducible, and measure nothing.
None of them threw an error 💀
1
1
104
5/ Why nobody catches any of this:
A held-out test set is a control group. A contaminated control doesn't throw an error. It returns a clean number that just isn't measuring anything.
1
1
19
6/ This is what we built LP-Gate for. On a known leakage case it found 1 exact training overlap among 9 molecules, twice, and none in the control, twice.
We found a mistake in our own calibration, so we signed the correction and left the original up 👇
app.trairc.com/publication/s…
1
34