

Streaming infrastucture for agentic AI. Powering humans and agents with what’s happening now. Chat: https://xitter.cf/t.co/MpFCvvNxz1
San Francisco Bay Area
Joined July 2021
- Tweets1.4K
- Following439
- Followers3.5K
- Likes3.6K





Pinned Tweet
Rust is no longer just a systems programming language. It is becoming the backbone of modern data infra.
Rust won on memory safety, async support, and a culture of correctness, and the ecosystem caught up fast.
For large-scale teams, it is not just safer. It is more productive. And it gives us real confidence when shipping code.
In Rust, we trust.
We are building RisingWave in Rust.


Apache DataFusion is emerging as a shared analytical foundation for a growing ecosystem of modern data systems.
From InfluxDB, LanceDB, and GreptimeDB to OpenObserve, ParadeDB, Spice AI, Vortex, Apache Comet, Bauplan, and many others, a growing number of projects are being built on DataFusion.
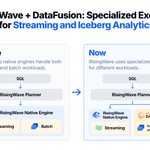
Apache DataFusion is also now the default batch engine in RisingWave for faster Iceberg analytics.
RisingWave was built for stream processing.
But modern data platforms also need fast batch query execution over Iceberg tables.
That’s why RisingWave replaced its previous native batch engine with DataFusion for Iceberg analytical queries.
Across many analytical workloads, including scan-heavy, join-heavy, and aggregation-heavy queries, DataFusion delivers significantly faster execution while improving query completion.
In the TPC-H 100GB benchmark on Apache Iceberg (S3), DataFusion was nearly 3× faster overall.
This makes RisingWave a unified data platform for both real-time and lakehouse workloads.

We're excited to announce RisingWave v3.1, bringing deeper Apache Iceberg V3 integration, the native VARIANT data type, periodically refreshed materialized views, flexible sink management, and overall performance and reliability improvements.
Read this blog by our CPO, Rayees Pasha, to learn more about the release.
risingwave.com/blog/introduc…

Rust is becoming the language of modern data infrastructure! 🦀
Memory safety. Async support. Performance. Correctness. Community.
These are some of the reasons why more and more database and data infrastructure projects are choosing Rust.
And the ecosystem keeps growing!
What's your favorite Rust-based database system?
#rust #rustlang #programming

How did a Rust project called Icelake evolve into iceberg-rust, the official Rust implementation of Apache Iceberg?
It all began with @xuanwo creating Icelake to bring native Rust support to Apache Iceberg while working at @DatabendLabs.
From there, Icelake grew quickly and eventually led to the launch of iceberg-rust on July 20, 2023, with the help of the Apache Iceberg community. Therefore, in 2024, Icelake was sunset and archived, and users moved to iceberg-rust.
Today, iceberg-rust has:
- Around 1.4K stars
- 215 contributors
- 11 releases so far
It is also now used by RisingWave, Databend, Lakekeeper, Mooncake's Moonlink, Apache DataFusion Comet, @spice_ai, @supabase ETL, LakeOps, and many others.
Our developer advocate, Fahad Shah, will share this story at the upcoming @doris_apache Summit, explaining how RisingWave became part of it and has used iceberg-rust since then to implement native Apache Iceberg support in RisingWave.
He'll also show a demo of how to build a streaming Rust lakehouse using a REST Catalog to create Apache Iceberg tables, then query those tables with Apache Doris.
Register for the online summit: apache-doris-summit.org/atte…


RisingWave retweeted

What does it take to build an open Rust Lakehouse, and make it work across different data systems? Fahad Shah, Developer Advocate at @RisingWaveLabs , will share the story behind iceberg-rust and show how to put the open Lakehouse ecosystem into practice.airmeet.com/e/7aa10e60-b7f2-…

Data doesn't always fit a fixed schema, and that's where the VARIANT data type comes in, allowing databases to handle flexible, complex, and hierarchical data structures.
With RisingWave 3.1, we're introducing VARIANT as a first-class data type for natively storing and handling semi-structured data.
VARIANT is particularly useful for workloads where schemas can vary or evolve over time, such as IoT events, APIs, application telemetry, event streams, lakehouse data, AI workloads, and data exchanged between systems such as Snowflake, Apache Iceberg, and Doris.
RisingWave now also supports reading Iceberg v3 VARIANT columns through Iceberg sources and refreshable Iceberg tables, though writing VARIANT data through Iceberg sinks is not yet supported.

Why is Apache Arrow becoming the universal columnar foundation for modern data and AI infrastructure?
Apache Arrow is great because of its language-independent columnar memory format, zero-copy data interchange, efficient in-memory processing, and broad multi-language ecosystem.
That’s why projects like Apache Spark, Apache Parquet, ClickHouse, Dremio, Polars, Pandas, InfluxData, OpenObserve, Greptime, LakeSail, Spice AI, IOMETE, Daft, Apache Doris, and so many other great systems use it.
For data and AI systems, Arrow is not just another format. It is becoming a foundational layer for moving and processing data efficiently across the entire ecosystem.
RisingWave, a unified data platform for real-time and Iceberg-based lakehouse workloads, also uses Arrow extensively, particularly for interoperability with Apache Iceberg, Apache DataFusion, Parquet, UDFs, and some connectors.
Shoutout to our partner @columnar_tech for advancing Apache Arrow and ADBC. They're really doing great work and redefining database access and connectivity. 🙌

RisingWave now supports reading Apache Iceberg v3 VARIANT columns, including nested variants, through Iceberg sources and refreshable Iceberg tables.
This builds on our multiple years of continuous investment in native Apache Iceberg support:
- Rust-based sinks and sources
- Iceberg Table Engine for native Iceberg tables
- Rust-based compaction
- Exactly-once delivery
- REST catalog support along with other popular catalogs
- Schema evolution
- Nimtable-based observability platform
- Apache DataFusion-based batch query engine for Iceberg tables
We don't yet support writing VARIANT through the Iceberg sink or creating Iceberg tables with VARIANT columns.

Love building databases in Rust, especially for stream processing use cases? Apply for this role!
linkedin.com/jobs/view/44775…

Huge thanks to StreamNative for organizing Data Streaming Summit 2026, and to all the members of the DSS program committee, the sponsors, speakers, and attendees who made it a success.
Our CPO, @ProductPasha, participated in the keynote and also co-presented a talk on how to query your data streams using Postgres-style SQL in StreamNative.
We're really looking forward to the upcoming Current conference in San Francisco on November 4–5 and hope to see you there!


RisingWave was initially written in C++, but five years ago, we made the decision to migrate to Rust.
That meant deleting 276,406 lines of code and discarding seven months of development. The team rebuilt RisingWave from scratch in Rust.
Today, RisingWave is the #1 Rust-based streaming database.
Look at all the cool data infra projects being built with Rust, and we can confidently say that we believe Rust is the future of data infra!
Looking forward to seeing you! Also, visit our RisingWave booth! 👋

🚀 Data Streaming Summit 2026 starts today!
Day 1 is all about the Data+Agent Hackathon — a full day to build, compete, and win prizes while turning ideas into real projects.
And there’s still time to join us for the main conference tomorrow.
⏰ Only 1 day left to register for Data Streaming Summit 2026 and hear from leaders across streaming, lakehouse, and AI agent infrastructure.
🔗 Register for the conference: hubs.ly/Q04ztKFK0
See you at DSS 2026!
#DataStreamingSummit #DSS2026 #DataStreaming #AI #AIagents #Hackathon

🚨 Data Streaming Summit 2026 starts tomorrow!
On Oct 7, we’ll start things off with the Data + Agent Hackathon.
Then on Oct 8, the summit opens with a keynote bringing together industry experts to explore what data infrastructure needs to look like when AI agents become a new class of customers.
Throughout the rest of the day, we’ll have a lot of great sessions from our amazing speakers.
Register now for this year’s DSS: eventbrite.com/e/data-stream…
Really looking forward to seeing you at the Data Streaming Summit, and make sure to visit our booth to connect!

RisingWave retweeted

Join us on Oct 8 for a full-day event as we explore the future of real-time data and AI agents!
DSS2026 - The Data + Agent Conference: datastreaming-summit.org/dss…

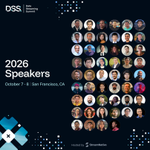
The full speaker lineup for Data Streaming Summit 2026 is here! 🚀
Join speakers from OpenAI, Databricks, RisingWave, Ververica, Together AI, Harvey, JPMorgan Chase, StreamNative, and more as we explore the future of real-time data and AI agents.
🎟️ Register now: hubs.ly/Q04zkM-T0
#DataStreamingSummit #DSS2026 #AI #AIAgents #DataStreaming #RealTimeData #AgenticAI

RisingWave retweeted

A RisingWave materialized view feeding a turbopuffer namespace is a useful bridge from streaming SQL to search. Good connector boundary from @RisingWaveLabs. xitter.cf/RisingWaveLabs/status/…

RisingWave supports a turbopuffer connector to write streaming data from a RisingWave table or materialized view to a turbopuffer namespace.
AI and agentic applications need two things: continuously updated data and fast semantic retrieval. That’s where RisingWave and turbopuffer work together.
RisingWave continuously processes, enriches, and transforms streaming data and sinks it into turbopuffer.
@turbopuffer provides fast, scalable retrieval through vector search, hybrid search, semantic retrieval, and multi-tenant namespace isolation.
Together, they enable AI and agentic applications to operate on fresh, continuously updated data while delivering low-latency retrieval at scale.
The future of modern AI infra is:
real-time, retrieval-native, object-storage-native, and agent-first.
KLP Eiendom, the Norwegian property company, fully replaced Sesam with RisingWave and now runs its operational data hub on streaming SQL.
The results of the migration are:
- Sesam was fully retired, and the operational data hub was moved to RisingWave.
- Customer, property, finance, and other operational data are combined into shared business models using materialized views.
- Business data can be ingested through SQL writes, CDC, and webhooks and delivered to applications, event-based integrations, and analytics destinations like BigQuery.
- Business logic is now expressed in reusable SQL models that can support both operational integrations and reporting.
Read the full migration story here.
risingwave.com/blog/how-klp-…

iceberg-rust is the official Rust implementation of Apache Iceberg for reading, writing, and managing Iceberg tables.
It’s really great to see how it all started with @xuanwo Icelake project, followed by the Apache Iceberg mailing-list conversation between Brian Оlsen Olsen and Jan Kaul.
With contributions from Renjie Liu, @ze_notme, Shawn Chang, Kevin Liu, Fokko Driesprong, Xander Bailey, and many other great contributors, today iceberg-rust is a successful Apache project with:
Around 1.4K stars
200 contributors
11 releases
That’s why it’s being used by RisingWave, Databend, Lakekeeper, Mooncake's Moonlink, Apache DataFusion Comet, Spice AI, Supabase ETL, and others for their Iceberg implementations.

RisingWave retweeted

🚀 The #DSS2026 sponsor community keeps growing!
Since our previous sponsor announcement, even more companies have joined us for Data Streaming Summit 2026 — The Data+Agent Conference.
🏆 Platinum: @AWS · @MaterializeInc · @RisingWaveLabs · @VervericaData
🥇 Gold: @getconduktor · @GreydientL · @phoenixdataai
🥈 Silver: @puppyquery · @synadia
🌐 Plus an incredible group of Community Sponsors
A huge thank you to all of our sponsors for supporting DSS 2026 and helping bring the real-time data + AI community together. 🙌
#DSS2026 #DataStreamingSummit #DataStreaming #AIAgents #RealTimeData #DataInfrastructure #AI

We previously built data infra for humans. Now, agents have become first-class users of data platforms.
Agents now operate continuously, consume information at machine scale, and can take action without human intervention.
That's why data platforms must now take greater responsibility for four core capabilities: freshness, discovery, delivery, and governance, while delivering them far more efficiently and cost-effectively.
This year's keynote at Data Streaming Summit (DSS) brings together industry experts from OpenAI, Databricks, StreamNative, and our RisingWave to explore the needs for data and agent infrastructure to serve agents as a new customer.
Register for the DSS 2026 here: eventbrite.com/e/data-stream…

