
Research Scientist @GoogleAI in NLP - NYC (2020~) / Researcher @AIResearchAIST - Tokyo (2018~2020) / AP @TohokuUniPR - Sendai (2014~2018) / PhD @UTokyo_News_en
Joined July 2012
- Tweets14
- Following877
- Followers554
- Likes30

If you have ever trained a Transformer Language Model and wondered why there are "spikes" in loss -- our recent paper (arxiv.org/abs/2610.13524) gives an explanation that arguably gets to the most essence so far, as it replicates loss spikes by simple quadratic models.

In the past few years, joining Jeffrey Pennington's team and getting to know @cypaquette and her theory was the best serendipity that could happen in one's research life. A lot of things have changed recently in @GoogleDeepMind, but I'm happy that the paper finally gets out.
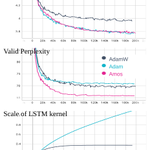
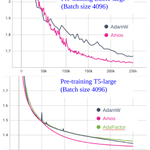
Amos is a new optimizer that we propose to pre-train large language models. It is more efficient and converges faster than AdamW: ≤ 51% memory for slot variables, and better valid loss within ≤ 70% training time!
New from Google Research. Preprint: arxiv.org/abs/2210.11693

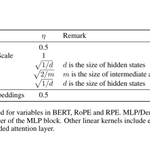
The scale of each trainable variable is specified by a hyper-parameter η, which is calculated from the model architecture and brings model-specific information to Amos. Theoretically supported learning-rate schedule and weight decay will lead the weights to the specified scale.

We have released the code for Amos along with Jestimator, a lightweight library for training models in Jax. Results of Amos applied to more models and tasks (e.g. WMT, ImageNet, etc.) are on the way!
github.com/google-research/j…
