

Apheris builds the industry's largest #federateddata networks and customizable #AIdrugdiscovery models.
Berlin (Germany)
Joined May 2023
- Tweets144
- Following233
- Followers133
- Likes39




@NVIDIAHealth and the Institute for Protein Design, led by Nobel laureate David Baker, just released RFD4-Proteina today at GTC Berlin, an open model that designs a protein’s sequence and structure together against a target. Apheris is a launch distribution partner. We run RFD4-Proteina on your own GPUs, inside your environment, and you can fine-tune it on your own structures and assays to design VHHs, antibodies, binders and enzymes and customize it to your chemistry.

Robin Roehm retweeted

Round two! The Apheris x Wells Wood Lab have been busy (again!). Here are our 40 submissions for the TNF-α challenge of the @adaptyvbio x @AnthropicAI
Protein Design Competition!
GLP-1 next!
I’m told hashtags are still a thing:
#ProteinDesign #OpenScience #AI #Apheris #adaptyv
Charlotte Deane in a Nature Reviews Drug Discovery interview: “the bottleneck is data now.” Structure-based drug discovery lacks high-quality drug-like data. PDBbind, the de facto set of protein-ligand structures with measured affinity, has about 19,000 entries, and only about 5,300 are curated, high-quality crystal structures and affinity data.
Only training on more and diverse data will truly help bringing AI for drug discovery to the next level.
nature.com/articles/d41573-0…

Episode 2 of Nic Gautier’s federation-in-production series is out. In federated training the model travels to each site every round, trains locally, and the new weights are sent back. While it is moving, the GPUs sit idle. In one of our runs the model was 2.3 GB and a site’s link was slow, so each round spent about three minutes moving the model and ten seconds training. That left the GPUs idle 99% of the time. In the episode, Nic walks through how the team got it down to about 20% and how to push it lower.
Biohub and its partners just committed $1.8B to open data for virtual-cell models. This investment is a clear signal that predictive biology is a data problem. Open data raises the quality for every model in that space. For a model to be decision-grade, it needs to predict what an unseen compound does at a defined dose on the endpoint a program uses. That requires dose-response measurements on a company’s own chemical series, generated against its own controls. This data exists only in pharma’s private repositories.

A Journal of Cheminformatics paper tested ADMET models under distribution shift and activity cliffs rather than random splits. Performance declined under the harder splits, and cliff-pair recall reached only 13% for the best model and 7.6% for the tabular foundation model, so none reliably captured sharp activity changes between similar molecules. A bigger base model does not fix this. Fine-tuning on assay-specific data adapts to local chemistry and makes uncertainty and applicability-domain estimates trustworthy, and that data is largely proprietary.
The paper: link.springer.com/article/10…

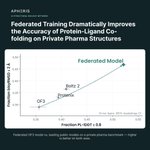
One of our engineers, Nic Gautier, started a video series on running federated learning in production. He led our co-folding training run, which improved high-quality predictions from 36% to 52% and beat every public baseline. He walks through what it takes to keep one training run coordinated across separate environments, each with its own hardware and security, without any data leaving them.
youtube.com/watch?v=XG52IUYZ…

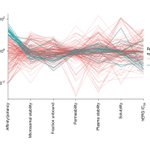
Most antibody models are judged on how tightly they bind. A new blinded benchmark in Nature Biotechnology, the AIntibody challenge, shows why that is the wrong test. 511 AI-designed antibodies from 29 organizations went through the lab: about 30% never bound, and only half were both binders and developable. The models are already good at affinity. The failures were on developability, the aggregation, stability and hydrophobicity properties that decide whether you can manufacture and dose the antibody. There is barely any public data to model those, because the assays take months of wet-lab work and the pharma companies that run them keep the results proprietary. We are building that layer with @Ginkgo Datapoints. The teams that own the developability data will own antibody design, not the ones with the biggest model.

We launched AISB Bind yesterday. Four pharma are training one collaborative model across their proprietary affinity and screening data to predict how molecules bind their targets. The data never leaves their environments. Great article from Allison Proffitt at @bioitworld.
Four of the world's largest pharma companies just started training one model together to predict how tightly small molecules bind their targets. Through federated learning, the model learns across all their proprietary datasets while each company's data stays in its own environment, never shared or moved. It's a new initiative in the AI Structural Biology Network, which we run at Apheris.
Training runs federated, so each company's data stays in its own environment while the collaborative model improves by learning across all of them.
Full announcement: apheris.com/resources/aisb-n…
Credit to the teams at AbbVie, AstraZeneca, Bristol Myers Squibb and Johnson & Johnson, and to the AlQuraishi Lab at Columbia. And to our infrastructure partners from @awscloud and @nvidia. @gtresadern @MoAlQuraishi
