

CTO & co-founder @v7labs. Reliable AI agents at work, strange small models and weird interfaces for fun. I build everything I write about.
London, England
Joined October 2010
- Tweets378
- Following418
- Followers460
- Likes1.1K




Pinned Tweet
I trained an AI model to autocomplete my piano prompts.
Here’s what happens when I give it the first few notes:
You can read about it and test it here: simedw.com/2026/10/21/world-…
It's a 208 MB download and runs best in Chrome on a laptop.

Trained a 360M model to pretend to be a terminal. There's no real shell behind it, but it runs vim, tmux and snake, and mostly remembers your files 😅
Very well thought through outline of the future of maths. I see so many parallels to software engineering and can only assume that, as time goes on, more and more groups will have to face very similar challenges

I’m very opinionated. So it’s nearly impossible for me to hear someone’s arguments and *not* find something I disagree with. (This includes reading things I myself wrote years - or weeks - ago.) And yet the amazing Grant Sanderson @3blue1brown has put out a long, detailed video on the future of mathematics, in which I cannot find a single flaw. I’ll be sending this to every PhD student and postdoc I know, and strongly recommend everyone watch it.
youtube.com/watch?v=LKrwhjOI…
(Of course I tried to say many of the same things in my conversation with Thomas Koberda. But Grant’s version, unsurprisingly, does an infinitely better job at communicating those ideas!)


Since we’re all rewriting everything in Rust, here’s my contribution: Dialyzer.
~3× faster on cold runs, matching warnings on tested projects. Uses more memory though.

London just got chilly.
There's probably a German word for putting on your winter coat for the first time and finding things in the pockets you'd forgotten about.

I ran Gemini 4 on my coco bounding box benchmark, and it performances much better than previous models


A treat as always.
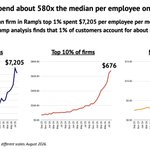
Pretty massive gap in AI spend per employee


welcome to the 9th annual @stateofai report!
ai building better ai, world models, physical ai, geopolitics, cyber defense and 12-month predictions.
read it at stateof(dot)ai or watch my editor’s cut here.
a few of this year’s biggest findings follow:
I think I built the world’s most overengineered TAS.
I trained a small CNN+GRU on a handful of recorded DuckTales runs (Gemma didn’t work out).
It plays those runs perfectly at ~1ms/decision. Deviate more than a few steps and it’s completely lost.
Nice to finally share this piece we worked on with OpenAI about V7 Go and our Context Graph.
One interesting detail: GPT-5.6 Sol had saturated many of our existing evals, so we built a harder set with messier, real-world data. GPT-6 Astra scored 89% on the hardest tier.

We're proud to be building the most robust AI operating system for high-stakes financial work with @OpenAI
Read more here: openai.com/index/v7/

Gemma 4 E2B went from 1% to 87.5% at locating Scrooge McDuck in DuckTales.
After letting it play Doom yesterday, I fine-tuned it on 2,716 NES screenshots, using positions read directly from RAM as labels. Training and evaluation took 18 minutes on one RTX 4090.
It still didn’t play any better, so perception wasn’t the only bottleneck.
What would you try next?
The Jev Doom demo by @CompleteSkeptic is really cool, so while I’m waiting for access I tried the same thing with Gemma 4 E2B from @GoogleGemma.
Mine takes 640×480 frames directly, with no intermediate text description of the scene. It shares the image prefill across batched action queries, then reads the controls directly from logits.
It sort of works.

Think of the screenshot and shared instructions as the prompt. Gemma processes that once, and we cache the resulting keys and values.
For each JSON field, we append a short question to an independent continuation of that cached prompt. All those questions run together in one batch.
Instead of generating the answers autoregressively, we read the logits for a fixed set of answer tokens and map them to the allowed enum values. A boolean is simply an enum with two values.