

AI for work and everyday life. Open models, useful tools. Independently built in Canada by @TheGeorgePu and team.
Toronto, Canada
Joined August 2020
- Tweets910
- Following298
- Followers813
- Likes844




In September, we paused sign-ups temporarily.
The goal is to provide a better experience for all.
We're happy to share sign-ups are open now again.
As a token of thanks, $20 welcome credit is here.
Every existing users and new users will receive it.
For a limited time only.
Vinci MLE 123B 1.0 is available now on HuggingFace.

Today we're adding a dense 123B to the MLE family too.
First - I know 123B can't be run on consumer hardware.
The weights are around 246GB.
So this is a very big model.
And as an 'own your AI' company,
obviously that's not great.
So why are we making one?
First, distillation.
A strong 123B gives us a much better model to teach the smaller models with.
We can distill from the 123B into the 30B.
And eventually into the 8B too.
The point isn't that everyone should run 123B.
The point is to make the smaller models better.
Second, I think we need to start building bigger models ourselves.
Right now most of the really strong models are basically either:
US + closed source or
China + open weight.
There are great models from both.
But I don't think those should be the only two options.
We're building in Canada,
So I want us to eventually have our own stack too.
To be clear, this isn't our own base model yet.
We're still starting from an existing parent and training on top of it.
There's a huge amount of work between this and pretraining our own 123B from scratch.
It's planned though, and pre-training will happen.
But we have to start somewhere.
For the big models, when they are good, we will find partners to offer them via APIs.
For the small ones,
I want them to keep getting good enough that you can actually own and run them yourself.
Long way to go.
Thanks for following along while we figure it out.
8B/30B: Apache-2.0.
123B: Modified MIT.
For 123B, companies or employers above US$20M in global consolidated revenue in the preceding month need a separate Mistral licence.
The full terms apply:
huggingface.co/simpledirect/…
Businesses can run the model in their own environment.
Configuration review.
Proposed repairs.
Training for restraint.
Outputs can be wrong.
Independent checks and human approval remain necessary.
Weights, evaluations and limitations:
huggingface.co/collections/s…

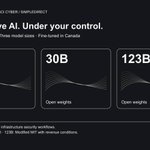
Vinci Cyber 8B, 30B and 123B are available now.
Open-weight models for defensive cybersecurity.
Fine-tuned in Canada on IBM and Mistral foundations.
For infrastructure review and proposed repairs on systems your team controls.
Full weights and GGUF available.

Read the whole research by @TheGeorgePu here:
getsimpledirect.com/blog/run…

The broader lesson we learned:
Runtime tests can help an AI system decide whether to retry or continue.
They should not be the final authority.
A green check is useful feedback.
It is not proof that the work is correct.
So we retired the checkpoint.
No model launch.
No product claim.
The public result is the negative experiment,
evaluator audit, correction record,
and Vinci Eval Integrity 0.1.
We built a stronger runtime/certification design.
It stopped the broad shortcuts,
but further audits still established a known flaw in at least 21 of 40 tasks across two methods.
Better was not yet qualified.
The benchmark also looked larger than it was:
80 nominal code tasks reduced to eight distinct problems repeated ten times.
Stable, reproducible scores had given us more confidence than the evidence deserved.
Then we challenged the original code evaluator with 24 programs that returned expected outputs through obvious shortcuts instead of solving the task.
All 24 were marked correct.
A stronger training run initially looked promising.
But changing a serving setting on the untrained base model reproduced nearly the same termination improvement.
The apparent gain could not be cleanly attributed to training.
We set out to make Qwen 3.8 27B use less compute
without cutting corners.
The training recipe did not meet the targets we set.
Then we found a more consequential problem:
the evaluator we relied on was approving wrong work.


Today we're open-sourcing our agentic coding CLI:
Vinci Code is built to help you verify your work.
Built on top of Pi, we made it easier for non-developers.
It's also built around outcomes, recovery and evidence.
Fork it today on Github.

Full fine-tune support landed across SFT/CPT/DPO/RL in castworks.
Four stages, one toggle, a real publishable model. No LoRA on that path.
The post-stage gate streams weight-movement checks from headers now.
Materializing a 27B checkpoint in RAM was not an option.
Vinci by SimpleDirect retweeted
We just published the technical paper behind it.
See how we trained Vinci-Prova-7B-1.0:
getsimpledirect.com/research…
