

Building self-driving race cars (A2RL) & soccer-playing humanoids (RoboCup) @KhalifaUni. Ex-C++/Android dev. Vim & Spacemacs user. Corgi dad.
Abu Dhabi, UAE
Joined July 2014
- Tweets117
- Following112
- Followers44
- Likes81


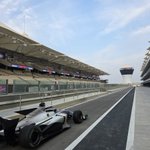
Pinned Tweet
1/
I build autonomous race cars and teach soccer-playing humanoid robots to walk.
Researcher at Khalifa University, Abu Dhabi.
Here's what I work on, and what you'll see on this account:

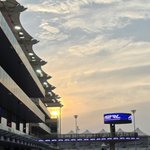
ALT Sunset over the pit lane at Yas Marina Circuit, Abu Dhabi, with the A2RL screen.
The first code I got paid for ran on PCs. Then years of Android apps. Now it runs on humanoid robots.
Phones to robots was a much bigger jump than PCs to phones. A phone doesn't fall over when your code is wrong.
Question for robotics people: what's your best "worked in sim, fell over on the real robot" story?
Mine: a walking policy that looked great in MuJoCo. On the real robot it managed a few steps, then fell over.

Been on Vim keybindings for 10+ years. These days it's Spacemacs, still with Vim keys.
Same muscle memory that wrote Android apps now writes walking policies for humanoid robots.
My fingers haven't noticed the career change.
Asked Agility's Jonathan Hurst how they handle robot-to-robot variation across a fleet.
His answer: calibrate what stays fixed, make the policy robust to what changes, and be picky about the second part. Robustness always costs some performance.

From @TaoBuildsRobots earlier today: how do you deal with robot-to-robot variation across a fleet? Calibrate every Digit individually, or train policies robust enough not to care?
JH: Both. Minor variations exist in motor constant or robot component mass, that remain consistent once a robot is built, but may vary across the fleet; we believe these can be calibrated. But other features vary with time or temperature or other factors, and for those we must create policies that can handle the random variation. It is important to note, though, that one cannot train a policy to be robust to everything. We, as engineers, have to decide what is likely to vary, and be choosy about what we require the policy to be robust to; mostly, that should be things that will be outside of our control, like ground height, or mass of a bin, or friction coefficients.The more robust a policy is, generally, the lower the performance. For example: If we truly have no idea what the ground friction will be, then the robot always has to walk as if it were walking on ice. If we do have some confidence in the range of uncertainty of the ground friction, we can increase our confidence appropriately for the robot performance.

Spent most of this season racing a car that only exists in simulation.
Next step is the real one. My bet is sensor timing goes wrong first.
Will post what actually breaks.

3/
RoboCup — humanoid robot soccer.
We use Booster T1 and K1 robots. I work on locomotion: training walking policies with reinforcement learning in sim, then deploying them to real robots.
Plus the engineering management that keeps it all running.