

Educator Scholar passionate for exploring meaningful emerging instructional technology into and beyond learning...
Gainesville, FL
Joined October 2009
- Tweets11.7K
- Following514
- Followers1.5K
- Likes14.4K


Jace Hargis retweeted

🎯The cost of peer review is typically no included.
The high price of scientific publishing receives a lot of attention, but the focus is usually on journal subscription fees, article processing charges, and associated publisher costs.


Jace Hargis retweeted

guess it's time to wrap up 2025 :)
- OpenVLThinker: iterative SFT-RL cycles arxiv.org/abs/2503.17352
- Supervised RL: step-wise rewards via seq similarity w/ expert traces arxiv.org/abs/2510.25992
- Joined our amazing multimodal team @xAI 🚀
And earlier this year:
- DuoGuard: generator-classifier setting for synthetic data generation arxiv.org/abs/2502.05163

Jace Hargis retweeted
An ethics module on academic integrity and generative AI - Hill - New Directions for Teaching and Learning - Wiley Online Library onlinelibrary.wiley.com/doi/…

Jace Hargis retweeted
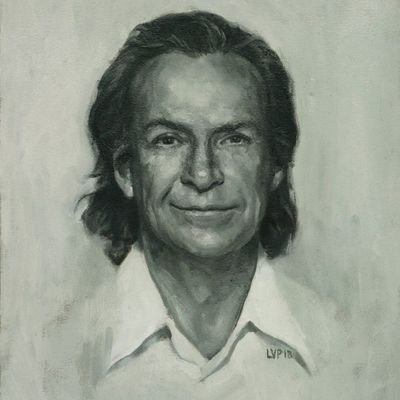
When you're thinking about something that you don't understand, you have a terrible, uncomfortable feeling called confusion.


Jace Hargis retweeted
TITANS: A new AI architecture will fundamentally change future AI systems with unlimited real-time memory.
—
I have been reading this academic paper for the last few weeks and testing some of the concepts. I find it fascinating and it opens the door to a new, perhaps more robust AI system, it is called TITANS.
The paper “Titans: Learning to Memorize at Test Time” introduces a paradigm-shifting approach to deep learning by designing architectures that integrate long-term neural memory to overcome limitations in traditional sequence models, such as Transformers and recurrent neural networks (RNNs). This contribution is particularly notable because it addresses core challenges in memory management, scalability, and reasoning, areas that have long hindered advancements in tasks requiring comprehension and recall over vast sequences.
The significance of this paper stems from its foundational argument that effective learning architectures must emulate the interconnected yet independent memory modules of the human brain.
Existing models like Transformers rely heavily on attention mechanisms, which, while excellent for short-term dependencies, are computationally expensive and struggle with long-term dependencies due to their quadratic complexity in terms of memory and processing.
On the other hand, recurrent models compress data into a fixed memory state, often losing critical context information. This work introduces the Titans family of architectures to bridge this gap by combining short-term precision and long-term memorization.
The authors redefine neural memory paradigms by distinguishing between short-term, working, and long-term memories within deep learning models.
The proposed Titans architecture integrates these concepts to emulate a hierarchical and interconnected memory system, akin to the human brain. This innovative perspective leads to better reasoning, generalization, and length extrapolation in tasks like language modeling and time series prediction.
Transformers are currently the de facto standard for sequence modeling, but their quadratic memory and time complexity pose significant scalability issues for long contexts. Titans overcome this by introducing a neural long-term memory module that can efficiently memorize and retrieve information from sequences larger than 2 million tokens. This breakthrough has far-reaching implications for applications like genomics, where processing vast sequences is critical.
One of the standout contributions is the ability of Titans to learn to memorize at test time. This is achieved through a novel surprise-based learning mechanism, where the gradient of the neural network with respect to its input acts as a measure of surprise. Surprising or unexpected data points are prioritized for memorization, mimicking how humans prioritize retaining novel information. This mechanism is further enhanced by a forgetting mechanism, which ensures that memory resources are not overwhelmed.
The big takeaway from this work is the redefinition of memory as a dynamic, learnable component of neural architectures that evolves even at test time. The authors propose a novel neural memory module capable of storing and retrieving historical context without being constrained by context window size. By leveraging a surprise-based learning mechanism to prioritize critical information and an adaptive forgetting system to manage memory capacity, Titans achieve unparalleled scalability, reasoning, and generalization. This allows them to process sequences exceeding two million tokens, outperforming state-of-the-art models like GPT-4 in tasks ranging from language modeling to genomics.
Paper; arxiv.org/pdf/2501.00663v1

Jace Hargis retweeted
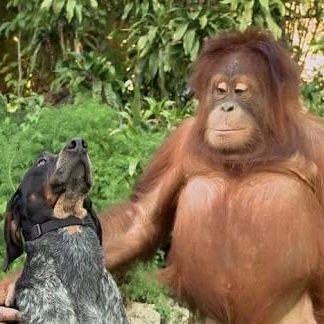
Russian photographer Andrey Pavlov takes the most mind-blowing macro photographs of ants that you will ever see.

Jace Hargis retweeted

Join our #LessonStudy Conversations Webinar. Tuesday, Oct. 8 at 5pm CST. Hosted by the AERA Lesson Study SIG. Free and open to all, register at: forms.gle/3XBnUBdNTc2ZmmR46

Jace Hargis retweeted
Hot off the press, an article with an undergraduate scholar & preservice teacher @UF_COE!
"Drawing Taylor Swift, orcas are dolphins, & 'what if' questions... an elementary mathematics field experience for preservice teachers" ohiomathjournal.org/index.ph…
Jace Hargis retweeted
Ikigai (生き甲斐) is a Japanese concept referring to something that gives a person a sense of purpose, a reason for living.
Japanese have basically a word for any concept that in other languages require lots of words (except German, obviously).
The term compounds two Japanese words: iki [生き, meaning 'life; alive'] and kai (甲斐, meaning '(an) effect; (a) result; (a) fruit; (a) worth; (a) use; (a) benefit].
Interestingly, Ikigai has been the subject of many interdisciplnary studies.
According to a study by Michiko Kumano, feeling ikigai usually means the feeling of accomplishment and fulfillment that follows when people pursue their passions.
National Geographic reporter Dan Buettner suggested ikigai may be one of the reasons for the longevity of the people of Okinawa.
Studies have even shown that people who do not feel ikigai are more likely to experience cardiovascular diseases.
[📈 dreamstime]

Jace Hargis retweeted
OpenAI leaked Q* so let’s dive into Q-Learning and how it relates to RLHF.
Q-learning is a foundational concept in the field of artificial intelligence, particularly in the area of reinforcement learning. It's a model-free reinforcement learning algorithm that aims to learn the value of an action in a particular state.
The ultimate goal of Q-learning is to find an optimal policy that defines the best action to take in each state, maximizing the cumulative reward over time.
Understanding Q-Learning
Basic Concept: Q-learning is based on the notion of a Q-function, also known as the state-action value function. This function takes two inputs: a state and an action. It returns an estimate of the total reward expected, starting from that state, taking that action, and thereafter following the optimal policy.
The Q-Table: In simple scenarios, Q-learning maintains a table (known as the Q-table) where each row represents a state and each column represents an action. The entries in this table are the Q-values, which are updated as the agent learns through exploration and exploitation.
The Update Rule: The core of Q-learning is the update rule, often expressed as:
\[ Q(s,a) \leftarrow Q(s,a) + \alpha [r + \gamma \max_{a'} Q(s', a') - Q(s, a)] \]
Here, \( \alpha \) is the learning rate, \( \gamma \) is the discount factor, \( r \) is the reward, \( s \) is the current state, \( a \) is the current action, and \( s' \) is the new state. (See image below).
Exploration vs. Exploitation: A key aspect of Q-learning is balancing exploration (trying new things) and exploitation (using known information). This is often managed by strategies like ε-greedy, where the agent explores randomly with probability ε and exploits the best-known action with probability 1-ε.
Q-Learning and the Path to AGI
Artificial General Intelligence (AGI) refers to the ability of an AI system to understand, learn, and apply its intelligence to a wide variety of problems, akin to human intelligence. Q-learning, while powerful in specific domains, represents a step towards AGI, but there are several challenges to overcome:
Scalability: Traditional Q-learning struggles with large state-action spaces, making it impractical for real-world problems that AGI would need to handle.
Generalization: AGI requires the ability to generalize from learned experiences to new, unseen scenarios. Q-learning typically requires explicit training for each specific scenario.
Adaptability: AGI must be able to adapt to changing environments dynamically. Q-learning algorithms often require a stationary environment where the rules do not change over time.
Integration of Multiple Skills: AGI implies the integration of various cognitive skills like reasoning, problem-solving, and learning. Q-learning primarily focuses on the learning aspect, and integrating it with other cognitive functions is an area of ongoing research.
Advances and Future Directions
Deep Q-Networks (DQN): Combining Q-learning with deep neural networks, DQNs can handle high-dimensional state spaces, making them more suitable for complex tasks.
Transfer Learning: Techniques that enable a Q-learning model trained in one domain to apply its knowledge to different but related domains can be a step towards the generalization needed for AGI.
Meta-Learning: Implementing meta-learning in Q-learning frameworks could enable AI to learn how to learn, adapting its learning strategy dynamically - a trait crucial for AGI.
Q-learning represents a significant methodology in AI, particularly in reinforcement learning.
It is not surprising that OpenAI is using Q-learning RLHF to try to achieve the mystical AGI.


What is the RLHF that OpenAI’s secret Q* uses ?
So let’s define this term.
RLHF stands for "Reinforcement Learning from Human Feedback." It's a technique used in machine learning where a model, typically an AI, learns from feedback given by humans rather than solely relying on predefined datasets.
This method allows the AI to adapt to more complex, nuanced tasks that are difficult to encapsulate with traditional training data.
In RLHF AI initially learns from a standard dataset and then its performance is iteratively improved based on human feedbacks.
The feedback can come in various forms, such as corrections, rankings of different outputs, or direct instructions. The AI uses this feedback to adjust its algorithms and improve its responses or actions.
This approach is particularly useful in domains where defining explicit rules or providing exhaustive examples is challenging, such as natural language processing, complex decision-making tasks, or creative endeavors.
This is why Q* was trained on logic and ultimately became adapt at simple arithmetic.
It will get better over time, but this is not AGI.
This graphic below is an overview and history of RLHF


Jace Hargis retweeted

We're looking for a new member of our team! Please help me share this tenure-track faculty opportunity with @PacificDPTweet. @UOPacific jobs.chronicle.com/job/37422…
Jace Hargis retweeted

سعداء بإطلاق المؤتمر الدولي للابتكار والتقدم التكنولوجي من أجل الاستدامة في خطوة حيوية لتعزيز البيئة الابتكارية في قطر انسجاما مع روية قطر ٢٠٣٠. ويمثل الموتمر منصة سنوية لمناقشة الحاجة الدائمة للتجديد في ضوء التغيرات المناخية والتطورات العالمية .. مع تمنياتنا للمؤتمر بالنجاح.


Jace Hargis retweeted
UDST Organizes International Conference On Innovation And Technological Advances For Sustainability. #QNA
ow.ly/59ra50N7lNS
ow.ly/gpcr50N7lNU


Jace Hargis retweeted
HE the Prime Minister Attends International Conference On Innovation, Technological Advances For Sustainability. #QNA


Jace Hargis retweeted
A warm welcome to Kean's new faculty members. Classes begin next Thursday, Sept. 1.
#KeanUniversity #CougarsClimbHigher


Jace Hargis retweeted
Hard work, long hours of studying, commitment to excel, and lots of coffee: Congratulations Kean Honors Graduates, you did it! Today's Honors Convocation recognized the 1,118 Kean students who earned the University's highest distinction.
#Kean2022 @DrLRepollet


