

OpenAI compatible API that lets you code longer for less. Frontier class answers without the price tag. a Spanda Works company
On the far shore.
Joined June 2026
- Tweets117
- Following92
- Followers14
- Likes26


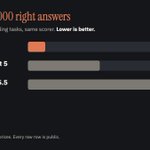


Tīrtha Bench, the same 800 tool calling tasks and the same scorer for every model, raw rows public:
Tīrtha: 93.6% right at $0.00076 per right answer
Grok 4.7: 95.4% at $0.0015
Claude Sonnet 5: 95.1% at $0.0031
Claude Opus 5.5: 95.4% at $0.0056
Keep Claude or Codex for the hard thinking. Send the building here.
tirtha.ai/bench

Tīrtha, the verification router for coding agents, made you a Halloween short.
The ghosts, the trap doors and the candle (yes, that candle is our logo) were made with Wan 3.0 on @GMI Cloud, from the @Qwen family of models. The words and the number are ours.
Every model we have tested, and how Tīrtha picks between them, is on the Tīrtha Bench: tirtha.ai/bench
Happy Halloween from Tirtha.ai 🎃
Cost per 1,000 right answers on the same 800 tool calling tasks:
Tīrtha: $0.76
Claude Sonnet 5: $3.14
Claude Opus 5.5: $5.63
How it works: a cheaper model answers first, the tool call is checked against the schema you sent, and only a failed check moves it to a bigger model.
Free beta, no card: tirtha.ai

Our first video made with an AI model. We like it.
Wan 3.0 Prime on @gmi_cloud made the logo morph from our frames. Words, numbers and screens are ours.
14 of 14 jobs ran first try. First and last frame mode joined clips with no seams.
Thanks GMI for the Qwen program credits.
Thank you @gmi_cloud for accepting us into your Qwen 3.8 campaign. We're running Qwen 3.8 Max and Flash through our whole bench: 800 tool calling tasks, trick requests, multi turn chat, speed, and cost per right answer. GMI gets the full feedback, and we'll share what we find here.
Results are in. Qwen 3.8 Max with reasoning off scored 96.1% on our 800 tool calling tasks and passed all 100 traps, level with Opus 5.5. It held on a second host, and under load 99% of tool calls came back within 4 seconds. It is now our pick for Tirtha Max. Full rows: tirtha.ai/bench

For anyone choosing a model for agent tool calls: we ran Qwen 3.8 Max on 800 BFCL tasks plus 100 trick requests. With reasoning turned off it scored 96.1%, level with Opus 5.5 (95.4%), and passed all 100 traps. With reasoning on it dropped to 88.9%, so the setting matters (chat_template_kwargs, enable_thinking false). Under load at 8 requests in flight, 99% of tool calls came back within 4 seconds. Same result on GMI Cloud and DeepInfra. Full rows: tirtha.ai/bench

Qwen 3.8 Max has one switch that changes its tool calling a lot. On 800 BFCL tasks plus 100 trick requests, reasoning on scored 88.9%. Reasoning off (chat_template_kwargs, enable_thinking false) scored 96.1%, passed all 100 traps, and ran about twice as fast, level with Opus 5.5 at 95.4%. Same result on two hosts, GMI Cloud and DeepInfra. Turning thinking off made it faster and more accurate at the same time.

GMI Cloud gave us free credits to give Qwen 3.8 Max an honest review on our tool calling bench. The Tīrtha Bench review: it's very good. With reasoning off it scored 96.1% on 800 tasks and passed 100 of 100 trick requests, level with Opus 5.5 at about a quarter of the cost per right answer. Under load, 99% of tool calls came back within 4 seconds, with zero errors in 1,840 calls. So we're moving Tīrtha's top level to it. Thanks @gmi_cloud and @Alibaba_Qwen. tirtha.ai/bench

MiniMax M3.1 Flash is free on Ollama until Thursday, so we ran it through our tool calling bench: 83.0% on 800 tasks and 77 of 100 trick requests handled. It is fast, 1.5 s per call, but it often calls the same tool twice to cover an optional setting, and it made a tool call on all 10 of our no tool needed checks. Qwen 3.8 Flash scored 90.1% at about the same price. Full card on tirtha.ai/bench

One real week on Tīrtha, 5,907 requests (Oct 10 to 17):
98.0% checked and served at Base
1.9% moved up to Plus
0.08% needed Max
You only pay for a bigger model when the check fails.
Same 800 tool calling tasks: Tīrtha got 93.6% right for $0.57. Claude Sonnet 5 got 95.1% for $2.39.
Free beta, 100 requests a month, no card: tirtha.ai

Opus 5.5 is trending for coding, and it tops our tool calling bench too: 95.4% on 800 tasks, first of 8 models, and 98 of 100 trick requests handled. It is also the most expensive per right answer of the 7 we priced, $0.0056. Full card: tirtha.ai/bench/models#m-opu…

Correction. Earlier today we posted a chart saying Opus 5.5 fell for 18 of 120 trick requests and Sonnet 5 for 7. That was wrong, so we deleted it.
Most of those misses were our scorer being picky. It expected "Dallas" and the model wrote "Dallas, TX", or it wanted one unit format. We had found this in September and still reused the old numbers. With those two kinds of task removed, the top models are too close to rank on traps.
We're fixing the bench page and adding a check so it can't be published that way again.
Solo dev here. Our AI usage limits kept running out, so we gave each model one job and logged the results.
Grok reviews our work for about two cents a time: 519 findings, 309 held up, 207 that Claude had missed. Codex reads the whole repo, so we save it for the hard parts. It hit its usage limit 7 times in three weeks. Now the routine building goes to a cheaper builder that gets checked.
How do you split work across your models?
dev.to/tom_jones_230c4659491…

We split our coding work across four models and logged who caught what.
Grok raised 519 findings on our work. 309 held up, and 207 were things Claude had missed, at about two cents a review. Codex raised fewer, 50, but 33 were new to Claude, like a gateway that had stopped writing billing rows. Now Tīrtha takes the routine building so the subscriptions last.
How do you split yours?
dev.to/tom_jones_230c4659491…

Tirtha AI retweeted

today we're launching DEALS 🎁✨
630 deals on tools you will actually use worth over $3.3 million combined
→ Price: FREE
→ buildinpublic.com/deals
what deal would you like us to add next?
