

Accelerate inference, model shaping, and pre-training on a research-optimized platform.
San Francisco, CA
Joined November 2022
- Tweets3.3K
- Following279
- Followers65.2K
- Likes2.5K





Introducing Together Compiler: agents that continually optimize kernels for your model, your hardware, and your traffic.
We built this to scale frontier research from the teams behind FlashAttention, ThunderKittens, ThunderAgent, and more to every customer deployment.
So far we're seeing:
👉 +12% to +20% median TPS on serverless endpoints our researchers had already heavily optimized by hand
👉 Customers in production cutting response and generation times by about a third to nearly half
Read the full story: togetherai.link/R7BKfl7
Together AI retweeted

"Together Compiler: Continual Compilation for AI Inference"
AI agents can optimize LLM inference, but testing every change requires restarting the entire inference engine, making experimentation extremely slow.
This paper by Together AI introduces Together Compiler, which lets coding agents continuously modify and test inference code without restarting the engine, using real workloads to measure performance.
This enables 252x more agent experiments and achieves up to 2.6x higher inference throughput than top open-source engines across frontier models.
alphaxiv.org/abs/2611.togeth…

“We are driving towards Super intelligence that is vastly superior to what we have today and will become a part of the labor force to solve kind of problems we have not been able to solve before.”
Our CEO, @vipulved , shares his vision for the future of AI in this conversation with @cheddar .
Watch the full interview: cheddar.com/media/inside-the…

collinear ai has been building on together post-training since our beta in april
with the latest release, self-onboarding made it easy for their team to launch full-scale agentic rl runs
together.ai/post-training

ripple-65b preview from ricursive is now live on together ai
the 65b dense model is built for agentic coding + reasoning, with ricursive reporting 80.5 on terminal-bench 2.1
trained from scratch on 12t tokens, with up to 1m context + apache 2.0
together.ai/models/ripple-65…

Inference is entering a new era. Models ship weekly, traffic shapes shift daily, and hardware turns over every year. The era of Static Inference, tuned once for one model with one traffic shape on one chip, is ending.
Welcome to the era of Polymorphic Inference: inference that adapts to new models, workloads, and hardware as they arrive.
Today we’re announcing Together Compiler, our first step into that era. It enables continual optimization, so a single overnight run can match or beat the manual expert tuning that used to take weeks.
Read the full vision from our SVPs of Research, @simran_s_arora and @realDanFu, on Polymorphic Inference and our research roadmap 👇
togetherai.link/uQJRZjW
Together AI retweeted

The Together Compiler (TKCC) from @simran_s_arora and her team is honestly one of the coolest things ever, and we have validated one of the InferenceX/AgentX results! The ability to continuously improve performance automatically while ensuring accuracy is great enough to quickly deploy to production!
Simran and her team are using TKCC and working on applying it to even more use cases. They will share more soon!
nitter.gq/simran_s_arora/status/…

Introducing the Together Compiler: continual compilation for AI inference! I’m super proud to finally share this work from our research team! ✨
Today’s inference is “Polymorphic” or shape-shifting, it doesn’t sit still. On OpenRouter, 80% of traffic goes to models released in the last three months and the top ten most popular open models each use a different architecture. Our customers constantly change their usage behaviors. Together Compiler leverages agents to continually optimize our deployments immediately as these changes occur.
Together Compiler research highlights include:
1. 252x better throughput: TKCC lets agents try 252x more optimization experiments per hour compared to prior agent inference optimization systems.
2. State-of-the-art TPS across InferenceX workloads we tried: TKCC outperforms the best InferenceX engine across all tested settings in just 24 hours & 2 nodes per compile. Including 1111 TPS on MiniMax M3.1 B200 and 1205 TPS on DeepSeek v4.1 Flash GB300 at batch size 1. NVIDIA, AMD, Trainium2.
3. Continuous recompilation: TKCC currently serves many trillions of production tokens per day and adapts to traffic shifts within just a few hours of recompilation.
4. Bitter lessons: TKCC’s design builds on 2+ years of building frameworks to accelerate AI Inference, starting from ThunderKittens and Megakernels. Compilers have always used abstractions and IRs, but we show that agentic compilers now reach higher performance ceilings without abstractions.
From an incredible team @reyna_abhyankar @dylan__lim @realDanFu @togethercompute!!
“AI is now improving the systems that run AI.” Thanks to @Forbes for covering Together Compiler and the shift to Polymorphic Inference.
New open models can now get fully optimized for production performance in hours, not weeks.
togetherai.link/OeAIz0u

Introducing Together Compiler: agents that continually optimize inference for production traffic.
Serving trillions of tokens/day. Up to 2.6x faster than leading InferenceX configs, up to 50% faster on customer workloads.
Congrats @reyna_abhyankar @dylan__lim @simran_s_arora and the team!
Introducing the Together Compiler: continual compilation for AI inference! I’m super proud to finally share this work from our research team! ✨
Today’s inference is “Polymorphic” or shape-shifting, it doesn’t sit still. On OpenRouter, 80% of traffic goes to models released in the last three months and the top ten most popular open models each use a different architecture. Our customers constantly change their usage behaviors. Together Compiler leverages agents to continually optimize our deployments immediately as these changes occur.
Together Compiler research highlights include:
1. 252x better throughput: TKCC lets agents try 252x more optimization experiments per hour compared to prior agent inference optimization systems.
2. State-of-the-art TPS across InferenceX workloads we tried: TKCC outperforms the best InferenceX engine across all tested settings in just 24 hours & 2 nodes per compile. Including 1111 TPS on MiniMax M3.1 B200 and 1205 TPS on DeepSeek v4.1 Flash GB300 at batch size 1. NVIDIA, AMD, Trainium2.
3. Continuous recompilation: TKCC currently serves many trillions of production tokens per day and adapts to traffic shifts within just a few hours of recompilation.
4. Bitter lessons: TKCC’s design builds on 2+ years of building frameworks to accelerate AI Inference, starting from ThunderKittens and Megakernels. Compilers have always used abstractions and IRs, but we show that agentic compilers now reach higher performance ceilings without abstractions.
From an incredible team @reyna_abhyankar @dylan__lim @realDanFu @togethercompute!!
We are live with @Kimi_Moonshot to go through Kimi K3.1 Pro.
Join now!

Everything you need to know about Kimi K3.1 Pro: A conversation with Moonshot AI and Together AI nitter.gq/i/broadcasts/2dKYBAyRX…

Everything you need to know about Kimi K3.1 Pro: A conversation with Moonshot AI and Together AI nitter.gq/i/broadcasts/2dKYBAyRX…
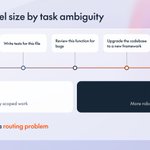
how clearly a task is defined can help guide model choice
scoped work like writing tests or renaming an API may not need your largest model
open-ended work like a framework upgrade or an auth refactor is where a larger model's reasoning is more likely to pay off

Kimi K3.1 Pro has arrived on Together AI
@Kimi_Moonshot’s most capable 3T-class model yet brings native multimodality, 1M context, and major gains across coding and agentic work
Run it as-is, or post-train it with RL/SFT on Together Post-Training for your own workflows
together.ai/models/kimi-k3-1…

Kimi K3.1 Pro has arrived, and the weights are dropping tomorrow.
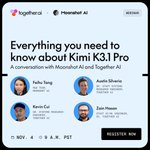
Tomorrow, hear @Kimi_Moonshot 's Feihu Tang explain the architecture and decisions behind it.
He joins Austin Silveria, Kevin Cui and Zain Hasan from Together AI for a deep dive into long-running agents and production inference.
🗓 Wed, Nov 4 · 9 AM PT / 12 PM ET Register → luma.com/together-1w4x

Europe’s largest private company just made open models its default for coding.
@Revolut: ~2,000 engineers, 1/10th the cost, 70% faster lead time.
Proud to be part of the infrastructure powering open models in production 🚀.

BREAKING: Revolut moved ~2,000 engineers onto self-hosted GLM for coding and pushed Claude Code and Codex to the exception list.
Per David Abitbol, who leads AI ops there: 56 Nvidia B200s, a blended 30 cents per million tokens, roughly a tenth of what they paid Anthropic and OpenAI. Engineering lead time improved 70%.
Here's the part that matters: the gains showed up when tokens stopped being rationed. Engineers quit saving AI for the hard tickets and pointed it at everything.
Frontier models become the exception, open weights become the default. That's a pricing problem for every lab heading to IPO.
h/t @OliverMolander
Would you move your team off frontier APIs if the bill dropped 90%?

“Token maxing without cost maxing.” That’s the real goal.
@vipulved at #TCDisrupt on why the smartest teams are swapping closed models for smaller, faster ones.
youtube.com/watch?v=niojbz9f…
training and generation stay aligned on together post-training
that means the reward signal you designed is the one the model actually learns from, and the behavior carries through to serving
together.ai/post-training

one benefit of an open model stack: every task doesn’t have to go through the same model
well-specified work can run on smaller, faster models, while harder or more ambiguous tasks benefit from larger ones
match the model to the work instead of defaulting to the biggest one

Cool use case for open models!

If you want your apps to be more unique, generate your own fonts!
These only cost $0.02 each with DeepSeek V4.1 Flash 1017 on @togethercompute.
Open sourcing all 36 fonts on Monday!
agentic rl means training across long, multi-turn interactions with tools
together post-training supports tool calls, async generation + the environment you already use
you define the environment and rewards. we run the training + generation
together.ai/post-training
