

Accelerate inference, model shaping, and pre-training on a research-optimized platform.
San Francisco, CA
Joined November 2022
- Tweets3.2K
- Following276
- Followers64.5K
- Likes2.5K






Together AI retweeted

Better AI for global work starts with better training.
Deel’s Pangaea K1 model is trained on 43,500+ pages of expert knowledge and fine-tuned on @togethercompute.
The result: faster, more accurate answers for teams everywhere. Thanks for the partnership.

.@deel’s data science team went from setup to real rl experiments on together post-training in a couple of hours
they then ran up to five experiments at once on the same gpu capacity
more experiments per gpu means a much faster iteration loop
together.ai/post-training

.@deel’s data science team went from setup to real rl experiments on together post-training in a couple of hours
they then ran up to five experiments at once on the same gpu capacity
more experiments per gpu means a much faster iteration loop
together.ai/post-training
together post-training keeps the training loop in your hands
your code defines the data, rewards, loss, optimizer + lora or full weights. gpu setup and the hard infrastructure are already handled
start from a recipe 👇
github.com/togethercomputer/…

Muse Spark Open is the most capable US open-weight model to date, and it’s live on Together AI.
Join @AIatMeta and Together for a live technical deep dive: what Meta built, and how we serve it in production.
🗓 Mon, Oct 26 · 12 PM PT / 3 PM ET
Register → luma.com/m30txf74

greptile wants to validate every piece of software on the planet
as more code gets written by ai, the first review pass needs to be independent + fast. greptile’s v5 agent spins up sub-agents on every pr, pairing open + frontier models so one model’s blind spots don’t decide what gets caught
together ai powers part of the inference behind those open models, helping reviews come back faster and at lower cost
watch how @greptile does it
read more 👇
together.ai/customers/grepti…

sf, join us this thursday for step 5 preview launch night with stepfun
we’ll dig into the model, building + serving agent workloads, and what’s worth building as models keep improving, with dan fu, hongyu zhou, mar hershenson, saoud rizwan, joey wang
rsvp: luma.com/12t5e4lc


together post-training on b200s is $9/gpu-hour for the first eight weeks, down from $11
run sft or rl, iterate on more experiments, and keep the training loop in your own code
together.ai/post-training

Kaffee Inferenz just opened, two minutes from GTC Berlin ☕️. Fresh coffee, zero prompts required. Map to find us in the thread.
Find your way to Kaffee Inferenz: maps.app.goo.gl/sHjL5PnGfGgz…

Together AI retweeted

Got to be a beta-tester for this! Pretty cool, agent-friendly and works for most-use cases!
Custom Models ftw
Together Post-Training is live
Turn open models into custom models you own, with SFT or RL.
You define the data, rewards, environments and the training loop itself. We run the hard infrastructure underneath it, tuned for quality and speed.
Under the hood, every model gets a GPU setup we’ve already tested and rollout engines tuned for RL.
We also keep training and generation in sync, so the quality you see in training holds up when you serve the model.

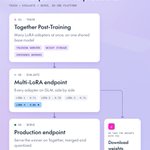
When you have a few good runs, compare the adapters side by side on one endpoint. Then deploy the best one on Together, or download the weights and run it anywhere.
Available today on open models from Meta, Z.ai, Moonshot and Qwen, with more on the way.
together.ai/post-training

deepseek v4.1 flash 1017 is now live on together ai
deepseek trained this update with self-feedback rl to get better at building complete projects from scratch, from web apps and games to longer agentic coding tasks
same price. try the model now ↓
together.ai/models/deepseek-…
