

CEO & Founder @ Overmind - Ex-Engineer @ GCHQ
London
Joined January 2026
- Tweets64
- Following92
- Followers77
- Likes137




Tyler Edwards retweeted
60-70% of the world’s computers run on Linux. Yet Microsoft and Apple are the commercial leaders.
Wouldn’t be surprised if LLMs go the same way. We’ll still have Anthropic, OpenAI, and all the other new frontier labs...but open-source models will lead real-world adoption.

Tyler Edwards retweeted

Coinbase built this for their employees.
Overmind ships it for everyone.
Run /overmind finetune in:
• Claude Code
• Cursor
• Codex
Open source, and the model is yours.

We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case).
I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves.
We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them:
"/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started"
I imagine we'll have some backend services that could be replaced entirely by this new architecture.


60-70% of the world’s computers run on Linux. Yet Microsoft and Apple are the commercial leaders.
Wouldn’t be surprised if LLMs go the same way. We’ll still have Anthropic, OpenAI, and all the other new frontier labs...but open-source models will lead real-world adoption.

Abstraction is the core of innovation: taking something complex and making it simple, accessible, and usable.
That’s why we built Overmind. To abstract away the complexity of AI infrastructure and give everyone the tools to train and deploy their own models.
Overmind turns anyone into an AI lab.
• Builds a context graph from code and traces
• Curates training and eval datasets
• Evaluates prompts and models
• Trains smaller, specialized models
github.com/overmind-core/ove…

Decision models had a big week. Clef, Strands, OpenAI's Decisions API, Jev already out.
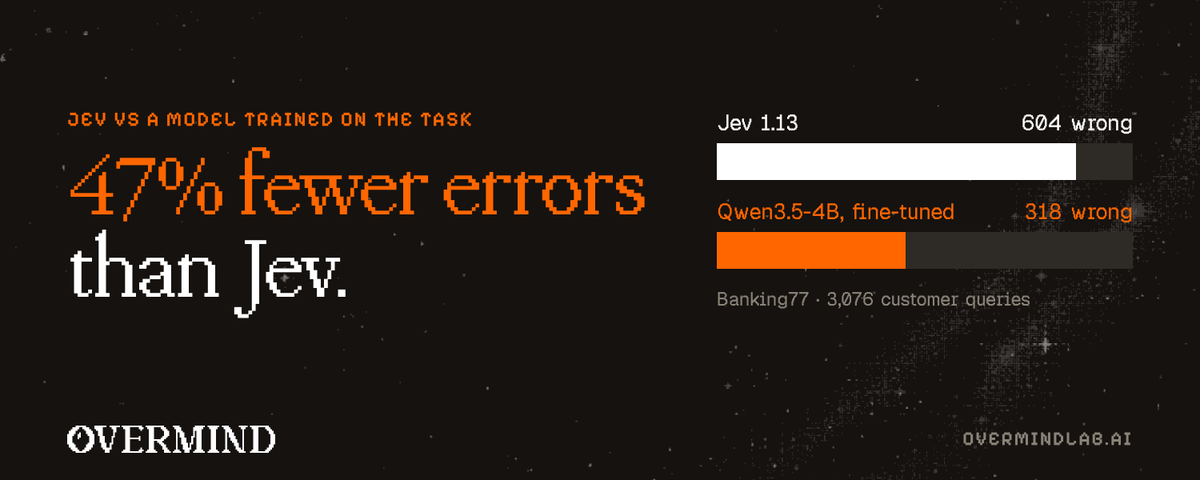
They're great when you don't have labels yet. We fine-tuned a 4B on Banking77 anyway.
89.7% vs Jev's 80.4%. One LoRA, under an hour.
TLDR: the moat is your labelled data.
IMO: the teams that win big will be the ones that train their own models. So we’ve made it easy for them. And its open-source! github.com/overmind-core/ove…

Introducing Overmind. The training platform for agents.
Overmind trained models across biomedical, legal, and engineering tasks beating the frontier and achieving:
• 7x better accuracy
• 20x cheaper usage
• 28x less hallucinations
Train your own: github.com/overmind-core/ove…
Tyler Edwards retweeted
Had a blast!
Watch this space, Q4 may or may not start off with a lot of fire... 👀

It will take me a year to try every new thing announced @OpenAI devday today. Team is cooking! And more resets please 🔵🟢🟠🟣
@TylerEdwas

Very nice Claude can help you hillclimb ⛰️
I'd rather the eval set also trains a specialist agent I own though, but that's just me ;)

Claude can now help you build evaluations and hillclimb on them.
In this article, we share guidance on eval design & skills that Claude Code can use to improve your applications.
claude.dev/blog/automating-e…

Fun one at @heavybit DevGuild last week!
Good room, great minds.


A truly 🔥 room last Thursday at DevGuild. A huge thank you to everyone who came and especially to our speakers and roundtable facilitators 🙏🏼
🎥 Talk videos coming to Heavybit.com
🎉 Show + Tell winners took home credits from @LightningAI, @baseten and @neondatabase


Tyler Edwards retweeted
Keep your tracing stack. Train from it.
Overmind now imports traces from @langfuse, @LangChain (LangSmith), @braintrust and Galileo. Connect a project and it backfills the history, then keeps syncing.
Those traces become eval sets and training data for a model you own.
Had a blast!
Watch this space, Q4 may or may not start off with a lot of fire... 👀
It will take me a year to try every new thing announced @OpenAI devday today. Team is cooking! And more resets please 🔵🟢🟠🟣
@TylerEdwas
The Token Lords have given us such bounty! Honestly the pace of innovation at @OpenAI is astounding.

Tyler Edwards retweeted

A truly 🔥 room last Thursday at DevGuild. A huge thank you to everyone who came and especially to our speakers and roundtable facilitators 🙏🏼
🎥 Talk videos coming to Heavybit.com
🎉 Show + Tell winners took home credits from @LightningAI, @baseten and @neondatabase
Been making SF tech events my whole personality.
Now that @sambrunty is in town, it’s time we host our own. Hang with us and the good people at Daytona and Doubleword at our hackathon during #SFTechWeek.
RSVP to Model Training Night: partiful.com/e/zVfEE2R1zoj8W…
Fine-tuning a smaller open-weight model isn't a compromise.
For specialised tasks it can be the better way to build.
Across legal, biomedical and aviation benchmarks, our fine-tuned models were 7x more accurate at quoting clauses word for word and 20x cheaper on the legal task.
How we did it: overmindlab.ai/research/when…
