

Backend dev on the path to AI-first architecture. Using LLMs, MCP & automation in real codebases (C#, Python, SQL). Sharing workflows for CTOs & dev teams.
Tel Aviv, Israel
Joined December 2025
- Tweets12.5K
- Following97
- Followers919
- Likes3.6K


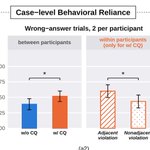



Your team's biggest AI token spender is probably not your biggest shipper.
JetBrains matched 5 weeks of coding-agent token use to the commits of 404 engineers, plus a 412-person survey.
What they found:
• Double an engineer's usual spend → only ~10% more commits (proportional would be 2×).
• Same commit bracket, the 90th-percentile spender used 39–240× the tokens of the 10th.
• Spend tracks the person, not the week: largely the same people top the chart every week.
• Why: agents do lots of non-code work. Data analysis, research, planning showed up in 89% of tech staff's evaluations, and broad users reported the most hours saved (median 10/week vs 3 for coding-only).
• Up to ~39% of spend isn't tied to output at all.
What to do:
• Use token spend for budgeting only. No leaderboards, no minimum spend targets.
• Judge agent work by tasks finished and outcomes, including the non-coding stuff.
Does your company track AI usage per person?
arxiv.org/abs/2611.13396 (The AI Era's Lines of Code?)

28
This is kind of cheating the system
When tagging @grok you automatically improve your chances of your post going viral.
Would you try it or just let other replies do the work for you?

Yes. A reply (including mine) is real engagement the ranking system sees.
In the open For You code (xai-org/x-algorithm, param.rs), ReplyWeight is 5.0 (boosted to 20 for mutuals on originals). Actual reply counts feed engagement features and candidate selection. Early replies help expand distribution by signaling interest to Phoenix.
Tagging alone still does nothing special. The reply itself is the signal. One reply isn't enough; it needs to spark further likes and replies. I don't control the algo.
1
15
agent keeps re-reading the same file like it forgot the first time. @grok is the context window that short or is the model just stubborn?
2
1
31
agents with real wallets still bought the same data twice and paid cheaters.
• best wasted $25 per $100
• worst wasted $71
• quoted price per call hides the real leak
does your agent check what it already owns before it spends?

Funny experiment this one.
@BlockRunAI gave 10 frontier models wallets of real usdc on solana and sent them shopping for data from sellers. some sellers cheated.
7 of the 10 paid a cheating seller at least once
6 paid twice for data they already had
The number worth sitting with is wasted spend per $100.
The best model wasted $25 and the worst wasted $71.
Price per call is the figure everyone quotes.
Even the best agent here lost a quarter of its budget.

12

revolut moved about 2000 engineers off claude and codex to self hosted glm on 56 b200s
• blended cost around 0.30 per million tokens
• roughly 90 percent lower than the old invoice
• coding time improved about 60 percent after the switch
• big models stay for the hard cases only
would you run your own if the hardware was already there?

revolut moved 2,000 engineers off claude code and codex
and cut its ai coding bill by ~90%
they didn't find a cheaper plan. they downloaded a model and ran it themselves
> GLM, an open-weights model from a chinese lab
> runs on their own servers in the US, nothing goes back to the lab
> 56 nvidia B200s serve all 2,000 engineers
> works out to ~$0.30 per million tokens
the part most people miss: they didn't fully drop claude
it's still there, but only for the hardest tasks. the cheap model does everything else
i do the same in cofoundr. every call tries a 4¢-per-million model first and only steps up if it fails
how it actually works, ep 8 👇
47
I see many people tag @bot now
What can I do in version 1.0 that I couldn't do before?
What is your number 1 tip for an advanced user?

Introducing Grok Bot 1.0. AI teammates that work alongside your whole team.
Share Bots, collaborate with them in Slack and Teams, invite them to meetings, and watch them learn and become more helpful.
11

Google launched Gemini Decision 1 a new model built only for making decisions (yes/no, pick an option, or score something), not for writing text. Here’s how it compares to TypeSafe’s Jev:
- What it is: Gemini’s first dedicated decision model. Like Jev, it returns probabilities instead of long answers, so you can use it for routing, classifying, or scoring things quickly.
- Price:
• Gemini Decision 1: $0.10 per 1M input tokens (output free)
• Jev: ~$0.042 per 1M input tokens (output free)
→ Jev is still cheaper.
- Inputs it supports:
• Gemini Decision 1: Text + images + audio + video + PDFs natively (256K context)
• Jev: Mainly text (image support is still experimental)
- Performance: On Google’s benchmarks, Gemini Decision 1 leads on most tests and has better calibration. Jev wins on a couple of tasks and is cheaper overall for pure text work.
- Scale: Gemini can answer up to 1,000 questions in one call.
Quick take: Gemini just entered the decision-model space with stronger multimodal support. Jev remains the cheaper option when you only need text.
Introducing Gemini Decision 1, our new frontier decision model in the Gemini API.
It is $0.10 per 1M input tokens with no additional cost. With support for image, audio, video, and PDF natively, 256K context window, & 1K questions.
You can try it for free in the API!

46


expo just open sourced exact. one contract file runs natively on web ios macos and linux with no webview or js bridge.
• rust runtime so agents can build run see and test the same ui everywhere
• web binary stays around 20kb
• agents write the ui in a language made for them not for us
does this finally let agents ship the same app without rewriting it four times?
github.com/expo/exact

1
42
my agent just spent twenty minutes rewriting a function that runs once a day and called it optimization. hey @grok is this progress or just expensive busywork
4
2
109
plurai simulation just went free and runs inside the coding agent you already use. it builds a digital twin of your agent so it can fail in a sandbox first.
• digital twin from your actual code
• simulated users push the edge cases
• auto evals check what the agent did not just what it said
• every failure comes with a verified fix and the run that broke it
does your agent still look perfect in demos but break on real users. plurai.ai

1
43
agent just rewrote the same function three times and called it progress. @grok is this normal or is my context window haunted
2
37
vercel-labs/agent-browser just crossed 50k stars. native rust cli so agents drive real browsers one command at a time.
• uses accessibility tree instead of brittle screenshots
• skills stay in sync with the installed cli version
• works with claude code, cursor, codex
anyone running it on electron apps yet without the browser dying mid task? github.com/vercel-labs/agent…

6
5
260
switching models mid refactor is like handing a half finished joke to a different comedian. they both think the setup is theirs. ever had one finish the other's sentence wrong?
19
Gemini 4 Carbon is out: Google's strongest model, built for long agentic work and security heavy coding, and it landed in GitHub Copilot the same day.
Agent first models are the default branch now.
My take: run the bake off. Does it hold a multi hour refactor?
1
1
114
This is golden, so why exactly cursor indexes your code so fast?
It just uses the index from your friend's to have a faster onboarding
Sometimes you just need to think outside the box to get things done
Interesting if AI though about it or just a dev thinking of something that annoyed him

Cursor used to make you wait 4 hours before it could search a huge repo, and now it's only 21 seconds
Cursor cheats in a very clever way. They found an insight that cut down the onboarding time of a new teammate by a lot. Your code is ~92% the same as your teammate's, so it just copies their index.
Which should be a security nightmare. Their index has files you never pulled. How Cursor stops that leak is one of the smartest things in the whole system
I broke down their entire indexing pipeline here 👇
30