

CS PhD student @NotreDame | Prev: @IBMResearch @amazon @JHUCLSP 🦋: https://xitter.cf/t.co/gPXvdPuesy
South Bend, IN
Joined December 2019
- Tweets149
- Following677
- Followers246
- Likes543





Pinned Tweet
Thrilled to share that I'll start my Ph.D. at @ND_CSE this fall, working with @Meng_CS. I am so grateful for the sincere guidance from my current advisor, @DanielKhashabi, and for the unconditional support I received from my family, friends, and collaborators over the past years!
Starting soon! If you’re curious about multi-objective RL (MORL) and how it applies to LLMs, please stop by Room F7 at 16:45 today. Session 9: Machine Learning for NLP 3. Hope to see y'all there!

I will be at #EMNLP2026 in Budapest next week to give an oral presentation of our TACL paper on Multi-Objective Alignment.
Excited to catch up with old friends and meet new ones! Feel free to reach out if you’d like to grab a coffee together!
I will be at #EMNLP2026 in Budapest next week to give an oral presentation of our TACL paper on Multi-Objective Alignment.
Excited to catch up with old friends and meet new ones! Feel free to reach out if you’d like to grab a coffee together!
✴️ Pleased to introduce our new paper yining610.github.io/dynamic-…
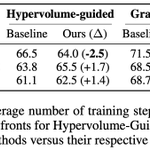
- Rebalance multiobjectives during training through dynamic reward weighting
- Build Pareto-dominant front over static baselines across online RL algorithms, datasets, and model families
- Faster convergence rate
1/8

Here is the recorded video of the paper👀 youtu.be/3n1nvOwiKPE?si=yG_K…
Yining Lu @ EMNLP 2026 retweeted

We built Agent as Policy (AGP), a robot control harness on top of GPT-6 Astra.
With AGP, Astra performs zero-shot manipulation on real robots across precision manipulation, long horizon tasks, dynamic actions, and deformable objects.
How it works. 🧵
agent-as-policy-2026.github.…
Yining Lu @ EMNLP 2026 retweeted

Please submit papers to NeurIPS 2026 Workshop on Continual Learning for Enterprise AI Agents (CLEA)! We welcome submissions on continual learning, AI agents, reinforcement learning, agent memory, workflow learning, planning, evaluation, and enterprise AI. clea-neurips.github.io/

Yining Lu @ EMNLP 2026 retweeted

Introducing Kimi K3: Open Frontier Intelligence
🔹 2.8 Trillion Parameters, 1 Million Context, Native Multimodal
🔹 Kimi Delta Attention enables up to 6.3x faster decoding in million-token contexts
🔹 Attention Residuals deliver ~25% higher training efficiency at <2% additional cost
🔹 Built for long-horizon agentic coding and self-evolving workflows
Kimi K3 is now live on on Kimi.com, Kimi Work, Kimi Code, and the Kimi API.
Open Weights by July 27, 2026.
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.com/blog/kimi-k3


Yining Lu @ EMNLP 2026 retweeted

Imagine this: It's Friday. You've been deep in a debugging session with your agent for hours. Suddenly it says: "Need to compact context" because it's about to exceed the context window. And with that, it forgets various details about your session.
𝐓𝐡𝐞 𝐜𝐡𝐚𝐥𝐥𝐞𝐧𝐠𝐞
As they work, agents' context fills with both useful things and junk (dead-end searches, stale results, superseded plans). That junk impacts everything that follows. Compaction (summarizing the context and resuming from the summary) is the standard fix.
Two questions matter: (1) 𝑤ℎ𝑒𝑛 to compact, and (2) ℎ𝑜𝑤 to compact.
Both matter: a poorly-timed call discards the partial result you still needed.
𝐖𝐡𝐚𝐭 𝐝𝐨 𝐩𝐞𝐨𝐩𝐥𝐞 𝐝𝐨 𝐭𝐨𝐝𝐚𝐲?
Within academia there are a few camps:
1️⃣ Deployed agents compact at a certain token threshold. This is an intuitive starting point: compact if you're about to exceed. But it starts to make less sense once one realizes that this compaction point may appear in the middle of an important task. And there is no agreement on the threshold — triggers range from 30% to 95% of the context window.
2️⃣ Another camp compacts on a fixed interval — every k tokens regardless of trajectory state. This increases the frequency of the compactions, which allows one to use shorter active context (and hence less memory). But again there is no informed logic to when compaction is applied.
3️⃣ Training-based approaches bake the when-to-compact decision into weights via SFT/RL. But with the increasing capabilities of the models, especially with their tool-use capabilities, is training really a necessity?
In industry, various agents have compaction strategies that more or less work. We don't always know how they work. Even in cases that we do, it's unclear how well they do and why.
𝐎𝐮𝐫 𝐩𝐫𝐨𝐩𝐨𝐬𝐚𝐥: 𝐒ᴇʟꜰ𝐂ᴏᴍᴘᴀᴄᴛ
A training-free scaffold pairing two inference-time elements:
(i) 𝐀 𝐜𝐨𝐦𝐩𝐚𝐜𝐭𝐢𝐨𝐧 𝐭𝐨𝐨𝐥. The model emits a summarize signal, the scaffold runs the summarization, and generation resumes from the summarized prefix. This is the ℎ𝑜𝑤.
(ii) 𝐀 𝐫𝐮𝐛𝐫𝐢𝐜 𝐠𝐚𝐭𝐞. At periodic probes, the model returns COMPRESS or CONTINUE. Fire when a sub-task has resolved or the trajectory is converging. Suppress mid-derivation or when stuck. This is the 𝑤ℎ𝑒𝑛.
The same model is generator, judge, and summarizer.
𝐎𝐮𝐫 𝐞𝐯𝐚𝐥𝐮𝐚𝐭𝐢𝐨𝐧𝐬
We evaluate on two task families and 6 datasets: (1) Competition math (IMO-Answerbench, HMMT Nov 25, HMMT Feb 26) and (2) Agentic search (BrowseComp, BrowseComp-Plus, DeepSearchQA).
We also evaluated 7 models: GLM-4.7-Flash, MiniMax-M2.5, MiMo-V2-Flash, Qwen3-4B-Instruct, Qwen3-30B-A3B-Instruct, Qwen3.5-4B, Qwen3.5-9B.
𝐅𝐢𝐧𝐝𝐢𝐧𝐠𝐬
🔹 The pattern of gains is consistent across various evaluations: baseline < fixed-interval ≤ 𝐒ᴇʟꜰ𝐂ᴏᴍᴘᴀᴄᴛ.
🔹 In scenarios where window size is limited, +𝟏𝟖.𝟏 𝐩𝐨𝐢𝐧𝐭𝐬 over no-compaction.
🔹 Even if there is no limit on context window, 𝐒ᴇʟꜰ𝐂ᴏᴍᴘᴀᴄᴛ is still helpful. It is the strongest method on all three models: +𝟓–𝟗 𝐩𝐨𝐢𝐧𝐭𝐬 over no-compaction, at 𝟑𝟎–𝟕𝟎% 𝐥𝐨𝐰𝐞𝐫 𝐩𝐞𝐫-𝐪𝐮𝐞𝐬𝐭𝐢𝐨𝐧 𝐜𝐨𝐬𝐭.
🔹 In our analysis, we find that 𝐒ᴇʟꜰ𝐂ᴏᴍᴘᴀᴄᴛ fires earlier than the fixed-threshold baseline.
🔹 We also observed that 𝐒ᴇʟꜰ𝐂ᴏᴍᴘᴀᴄᴛ helps most on the hardest questions, where deep search accumulates the largest contexts. On easy questions, all three policies are within noise.
——
💡 𝐓𝐚𝐤𝐞𝐚𝐰𝐚𝐲:
💡 "When to compact" is a meta-cognitive capability a lightweight rubric can supply at inference time .
💡 Across 6 benchmarks and 7 models: 𝐒ᴇʟꜰ𝐂ᴏᴍᴘᴀᴄᴛ matches or exceeds fixed-interval summarization at 30–70% lower cost.
💡 To our knowledge, this is the first work to introduce and evaluate rubric-based adaptive compaction timing in a training-free setting.

Yining Lu @ EMNLP 2026 retweeted

🚨 New paper: "Self-Compacting Language Model Agents"
LM agents build up long traces of reasoning and tool calls. As the trace grows, old mistakes and stale info stick around and anchor everything that follows. We ask: can the model itself decide when to clean up?
Yining Lu @ EMNLP 2026 retweeted

Real-world agents juggle instructions from skill files, tools, other agents, ... each with different trust levels. When these conflict, can models reliably prioritize the most trusted one?
Our ManyIH-Bench🪜 finds that even frontier models like GPT-5.4 only get ~40% accuracy! 👇

Yining Lu @ EMNLP 2026 retweeted
LLMs continue to struggle with long-context tasks—such as needle-in-a-haystack problems—because of “positional bias.” What can we do if we only have 𝘣𝘭𝘢𝘤𝘬-𝘣𝘰𝘹 access to the model? (i.e., we can’t modify the model weights or attention patterns, as is often the case with API models.)
We introduce ⭐𝐆𝐨𝐥𝐝-𝐏𝐚𝐧𝐧𝐢𝐧𝐠⭐, a black-box Bayesian framework that, at inference time, strategically and iteratively shuffles documents to overcome positional bias.
Specifically, it searches over long contexts by (i) reordering documents to concentrate high-belief items in highly “diagnostic” positions, and (ii) updating beliefs about document relevance from model outputs.
We show that GP provably identifies a target among N documents in O(log N) rounds, ensuring scalability to many-document settings.
More in the paper: arxiv.org/pdf/2510.09770

Why does improving one objective in multi-objective RL sometimes hurt others, even when they shouldn't conflict from the MOO and MTL sense? And why only on certain models? 🤔
This isn't Pareto tradeoffs. It's 𝐜𝐫𝐨𝐬𝐬-𝐨𝐛𝐣𝐞𝐜𝐭𝐢𝐯𝐞 𝐢𝐧𝐭𝐞𝐫𝐟𝐞𝐫𝐞𝐧𝐜𝐞 in LLM alignment.
We uncover this in arxiv.org/abs/2602.06869 by
- answering why and when this model-dependent interference actually happens.
- conducting the first systematic benchmark of classic MOO/MTL methods for LLM alignment.
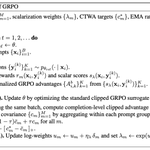
- proposing CTWA (Covariance-Targeted Weight Adaptation), our solution that actually works across the board.
We hope this work could provide actionable insights for multi-objective alignment for LLMs. Details in the thread below 👇

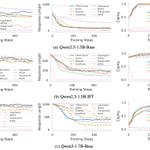
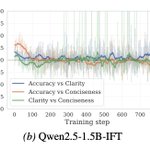
Our method, CTWA, effectively mitigates cross-objective interference compared to others. Competing methods either quickly sacrifice accuracy to achieve superficially high conciseness and clarity (e.g., GradNorm in 1a, Linear and Dynamic weighting in 1b), or trying to maintain high accuracy while overlooking the improvement of others (e.g., Lagrangian in 1a and PAMA in 1b). In contrast, CTWA achieves strong, balanced performance across all three objectives.

Our code is available at github.com/yining610/ctwa. Huge thanks to my advisor @Meng_CS for his support on this project.

Yining Lu @ EMNLP 2026 retweeted

Awesome work! 🧠 GDPO solves the signal collapse issue beautifully.
Our Dynamic Reward Weighting tackles the optimization side: since objectives vary in difficulty, static weights often waste training effort or get stuck.
Both findings highlight that simple linear scalarization is just not enough for complex alignment.
arxiv.org/pdf/2509.11452

RLVR is powerful — but how do you train with multiple rewards effectively? 🤔
🎯GDPO (not GRPO) is coming.
We introduce Group reward-Decoupled Normalization Policy Optimization (GDPO), a new multi-reward RL algorithm that consistently improves per-reward convergence over GRPO across a wide range of tasks. (1/n)

📣 My first system paper 📣 We built a decentralized RAG system that solves data reliability challenges in real-world settings. The sources provided by each data owner will be securely managed and scored on the blockchain.
🚀 one-line command to deploy: github.com/yining610/Reliabl…


Decentralized RAG allows your database to benefit all LLM clients. On the other side, not all data sources are reliable. Managing source reliability on blockchain can avoid third-party manipulation. Introducing dRAG + Blockchain + Truth Discovery: arxiv.org/abs/2511.07577

Paper link: arxiv.org/abs/2511.07577.
Huge thanks to all my amazing coauthors: Wenyi Tang, Max Johnson, Prof. Taeho Jung, and Prof. @Meng_CS.
Yining Lu @ EMNLP 2026 retweeted
Decentralized RAG allows your database to benefit all LLM clients. On the other side, not all data sources are reliable. Managing source reliability on blockchain can avoid third-party manipulation. Introducing dRAG + Blockchain + Truth Discovery: arxiv.org/abs/2511.07577