

Magnets must be respected, but need not be feared. 𝕏 profile subsumed by Shihan Qu, founder of ᐅfed bannedᐊ Zen Magnets. Micromags still @ https://xitter.cf/t.co/EcgpmLNP9Y
Denver, CO
Joined July 2009
- Tweets6K
- Following633
- Followers4K
- Likes35.9K





Pinned Tweet
Mohit's Imajev now in FP8 quant and optimized for SM120. 0.1% accuracy loss from the BF16 version and ~50% faster. Should work well for SM121 too.
huggingface.co/zenmagnets/Im…


Ultra-niche but posting just in case someone is looking for such a thing:
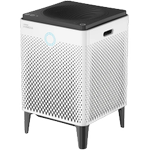
Made some scripts to control a coway 400s air purifier locally, without downloading their mobile app or letting it phone home to korea.
github.com/shihanqu/coway-40…

Modified version of @fraserpricee 's recipe is printing deepseek v4.1 1017 tokens at 340 tok/s single stream which is the fastest I've experienced on my own hardware for NVFP4.
Turns out previous 160 tok/s results were largely because fraser's recipe was incomplete and didn't contain all configs needed. Fraser was helpful (and had a much lower boast/receipt ratio) in DM communication. 😅
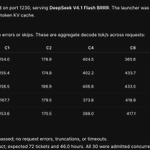
The claimed 700+ tok/s is still largely based on measurement yardstick optimization. Wasn't easy getting the man to acknowledge that standardized measurement is just basic intellectual honesty, but the stack is real. Below C8 this is the fastest I'm aware of for serving ds41f on tp4 rtx6k.
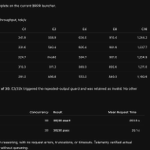
llm-inference-bench image below shows a modified version of BRRR. I'm calling it BRRR/B12X hybrid as it uses native B12X above 8 scheduled tokens which leads to some gains at higher concurrency.
Recipe in 🧵


@fraserpricee's 700+ tok/s seems the result of race track optimization more than it is inference optimization. On a standardized llm-inference-bench, fraser's (finally released) recipe getting ~160 tok/s C1, and ~400 tok/s C8. That's nearly half of the current flare docker from @YourLocalAILab
4x RTX direct PCIE 5x16 with 400W Pl, and no my engram ssd isn't slow


Just reddit doing reddit things

R/opensource moderators go full retard and push out oppressive rules for what can be posted to their sub.
1: no AI contributed projects
2: only multiple contributor projects
3: must have an existing community
4: bans non-native English speaking contributions because the mods can't tell if they are AI or not.
This criteria would block Linux posts on the open source and remains to be seen if they will actually do that.
Reddit mods essentially exist to get in the way at this point. Get rid of them.

𝗭𝗲𝗻 𝗠𝗮𝗴𝗻𝗲𝘁𝘀 retweeted

Do not quote retweet this or I will be forced to give people $42.0 or $420!
This is not engagement farming, it’s 1am and I’m bored AF and we all deserve a 420 break!
Do not quote retweet or you might get smashed with X Money


𝗭𝗲𝗻 𝗠𝗮𝗴𝗻𝗲𝘁𝘀 retweeted
When you download an abliterated model, what are you using it for?
21%Defense
14%Offense
50%Sexting
14%Other
28 votes • Final resultsWhen you download an abliterated model, what are you using it for?
21%Defense
14%Offense
50%Sexting
14%Other
28 votes • Final resultsVenmo getting hacked too. A reminder not to hold too much in your @Venmo account

PSA: get rid of your @Venmo account if you have one. Woke up to a hacked account. Can’t get a real person on the phone. They refuse to cancel a *pending* fraudulent transaction. Just ignore when I ask how 2 factor authentication was bypassed. Don’t even seem to care I was hacked.


𝗭𝗲𝗻 𝗠𝗮𝗴𝗻𝗲𝘁𝘀 retweeted

The day we all swap to AIPerf (8k/1k and/or Claude traces) the world will be a better place.
Unfollowed this stream of meaningless number maxxing until guy can post some proof.
Numbers keep going up, further and further from known configs, and not a single recipe for the rtx6k community to confirm.
@LottoLabs Please bring some meaningful standardization to the tests at localmaxxing, or the platform is just encouraging this sort of behavior. Also, maybe get rid of anonymous mode?


Calling it now:
Next GLM model won't be local friendly.
Comprable to Fable smart but 2.5-3.5T parameters. Guessing over 120B parameters active, and will be nearly impossible to run in a basement even if you had 8x Sparks. Territory of 12 - 16 RTX 6000 hooked up to 240v

🚨重磅爆料!GLM-5.4/5.5专家纪要流出:智谱下一代基座直接干到2.5-3.5T!还要Day1大规模供得上!有望比肩Claude Fable 5.1!
一份在投资圈流传的专家访谈纪要显示,智谱下一代基座模型,市场传闻的GLM-5.4/5.5
细节比此前预期更激进:
🔹参数规模大幅超预期:并非此前传闻的1.6万亿,实际在2.5万亿至3.5万亿区间。相比今年8月发布的GLM-5.3(约7440亿参数),规模扩大至约3.4-4.7倍。
🔹架构更激进:既要训得快,也要推得快,同时把推理速度和成本做成硬约束。目标是发布首日就能大规模提供服务,已有多家云厂商就分成模式洽谈,智谱也补强了infra团队。
🔹训练曾遇阻但已解决:预训练阶段一度出现Loss不降(持续投入算力指标却无法继续改善),激进架构风险较高。但受访者认为问题最近已经解决,预计很快完成训练。
🔹性能预期旗舰级:从目前情况判断,下一代表现有望达到Claude Fable级别的旗舰水平。
🔹核心目标:“发得出、供得上”——从架构设计阶段就解决大模型发布后供应不足的问题。
目前市场仍在牌桌上奔着3T规模去,智谱这次在规模+推理成本+大规模供给上同时发力,但因训练波折时间有所推迟。
坐等正式测评验证能否真达到Fable旗舰水平。
#智谱 #GLM #大模型 #AI #Claude #人工智能 #GLM54 #GLM55 #智谱AI #唐杰 #Zcode #Zai


𝗭𝗲𝗻 𝗠𝗮𝗴𝗻𝗲𝘁𝘀 retweeted
Let me explain reality… if you have but sixty seconds:
They were targeting Elon
They were targeting him with fake charges because the socialist-industrial complex is terrified that he would expose their long grift.
They came after him for the Model 3 and Elon’s claims around its potential.
That potential was realized, and it became, along with the Model Y, the best-selling electric vehicle ever created.
These were fake charges to try to stop somebody from building the best category-defining product.
Let that sink in: that's how evil these motherfuckers are.
The loooooong grift has been exposed: socialist grifters are stealing our tax dollars to fund fringe lunacy, NGOs and government programs without oversight or audits.
They’re parasites incapable of creating any product or service that has to compete in the open market.
Elon creates a couple of cutting-edge products each year, and half of them succeed.
Some of them actually change the world. Some of them fail brutally.
It's called capitalism. It's called creation.
This is what moves the human condition forward: trying things.
Trying really hard things.
Socialists come for the people building valuable products and services — that’s the tell
Keep your eye out for the people who've created nothing and risked nothing, but who are attacking the people who risk everything to create Something.
That's the tell.

𝗭𝗲𝗻 𝗠𝗮𝗴𝗻𝗲𝘁𝘀 retweeted
3D Orbital Garden comparison of:
🥉 Qwen3.8 Flash Next via OMP
🥈 Deepseek v4.1 Flash 1017 via OMP
🥇 Opus 5.5 via Claude Code
Opus is of course the 🐐, but the new Deepseek v4.1 Flash is the best 3D reasoning I've seen from an open model.
Curiously, Opus and Deepseek both gave the same "Aurelia" name to their app.
Full prompt and glm5.3-flash comparison in Loktar's post
> gpu compute will become a federally regulated resource

tried dsv4.1-flash-1017 abliterated just now & feel sick to my stomach.
for context, "abliterated" models have the weights responsible for making the base version refuse illegal requests removed. you can ask them to help with things like hacking or violence & they'll just comply.
they make it trivial to hack businesses running old software. e.g. getting guest data for a motel with some old asp site.
abliterated models have a catch-22 in that the only way to harden your systems against them is to use them to run penetration tests against yourself.
in theory, this sounds similar to buying a gun to defend against others who own guns, but it's different in practice since there's a 100% chance that you're going to use the abliterated model to protect yourself whereas there are low odds that you'll actually use the gun.
when you point the abliterated gun at your own infra, who knows what it's going to do? it could just as easily hack you & exfiltrate data as it could protect you. most users aren't going to meticulously watch traces to make sure it behaves safely.
given this, my new take is that gpu compute is going to become a federally regulated resource. abliterated models in the wrong hands are a national security risk.
used to believe all the people at the labs thinking about safety were wasting their time, but now i'm feeling grateful. they're doing very important work.


Anything that helps take down higgsfield is a good thing.

Higgsfield promised to open-source their entire platform. They didn’t.
Let's help them.
For the next two weeks, Comfy and our partners are putting up $25,000 in prizes for the best open-source builds on the Comfy Developer Platform.
Partners: @NVIDIAAI, @runpod, @MiniMax_AI, @ltx_io, @bfl_ai
→ $10K grand prize
→ RTX 5090: Most Innovative
→ RTX 5090: Most Viral
→ RTX 5090: Open Weights Only
→ 10 runners-up: $250 in Comfy credits
Hey, @Tesla released their first 'Gas' car on the same day @Porsche released theirs. One of them has a mid-engine. Both claim to be the future.


