

Scaler | Backend Engineer | Distributed Systems • APIs • Scalability
Joined December 2025
- Tweets4.2K
- Following962
- Followers1.2K
- Likes3.9K


Roughly 140 GB of VRAM if you keep fp16, but most teams shard across 8 to 12 A100 40 GB cards or use 4-bit quantization to drop it below 80 GB.

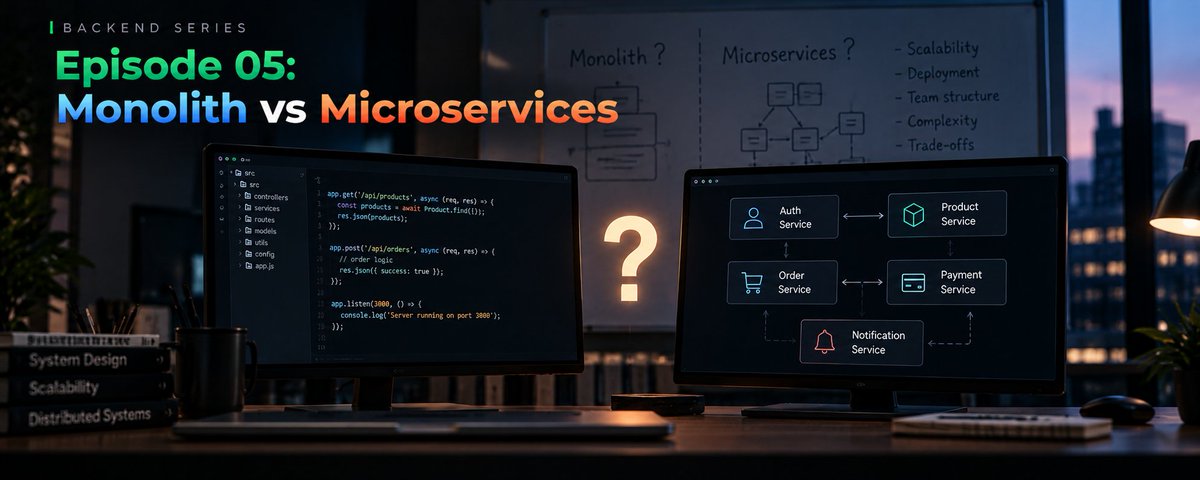
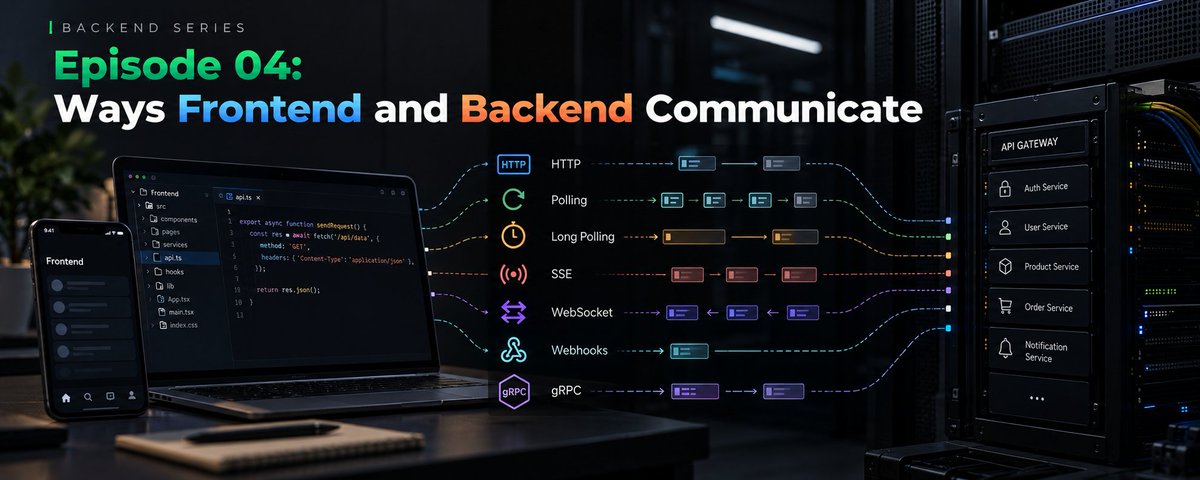
AI can speed up the build, but the deep understanding you gained lets you troubleshoot, design, and innovate where the model can’t. Your years still matter.
Devdeep retweeted

bro asked claude for an office and got a whole GTA side quest 💀

I asked Claude to build an office for the @tavus PALs...
I was not expecting it to build THAT kind of office
Devdeep retweeted
We’re now a family of 350 people on here!
Thank you to everyone who followed, engaged, and supported D3 Bytes. Every single one of you means a lot!
If you’re into tech, backend engineering, databases, or system design, let’s connect and grow together.
350 today. Bigger things ahead.


Use a distributed cache like Redis to store the restaurant list for the area and set a TTL of a few minutes. All 100k requests hit the cache, not the DB.
I'd add read replicas, cache hot data in Redis, paginate results and keep the API stateless so the DB stays light.
